Generate speech with customizable voices in any language, and create captivating stories using natural-sounding voices.

Google Cloud Text-To-Speech
0Popularity
About Google Cloud Text-To-Speech
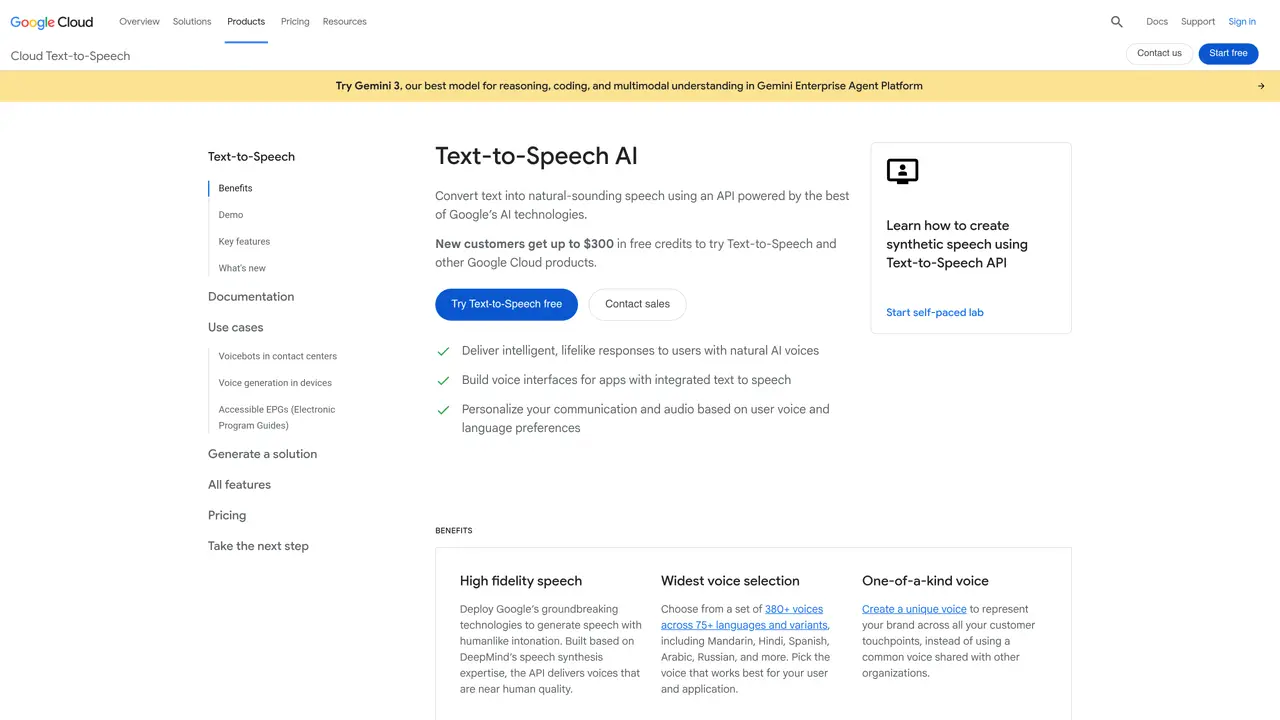
Google Cloud Text-to-Speech is a cloud-based service that converts text into natural-sounding speech using advanced neural network models. The tool supports a wide range of languages, dialects, and voices, including WaveNet voices that deliver highly realistic and expressive audio output. Users can customize speech parameters such as pitch, speed, and volume to tailor the audio to their specific needs. The service integrates seamlessly with other Google Cloud products, enabling developers to embed text-to-speech capabilities directly into applications, websites, or workflows. It is designed for scalability and reliability, making it suitable for both small-scale projects and large enterprise deployments. Common use cases include generating voiceovers for videos, creating interactive voice responses for customer service systems, and enhancing accessibility features in digital products. The platform also prioritizes security and compliance, ensuring that sensitive data processed through the service is handled with appropriate safeguards.
Key features
- Convert text into natural sounding speech
- Create lifelike audio from written text
- Add voice elements to podcasts and videos
- Access a variety of high-quality voices and languages
- Create custom audio experiences tailored to user needs
- Secure and reliable service for creating projects with confidence
Use cases
- Creating podcasts with lifelike audio from text
- Adding speech elements to videos
- Generating custom audio experiences with high-quality voices
Pros
- Offers lifelike AI voices with natural intonation and expressiveness
- Supports a wide range of languages and voice types, including WaveNet and Neural2 models
- Integrates seamlessly with Google Cloud services and APIs for scalable deployment
- Provides customizable speech synthesis with SSML support for precise control
- Delivers high-quality audio output suitable for applications, media, and accessibility needs
Cons
- Requires Google Cloud account and billing setup for usage
- May involve latency for real-time applications depending on network conditions
- Limited offline functionality compared to some local text-to-speech solutions
Frequently asked questions about Google Cloud Text-To-Speech
What is Google Cloud Text-to-Speech?
Google Cloud Text-to-Speech is a cloud-based service that converts text into natural-sounding speech using advanced AI models. It supports multiple languages and voice types, enabling users to generate lifelike audio for applications, videos, and other digital content.
Who should use Google Cloud Text-to-Speech?
The tool is designed for developers, content creators, and businesses looking to integrate high-quality speech synthesis into their projects, such as voice assistants, audiobooks, or multimedia applications.
How does Google Cloud Text-to-Speech work?
Users input text into the service, which processes it using neural networks to produce natural-sounding audio. The output can be downloaded or streamed directly into applications.
What languages and voices are supported?
The service supports a wide range of languages and dialects, including neural and standard voices, allowing users to select the most suitable option for their needs.
Can Google Cloud Text-to-Speech be integrated with other tools?
Yes, it offers APIs and SDKs for seamless integration with various platforms, applications, and workflows, including Google Cloud services and third-party systems.
How do I get started with Google Cloud Text-to-Speech?
Users can begin by enabling the Text-to-Speech API in the Google Cloud Console, accessing documentation, and using provided code samples to integrate the service into their projects.