Generate speech with customizable voices in any language, and create captivating stories using natural-sounding voices.

Qwen Audio 3.0 TTS
FreeStarting price
0Popularity
About Qwen Audio 3.0 TTS
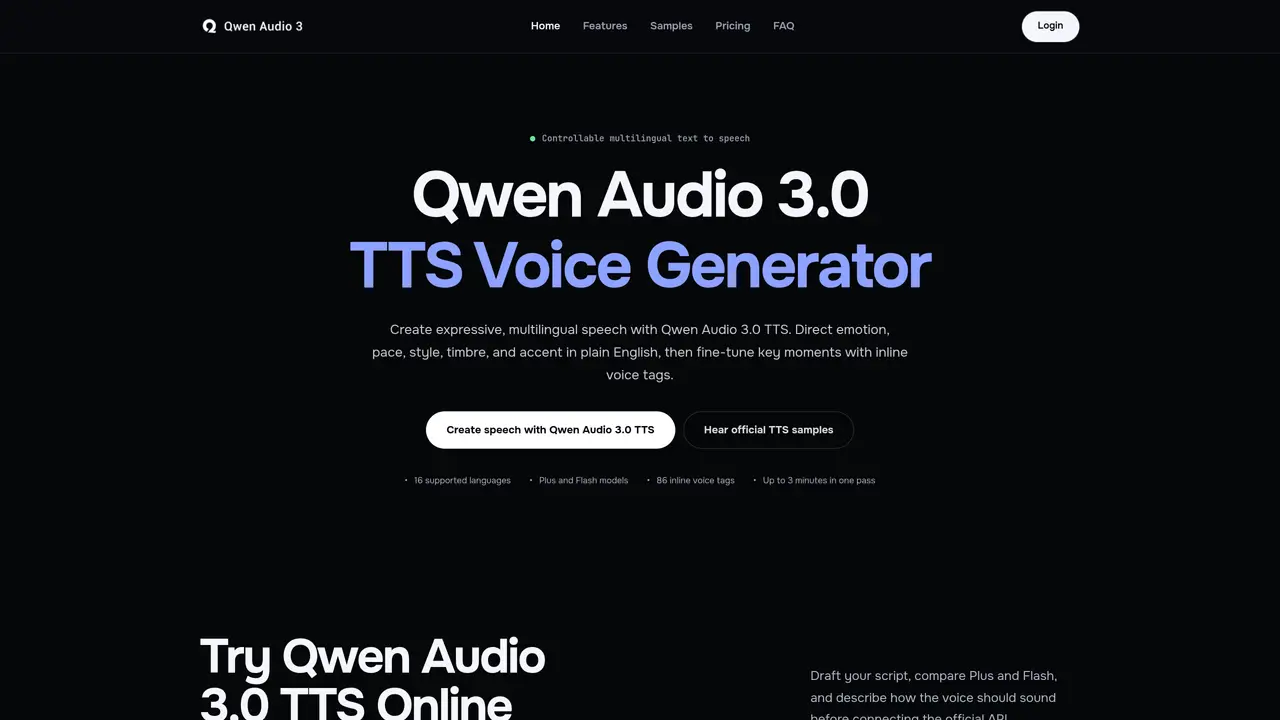
Qwen Audio 3.0 TTS is an AI text-to-speech system designed for natural, controllable, and multilingual voice generation. It allows users to direct delivery in plain language, refine specific moments with inline tags, and create longer speech from text or reference audio. The system offers two models: Plus for quality-first production and Flash for latency-sensitive interactions. Users can control overall role, emotion, pace, timbre, style, and accent through natural-language instructions, while 86 inline tags enable precise adjustments for pauses, laughter, breathing, and other expressive elements. The tool supports 16 languages and provides commercial usage rights with high-quality audio downloads in MP3, WAV, PCM, and Opus formats. It is typically used for voiceovers, dialogue, audiobooks, podcasts, film dubbing, and localized speech without manual acoustic tuning.
Key features
- Natural-language voice direction
- 86 inline voice tags for expressive control
- Multilingual text-to-speech in 16 languages
- Plus and Flash model options
- Reference-based voice cloning
- Long-form narration support
- Adjustable volume, speaking rate, and pitch
- Multiple audio format outputs (MP3, WAV, PCM, Opus)
Use cases
- Professional voiceovers and narration
- Multilingual audiobook production
- Interactive voice assistants and chatbots
Pros
- Natural-language voice control for emotion, pace, timbre, and accent
- 86 inline tags for fine-grained expressive control
- Supports 16 languages and cross-lingual speech
- Two models: Plus for high quality, Flash for low latency
- Commercial usage rights included with paid plans
Cons
- Requires official API connection for full functionality
- No free tier beyond 5 trial credits
- Maximum 3 minutes of speech per generation in one pass
Frequently asked questions about Qwen Audio 3.0 TTS
What is Qwen Audio 3.0 TTS?
Qwen Audio 3.0 TTS is an AI text-to-speech system designed for natural, controllable, and multilingual voice generation. It allows users to direct voice delivery using plain-language instructions and refine specific moments with 86 inline tags for expressive elements like pauses, laughter, or breathing.
Who is Qwen Audio 3.0 TTS suitable for?
The tool is suitable for content creators, developers, and businesses needing high-quality voiceovers, dialogue, audiobooks, podcasts, film dubbing, or localized speech. It caters to both professional production workflows and latency-sensitive interactive applications.
How does the pricing model work for Qwen Audio 3.0 TTS?
The tool offers two models: Plus for quality-first production and Flash for latency-sensitive interactions. Pricing is based on usage, with commercial usage rights included and high-quality audio downloads available in multiple formats.
What integrations does Qwen Audio 3.0 TTS support?
Qwen Audio 3.0 TTS requires an official API connection for integration. It supports multilingual speech generation across 16 languages and allows users to draft scripts, compare models, and fine-tune outputs before connecting to the API.
What are the limitations of Qwen Audio 3.0 TTS?
The tool currently supports up to 3 minutes of speech generation in one pass. Users must connect to the official API for full functionality, and advanced voice control features may require additional setup or scripting.
How do I get started with Qwen Audio 3.0 TTS?
Users can start by drafting a script, selecting between the Plus or Flash model, and describing the desired voice characteristics in plain language. The tool provides a voice studio interface for comparison and fine-tuning before generating speech via the API.