OpenAI builds and deploys advanced AI models like GPT-4o for autonomous agents and workflows.
UseTokenSaver
0Popularity
About UseTokenSaver
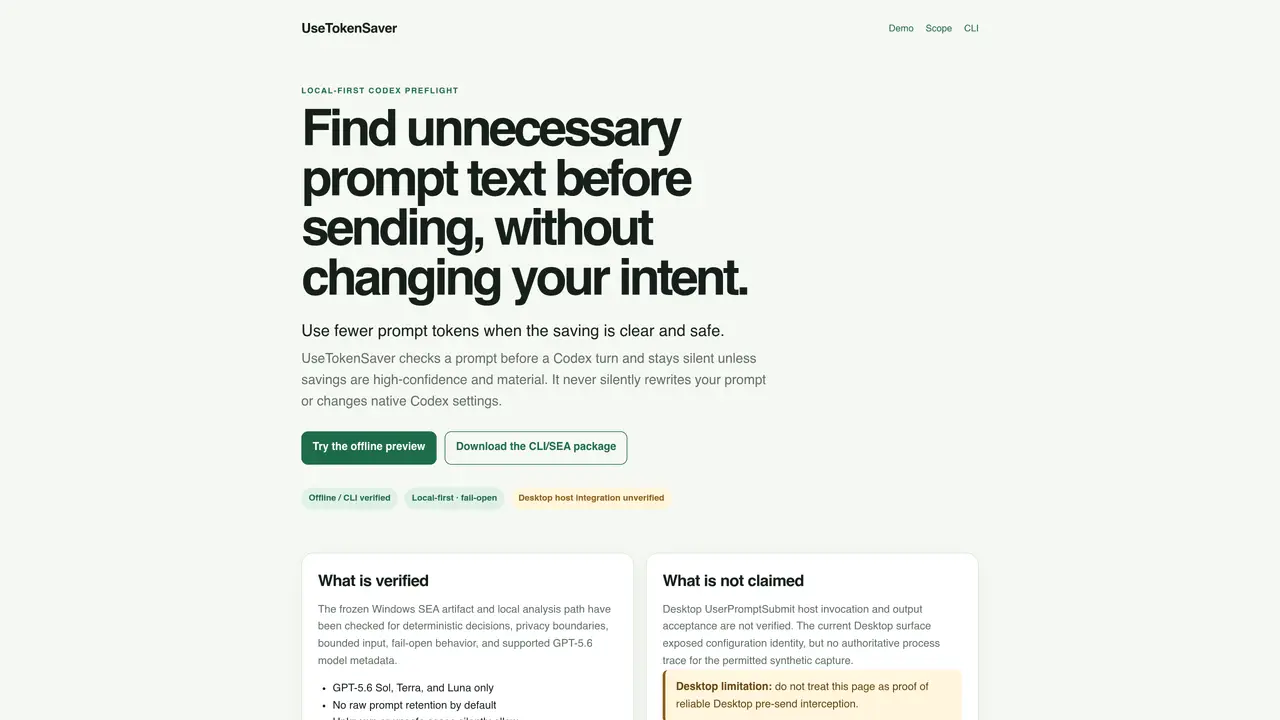
UseTokenSaver is a local-first tool designed to analyze prompts before they are sent to Codex models. It operates as a preflight check, identifying unnecessary prompt text that can be removed without changing the user’s intent or the expected output. The tool remains silent unless it detects high-confidence, material savings in token usage. It does not rewrite prompts or alter native Codex settings. UseTokenSaver is available as a self-contained Windows executable and integrates with local Codex environments via a CLI hook. The tool focuses on deterministic decisions, privacy boundaries, and bounded input, supporting only GPT-5.6 Sol, Terra, and Luna models. It is designed to fail open, allowing unmodified prompts to proceed if savings cannot be confidently determined. The offline preview feature allows users to test synthetic decision cases locally in a browser without sending data to a model.
Key features
- Preflight prompt analysis before Codex submission
- High-confidence material savings detection
- Silent operation unless savings are proven
- Fail-open behavior for unmodified prompt processing
- Offline preview with synthetic decision fixtures
- CLI hook integration for local Codex environments
- Bounded JSON envelope input/output
- Deterministic decision-making with privacy boundaries
Use cases
- Reducing token usage in prompts for cost efficiency
- Preflight checks before sending prompts to Codex models
- Local testing of prompt optimization without model exposure
Pros
- Local-first operation with no raw prompt retention by default
- Silent unless material token savings are detected
- Fail-open behavior ensures prompts proceed if savings are unclear
- Supports GPT-5.6 Sol, Terra, and Luna models
- Self-contained Windows executable with deterministic decisions
Cons
- Desktop host integration is unverified
- No verified recommendation for model, reasoning effort, and speed optimization
- Limited to Windows platform
- No public prompt or session metadata collection, but Desktop evidence gaps remain
Frequently asked questions about UseTokenSaver
What does UseTokenSaver do?
UseTokenSaver acts as a local-first preflight check for prompts before they are sent to Codex models. It identifies unnecessary prompt text that can be removed without altering the user’s intent or expected output, helping reduce token usage when savings are high-confidence and safe.
Who is UseTokenSaver designed for?
The tool is designed for users working with GPT-5.6 Sol, Terra, and Luna models in local Codex environments. It is particularly useful for those who want to optimize token usage while maintaining privacy and deterministic decisions.
How does UseTokenSaver integrate with Codex?
UseTokenSaver integrates via a CLI hook in local Codex environments. It reads a bounded JSON envelope from stdin and emits a validated decision only when it can confidently recommend material token savings. The tool fails open if savings cannot be determined.
Can UseTokenSaver be used offline?
Yes, UseTokenSaver offers an offline preview feature that allows users to test synthetic decision cases locally in a browser without sending data to a model. The CLI/SEA package is also designed for offline use.
Does UseTokenSaver change native Codex settings?
No, UseTokenSaver does not rewrite prompts or alter native Codex settings. It operates as a silent preflight check, intervening only when high-confidence savings are detected.
What models does UseTokenSaver support?
UseTokenSaver currently supports GPT-5.6 Sol, Terra, and Luna models. It does not provide verified recommendations for model, reasoning effort, or speed combinations beyond these.