Cloud platform for web scraping, browser automation, and AI data extraction with 20,000+ pre-built tools and scalable cloud runs.
Crawly
$1Starting price
0Popularity
About Crawly
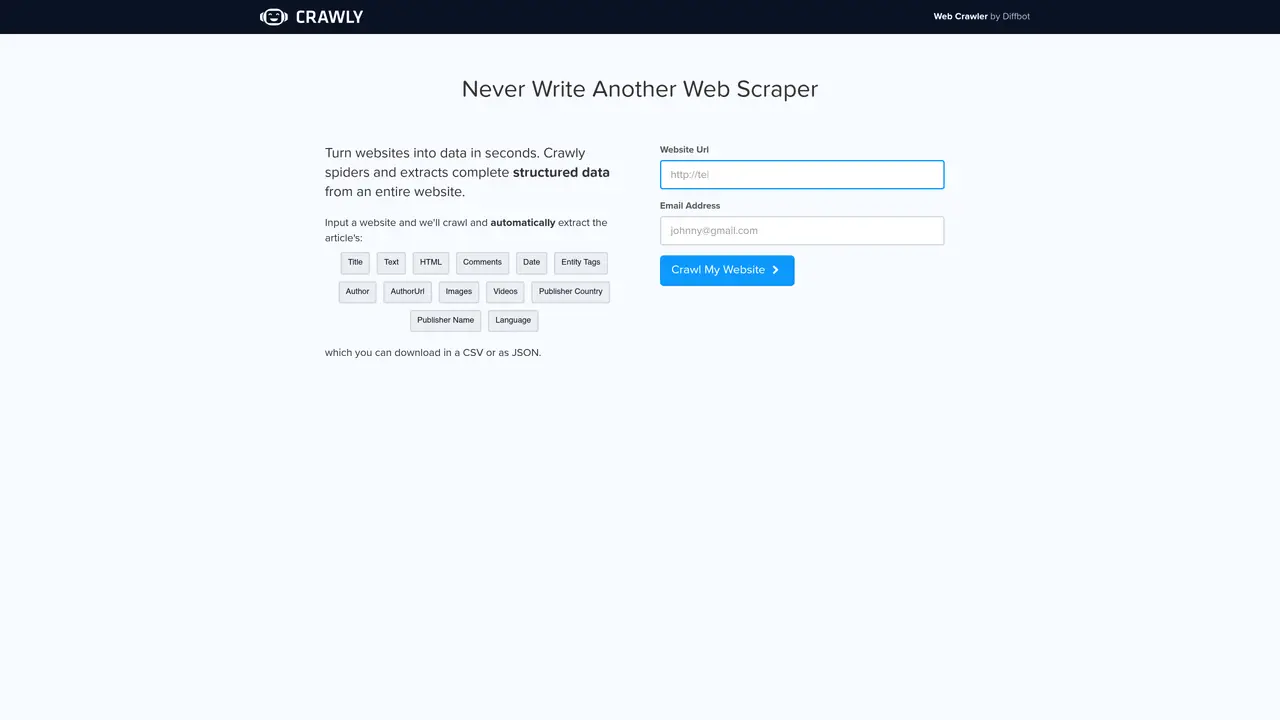
Crawly is an AI-powered web crawling and data extraction service designed to help users quickly and accurately gather valuable insights from the web. The platform enables users to capture data from millions of websites in various formats, including HTML, JSON, and CSV, making it versatile for different data needs. Crawly leverages advanced AI technology to ensure fast and precise data collection, reducing manual effort and improving efficiency for large-scale web scraping tasks. Its intuitive filtering capabilities allow users to narrow down search results, making it easier to locate specific data points across extensive websites. The tool is particularly well-suited for data scientists, marketers, researchers, and web developers who require reliable and scalable web data extraction solutions. By automating the process of data collection and filtering, Crawly streamlines workflows and enables users to focus on analysis and decision-making rather than manual data gathering.
Diffbot
Menlo Park, United States · Founded 2011
- Founder
- Mike Tung
- Founded
- 2011
- Headquarters
- Menlo Park, United States
Key features
- AI-powered web crawling for fast and accurate data extraction
- Supports multiple output formats including HTML, JSON, and CSV
- Intuitive filtering to narrow down search results efficiently
- Scalable solution for capturing data from millions of websites
- Designed for data scientists, marketers, researchers, and developers
- Advanced AI technology for reliable and precise data collection
- Easy-to-use interface for filtering and searching extracted data
- Automates repetitive web scraping tasks to save time
Use cases
- Collecting market research data from competitor websites
- Extracting product information for price comparison and analysis
- Gathering structured data from news sites or blogs for content aggregation
Pros
- Automatically extracts structured data from entire websites without requiring manual scraping scripts
- Supports output formats including CSV and JSON for easy integration with data analysis tools
- Captures multiple content types such as articles, images, videos, and metadata
- Reduces manual effort by handling crawling and extraction in a single automated process
- Provides entity tags, dates, authors, and publisher information for enriched data
Cons
- Limited to websites Crawly can successfully parse, as it relies on Diffbot's extraction technology
- May not capture dynamic or JavaScript-rendered content without additional configuration
- Requires input of a specific website URL, limiting broad web-wide crawling capabilities
Frequently asked questions about Crawly
What does Crawly do?
Crawly is a web crawler that automatically extracts structured data from entire websites, including articles, images, videos, and metadata, and outputs the results in formats like CSV or JSON.
Who is Crawly suited for?
Crawly is designed for users who need to convert website content into structured data, such as researchers, marketers, data scientists, and developers who require reliable and scalable web data extraction.
How does Crawly work?
Users input a website URL, and Crawly automatically crawls the site, extracts structured data such as titles, text, dates, and entity tags, and provides the results in downloadable formats like CSV or JSON.
Can Crawly extract data from any website?
Crawly can extract data from websites supported by Diffbot's extraction technology, but it may not capture dynamic or JavaScript-heavy content without additional configuration.
What types of data can Crawly extract?
Crawly extracts article titles, text, HTML comments, dates, entity tags, authors, images, videos, publisher information, website URLs, and email addresses.
How do I get started with Crawly?
To get started, input the URL of the website you want to crawl, and Crawly will automatically extract and structure the data for download in your preferred format.