Cloud platform for web scraping, browser automation, and AI data extraction with 20,000+ pre-built tools and scalable cloud runs.
PDFParser
$9Starting price
456Monthly visits
0Popularity
About PDFParser
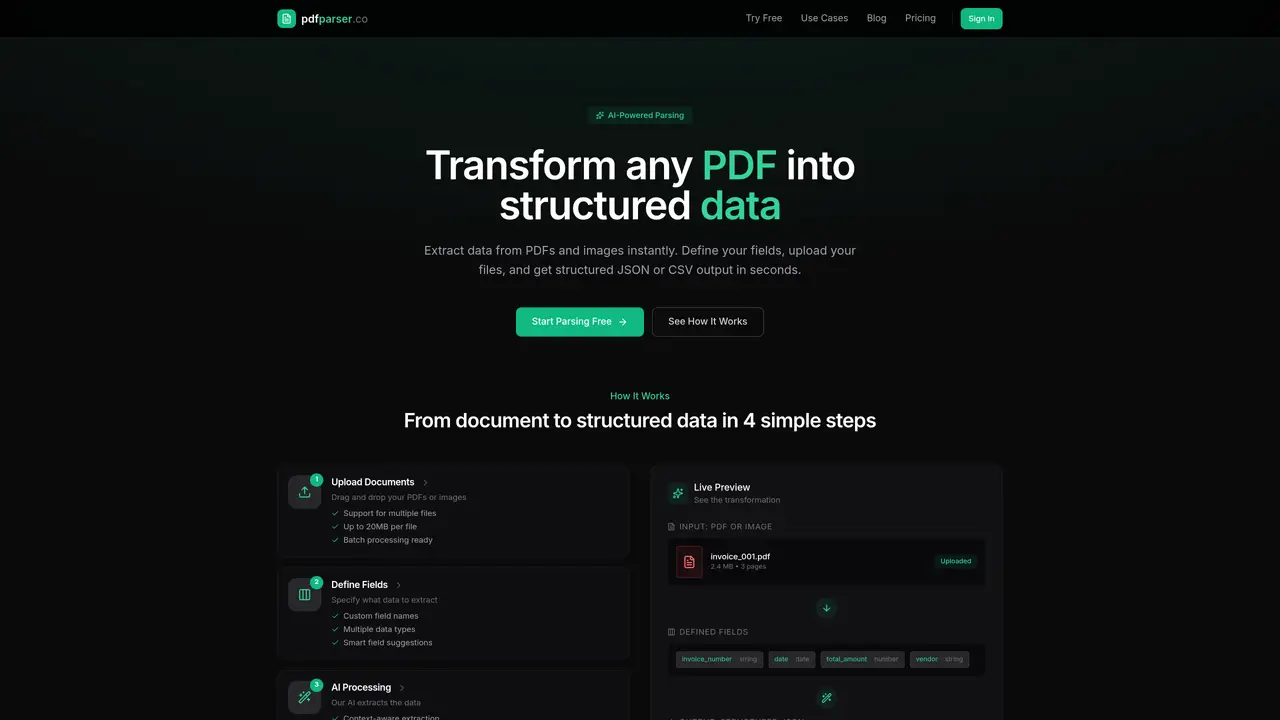
PDFParser is a tool that revolutionizes the process of parsing PDF documents by effortlessly converting them into a convenient JSON format. This eliminates the tedious and time-consuming manual intervention required in traditional methods. With PDFParser, you can parse several documents like invoices, resumes, tickets, emails, etc. It’s designed to extract data from unstructured PDFs, making it easier to work with large volumes of documents. The tool is suitable for various use cases, including parsing thousands of unstructured invoices and exporting them as CSV, or extracting skills and experience from resumes. PDFParser works by converting PDF documents into a JSON format, allowing users to easily extract data and export it as CSV. This process streamlines the workflow, saving time and increasing accuracy. The tool is particularly useful for businesses that need to handle large volumes of unstructured documents, such as invoices, resumes, or tickets.
Key features
- Parse PDF documents into JSON format
- Extract data from unstructured PDFs
- Export data as CSV
- Suitable for parsing thousands of invoices and exporting them as CSV
- Extract skills and experience from resumes
- Streamline workflow by automating data extraction
Use cases
- Parsing thousands of unstructured invoices and exporting them as CSV
- Extracting skills and experience from resumes
- Automating data extraction from large volumes of documents
Pros
- Supports multiple file formats including PDFs, images, and scanned documents
- Offers AI-powered extraction with high accuracy for structured and unstructured layouts
- Provides flexible output options with JSON or CSV formats for easy integration
- Includes batch processing and parallel processing for handling multiple documents simultaneously
- Secure processing with no permanent storage of uploaded documents and HTTPS encryption
Cons
- Maximum file size limit of 20 MB per upload
- Free tier has limited pages (20) and unused pages expire monthly
Frequently asked questions about PDFParser
What types of documents can PDFParser handle?
PDFParser supports PDFs, JPEGs, PNGs, WebP, TIFF, BMP, and GIF files. Common use cases include invoices, receipts, bank statements, contracts, insurance claims, medical records, and HR documents.
How accurate is PDFParser's document-to-JSON conversion?
PDFParser uses GPT-4-class vision models for context-aware extraction, delivering high accuracy on structured documents like invoices and receipts. Results depend on document quality, with clean, machine-generated PDFs yielding the best output.
Can I customize the parsing output to fit my specific needs?
Yes. Users define the exact fields required—field names, data types (string, number, date, boolean), and descriptions. PDFParser extracts only the specified data, returning clean JSON or CSV for direct integration into workflows.
Do I need any technical skills to use PDFParser?
No technical skills are required. The web interface allows users to upload files, define fields, and download results in three clicks. A REST API is also available for developers with full documentation and integration examples.
Is my data secure when using PDFParser?
Yes. PDFParser does not store uploaded documents after processing. File transfers use HTTPS encryption, and document processing is handled via OpenAI's API, which does not use customer data for model training.
Are there file size limitations for uploads?
Yes. The maximum file size is 20 MB per upload, covering most business documents. Batch uploads of multiple files are supported on all plans.
PDFParser Website Engagement
Last Update: 9 days ago
Total Monthly Visits
0
Bounce Rate
—
Visit Duration (avg)
—
Pages Per Visit
—
Country Rank
—
Unknown
Global Rank
0