Cloud platform for web scraping, browser automation, and AI data extraction with 20,000+ pre-built tools and scalable cloud runs.

Scrapeless
$0.40Starting price
101KMonthly visits
33Popularity
About Scrapeless
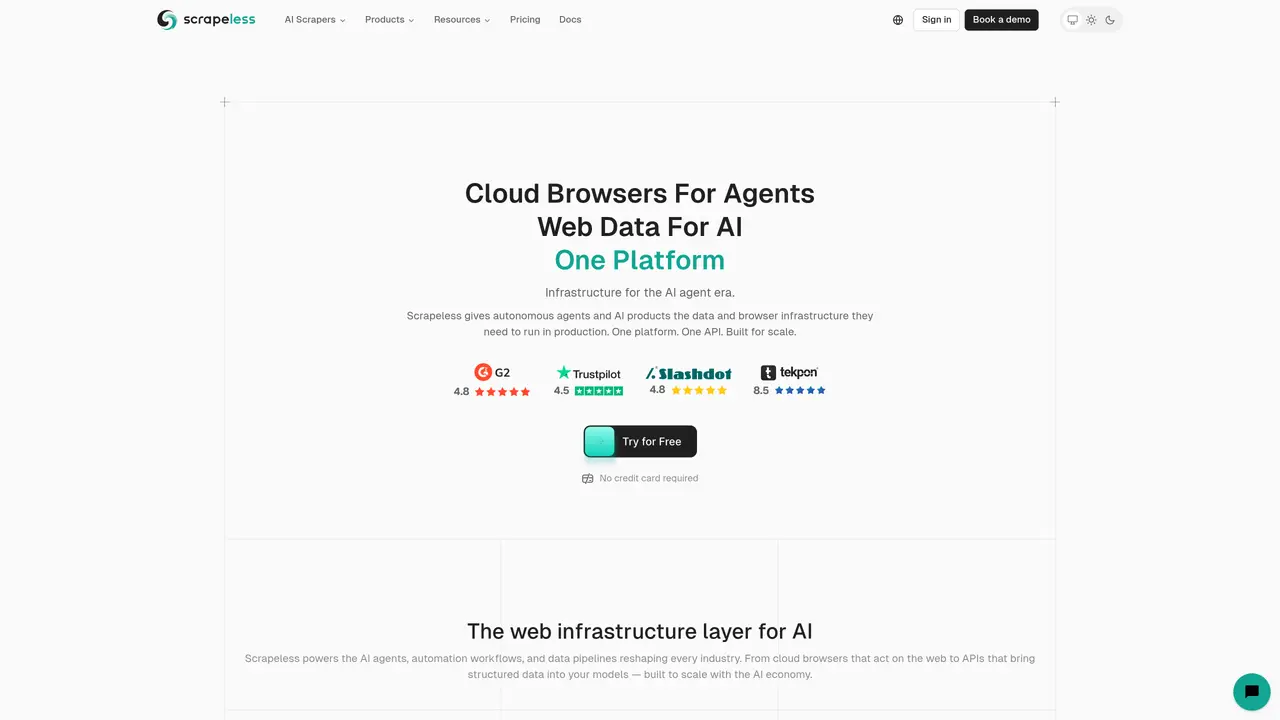
Scrapeless is a web scraping toolkit designed for developers and businesses that require dependable extraction of public web data. It provides a universal scraping API capable of handling JavaScript rendering, automatic IP rotation, anti-blocking features, and structured output formats like JSON or CSV. The platform includes a cloud browser infrastructure for automating dynamic page extraction, featuring anti-detection controls, fingerprint isolation, high concurrency, and compatibility with Puppeteer and Playwright. Additional capabilities include a CAPTCHA solver to bypass common security challenges during crawling, as well as proxy solutions with residential, ISP, datacenter, and IPv6 options for geo-targeted access. The integrated stack combines API, cloud browser, CAPTCHA solving, and proxy infrastructure to support dynamic websites and anti-bot defenses, with options for customized enterprise services and dedicated support. The service operates on a pay-per-successful-extraction model, making it cost-effective for users who only pay for extracted data.
Key features
- Universal Scraping API with JavaScript rendering and anti-blocking features
- Cloud browser automation with anti-detection controls and fingerprint isolation
- CAPTCHA solver for bypassing bot defenses during crawling
- Proxy solutions with residential, ISP, datacenter, and IPv6 options
- Geo-targeting for location-specific data access
- Structured output formats (JSON, CSV) for easy data integration
- Compatibility with Puppeteer and Playwright for automation
- High concurrency for scalable web scraping operations
- Pay-per-successful-extraction pricing model
- Enterprise-grade support and customized services
Use cases
- Extracting public product data from e-commerce websites for market research
- Monitoring competitor pricing and promotions in real time
- Automating data collection from dynamic websites with anti-bot protections
Pros
- Unified platform combining cloud browsers, scraping APIs, CAPTCHA solvers, and proxy solutions for comprehensive web data extraction
- Supports dynamic content via JavaScript rendering, anti-detection controls, and fingerprint isolation for reliable scraping
- Offers specialized tools for AI agents, LLM monitoring, and enterprise workflows with persistent profiles and MFA handling
- Pay-per-successful-extraction model reduces costs by charging only for usable data
- Compatible with popular frameworks like Puppeteer and Playwright for developer flexibility
Cons
- May require technical expertise to fully utilize advanced features like persistent profiles and session replay
- Limited transparency on exact success rates or performance metrics for CAPTCHA solving and anti-blocking
- Enterprise-focused pricing and support may not suit small-scale or individual users
- Dependence on third-party infrastructure introduces potential reliability risks during outages
Frequently asked questions about Scrapeless
What is Scrapeless and who is it designed for?
Scrapeless is a unified web infrastructure platform providing cloud browsers, scraping APIs, and proxy solutions for AI agents, automation workflows, and data pipelines. It is designed for AI-native startups, enterprises, and developers who need reliable web data extraction, browser automation, and anti-bot bypass capabilities.
How does Scrapeless handle dynamic websites and anti-bot defenses?
Scrapeless combines browser fingerprinting, CAPTCHA solving, IP rotation, and smart retries within a single API to bypass anti-bot measures and render JavaScript-heavy pages. Its cloud browsers support real browser environments, MFA handling, and persistent sessions for reliable automation.
What scraping products does Scrapeless offer?
Scrapeless provides four main products: Agent Browser for cloud-based browser automation, AI Scrapers for extracting structured data from AI engines, Web Unlocker for rendering and extracting content from URLs, and Crawl LLM-READY for recursive website crawling into structured formats.
Does Scrapeless support integration with AI agents and workflows?
Yes, Scrapeless is built for AI agent workflows, offering Puppeteer and Playwright compatibility, persistent profiles, session replay, and real-time debugging. It enables agents to fill forms, book appointments, and navigate logged-in or MFA-gated websites at scale.
What proxy solutions does Scrapeless provide?
Scrapeless offers a standalone proxy network with residential, ISP, datacenter, and IPv6 IPs spanning 195+ countries. It supports geo-targeting, HTTP/HTTPS/SOCKS5 protocols, and sub-0.5s average response times for reliable, low-latency scraping.
How does Scrapeless pricing work?
Scrapeless operates on a pay-per-successful-extraction model, where users pay only for successful requests. This cost-effective approach applies across its products, including Web Unlocker, Crawl LLM-READY, and AI Scrapers, with no upfront infrastructure costs.
Scrapeless Website Engagement
Last Update: 9 days ago
Total Monthly Visits
0
Bounce Rate
0%
Visit Duration (avg)
0.00s
Pages Per Visit
0
Country Rank
0
United States
Global Rank
0
Category Rank
#0
Programming & Developer Software
Monthly Traffic
Traffic Sources
Traffic Share By Country
- India11.6%
- United States10.6%
- China8.8%
- Vietnam5.1%
- Brazil5%