AI chatbot for conversation, work, research, coding, and content creation.
MachGen
$0.00Starting price
0Popularity
About MachGen
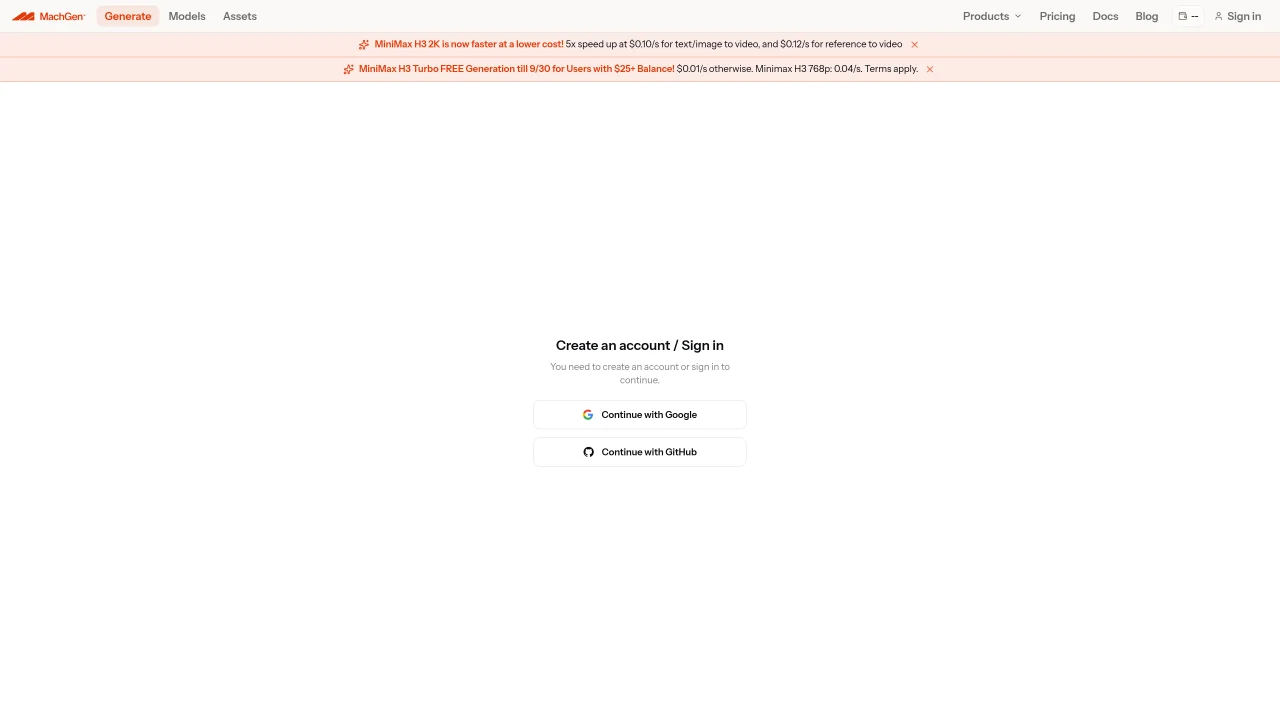
MachGen is an AI inference platform focused on making diffusion and video “world” models run much faster and cheaper in production. It speeds up popular open models for image and video generation while keeping the original weights and visual quality. The hosted playground at the MachGen Cloud endpoint lets teams try these models with prompts or reference images, then move to APIs and a growing managed inference platform for real products. Key Features: Accelerated Visual Models: Speeds up models like Wan 2.2, LTX 2.3, HiDream, Flux 2 Dev, and Vidu with published multi-X latency reductions at the same quality. MachGen Playground / Cloud UI: Hosted generation experience where users submit prompts or reference images and iterate quickly on image and video outputs using the MachGen runtime. APIs and Python Client: REST APIs plus an official machgen-client Python library with typed models, automatic file upload, and blocking or streaming result handling. GPU-Efficient Inference Platform: Kernel-level tuning, fused operators, and scheduling that aim to deliver more generations per GPU, with previews in seconds and zero-downtime failover. Deployment Flexibility: Support for running in MachGen’s cloud or a customer VPC, with a managed inference offering for hosting customer models currently in early access.
Key features
- Accelerated Visual Models
- MachGen Playground / Cloud UI
- APIs and Python Client
- GPU-Efficient Inference Platform
- Deployment Flexibility
- Pay-as-you-go pricing model
Use cases
- Generative product teams: Add fast image or video generation to consumer apps, from avatars to creative tools.
- Gaming and interactive studios: Use low-latency video models for in-game scenes and reactive visual effects.
- Adtech and marketing platforms: Render many variants of creative assets while keeping GPU bills contained.
Pros
- Accelerates popular open diffusion and video models without altering original weights or visual quality
- Provides a hosted playground for quick iteration on image and video generation using prompts or reference images
- Offers REST APIs and a Python client with typed models for seamless integration into workflows
- Delivers GPU-efficient inference with kernel-level optimizations and scheduling for higher throughput
- Supports deployment flexibility with options for cloud hosting or customer VPC environments
Cons
- Managed inference platform for hosting customer models is currently in early access
- Limited public information on specific performance metrics or pricing models for broader adoption
Frequently asked questions about MachGen
What is MachGen?
MachGen is an AI inference platform designed to accelerate diffusion and video world models for faster and more cost-effective production use. It maintains the original model weights and visual quality while improving performance.
Who should use MachGen?
MachGen is suitable for teams and developers working with image and video generation models who need faster inference, scalable deployment, and a managed platform for production use.
How does MachGen speed up models?
MachGen uses kernel-level tuning, fused operators, and optimized scheduling to reduce latency and increase throughput, enabling more generations per GPU without compromising quality.
Can I try MachGen before deploying it?
Yes, MachGen offers a hosted playground where users can test models with prompts or reference images before moving to APIs or a managed inference platform for production.
Does MachGen support deployment in my own environment?
MachGen provides deployment flexibility, allowing users to run models in its cloud or within their own VPC, with a managed inference offering available for hosting customer models.
What models does MachGen accelerate?
MachGen accelerates popular open models such as Wan 2.2, LTX 2.3, HiDream, Flux 2 Dev, and Vidu, among others, with published latency reductions at the same quality.