Create stunning visuals, develop ideas with AI-powered tools, and instantly share content without coding or formatting.
ClipClap
$1Starting price
0Popularity
About ClipClap
ClipClap is an innovative video curation tool that helps users create and share personalized collections of their favorite videos. It enables users to easily select and organize videos from a variety of sources, including YouTube, Vimeo, and Dailymotion, and add them to their own curated list. ClipClap also provides powerful search and sorting capabilities to help users find the videos they’re looking for quickly and easily. With ClipClap, users can create their own custom video library, complete with descriptions, tags, and categories. They can also share their collections with others, making it easy to collaborate on projects or simply share their favorite videos with friends and family. ClipClap also offers a convenient way to keep track of favorite videos, so users can quickly access them again later. The tool is designed for anyone who wants to build a structured, searchable archive of videos for personal use, team projects, or public sharing.
Key features
- Import videos from YouTube, Vimeo, and Dailymotion
- Create custom video collections with descriptions and tags
- Organize videos into categories
- Fast search and filtering across collections
- Share curated collections with others
- Save favorite videos for quick access
- Freemium pricing model
Use cases
- Building a personal video library for research or reference
- Collaborating on video-based projects with teams or clients
- Sharing curated video lists with friends, students, or followers
Pros
- Uses CLIP encoding for rich semantic visual understanding
- Combines pre-trained language models for coherent caption generation
- Requires minimal training for effective results
- Lightweight architecture with fewer trainable parameters
- Achieves competitive performance on standard image captioning benchmarks
Cons
- Limited to image captioning tasks
- Dependent on pre-trained CLIP and language models
- May struggle with highly specialized or niche visual contexts
Frequently asked questions about ClipClap
What is ClipCap and what does it do?
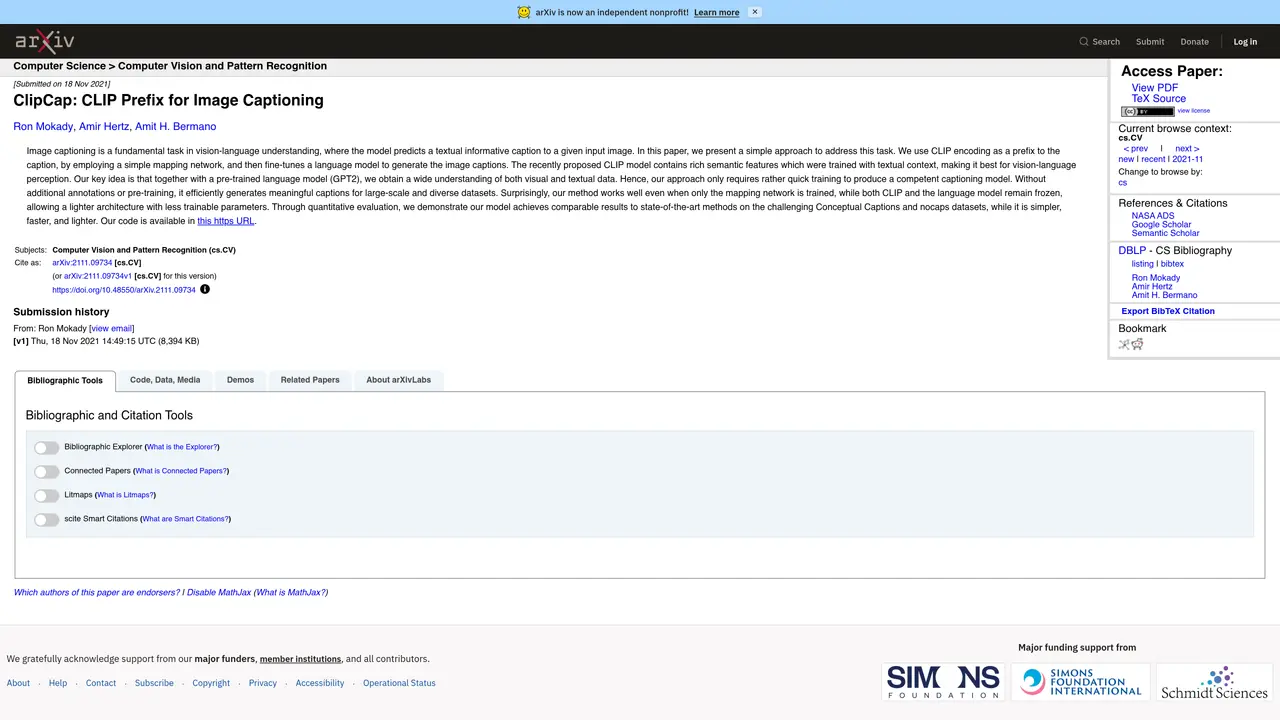
ClipCap is a method for image captioning that uses CLIP encoding as a prefix to generate textual descriptions for input images. It leverages a pre-trained language model to produce meaningful captions efficiently.
Who is ClipCap designed for?
ClipCap is designed for researchers, developers, and practitioners working in computer vision and natural language processing who need automated image captioning solutions.
How does ClipCap generate captions?
It uses a mapping network to transform CLIP image embeddings into a prefix for a language model, which then generates the caption. The architecture remains lightweight by freezing most components during training.
What datasets can ClipCap work with?
ClipCap has been evaluated on datasets such as Conceptual Captions and nocaps, demonstrating strong performance across diverse and large-scale visual content.
Does ClipCap require additional annotations?
No, ClipCap does not require additional annotations or extensive pre-training beyond the initial CLIP and language model setups.
Where can I access ClipCap's code or demos?
The code for ClipCap is available through the provided URL in the research paper, and demos can be found on platforms like Hugging Face Spaces and Replicate.