Generate speech with customizable voices in any language, and create captivating stories using natural-sounding voices.

FlowSpeech
$19/mStarting price
40KMonthly visits
27Popularity
About FlowSpeech
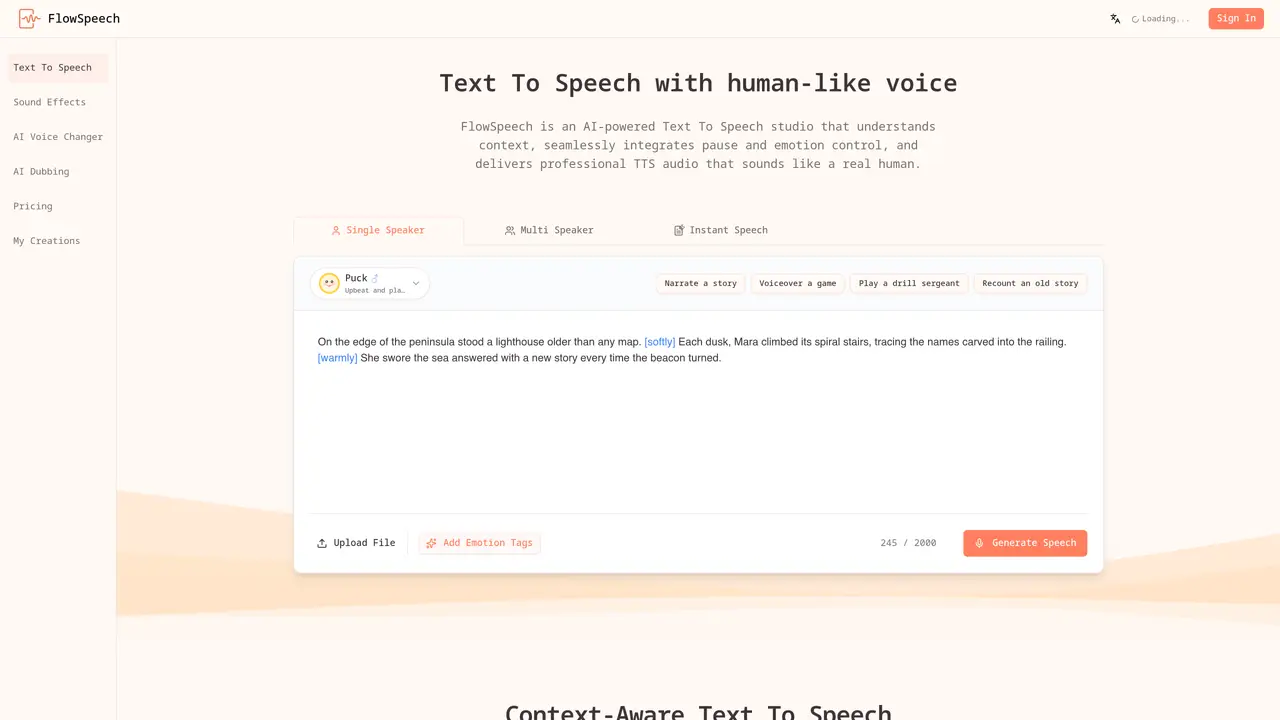
FlowSpeech is an AI-powered text-to-speech studio designed to transform written content into high-quality, human-like spoken audio. It processes text directly or extracts text from images and PDFs, then generates speech with natural intonation, pauses, and emotional inflection. The tool uses multimodal models to analyze context and trim irrelevant material, producing more expressive and lifelike audio than traditional text-to-speech systems. Creators, developers, and accessibility-focused users rely on FlowSpeech for tasks such as podcast production, audiobook narration, voiceovers, and app integration. By automating the conversion process, it significantly reduces the time and effort required to create professional-grade spoken content. The platform is accessible via a freemium model, offering a free tier for basic use while supporting advanced features for power users and developers.
Key features
- Converts text, images, and PDFs into speech
- Uses context-aware, multimodal models for natural intonation
- Adds pauses and emotional inflection to speech
- Trims irrelevant material for concise output
- Supports podcast, audiobook, and voiceover production
- Enables app integration via API
- Freemium pricing model with a free tier
- Produces more natural speech than traditional TTS systems
Use cases
- Creating podcast episodes from written scripts
- Generating audiobooks from text documents
- Producing voiceovers for videos or presentations
Pros
- Context-aware emotion and pause control for lifelike speech output
- Supports 70+ languages and 30 distinct voice styles across four categories
- Handles multi-speaker dialogue automatically with voice matching
- Directly processes text from PDFs, Word, PowerPoint, images, and other file formats
- Offers single, multi-speaker, and instant generation modes for flexibility
Cons
- Limited to 100,000 characters per render, which may require splitting longer projects
- No explicit mention of custom voice creation or cloning capabilities
- Advanced features may require a paid plan, restricting full functionality on the free tier
Frequently asked questions about FlowSpeech
What is FlowSpeech?
FlowSpeech is an AI-powered text-to-speech studio that converts written content into lifelike spoken audio with context-aware emotion, pause control, and multi-speaker support.
How does FlowSpeech differ from other text-to-speech tools?
It uses context-aware models to analyze sentiment, timing, and nuance, allowing for natural emotional delivery and precise pause control without post-production editing.
Can I use FlowSpeech for commercial projects?
Yes, generated audio can be used commercially, though specific licensing terms should be reviewed in the platform's terms of service.
How do I add pauses or emotions to my text?
Use tags like [⌛1.0s] for pauses or [whisper]/[shout] for emotions directly in the script to guide the AI's delivery.
Does FlowSpeech support custom voices?
The platform does not explicitly mention custom voice creation or cloning features in its public documentation.
Is my data safe when using FlowSpeech?
FlowSpeech states data safety measures are in place, but users should review the privacy policy for specific details on data handling and storage.
FlowSpeech Website Engagement
Last Update: 9 days ago
Total Monthly Visits
0
Bounce Rate
0%
Visit Duration (avg)
0.00s
Pages Per Visit
0
Country Rank
0
United States
Global Rank
0
Monthly Traffic
Traffic Sources
Traffic Share By Country
- United States31.4%
- India13%
- Germany7.9%
- Brazil5.4%
- United Kingdom5%