Generate speech with customizable voices in any language, and create captivating stories using natural-sounding voices.

KittenTTS
$0.07Starting price
0Popularity
About KittenTTS
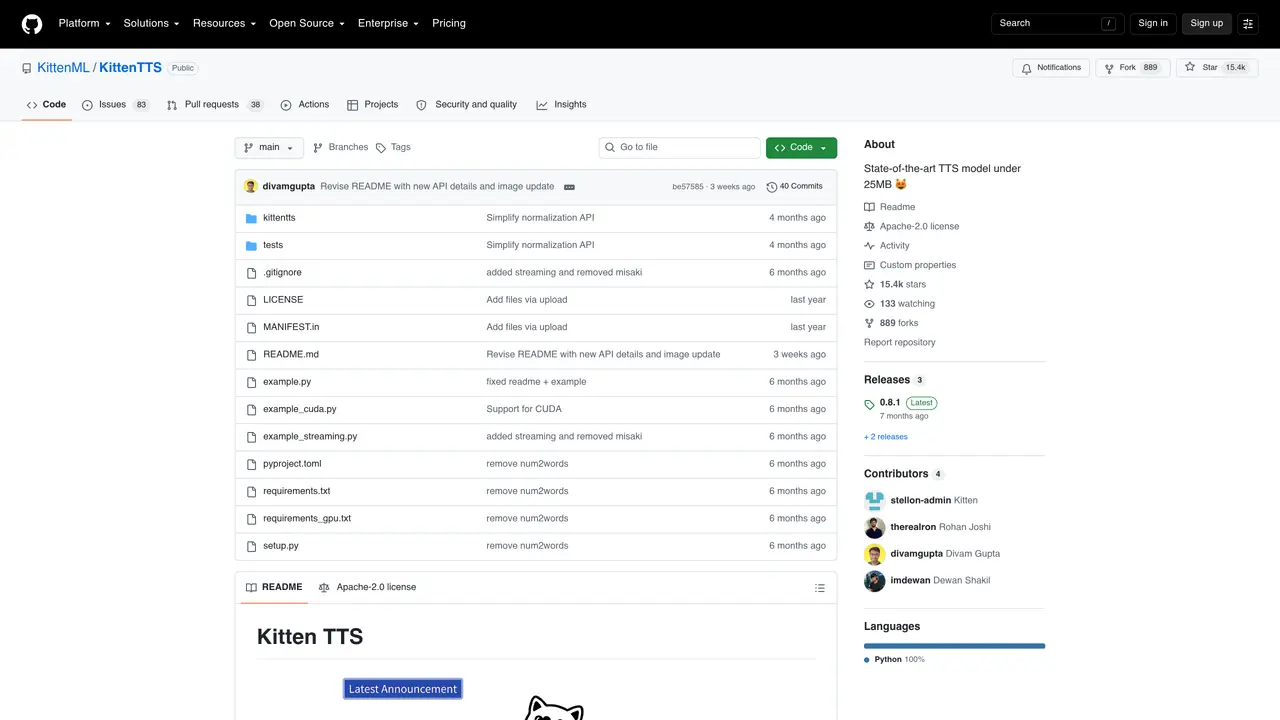
KittenTTS is an ultra-lightweight open-source text-to-speech model designed to convert written text into natural-sounding speech while minimizing computing resource usage. Unlike conventional AI speech models that depend on powerful hardware, KittenTTS operates efficiently on a wide range of devices, including older computers, Raspberry Pis, and web browsers. Its compact 25MB size and 15 million parameter architecture enable real-time speech generation without requiring GPUs or internet connectivity. The model delivers multiple realistic voices and maintains high output quality even on CPU-only systems. KittenTTS is particularly well-suited for developers building privacy-focused applications, edge computing projects, or accessibility tools where resource efficiency is critical. Its Apache 2.0 open-source license allows free use and modification, making it accessible for both personal and commercial projects. By prioritizing performance on constrained hardware, KittenTTS fills a gap left by larger models that struggle to run in low-resource environments.
GitHub, Inc.
San Francisco, California, US · Founded 2008
- Founders
- Tom Preston-Werner, Chris Wanstrath, PJ Hyett, Scott Chacon
- Founded
- 2008
- Headquarters
- San Francisco, California, US
- Legal status
- Subsidiary of Microsoft (NASDAQ: MSFT)
Key features
- Ultra-lightweight 25MB footprint
- 15 million parameter design
- Runs on CPU-only systems without GPUs
- No internet connectivity required
- Multiple realistic voices available
- Real-time speech generation
- Open-source Apache 2.0 license
- Compatible with older computers and Raspberry Pis
- Works in web browsers
- Privacy-focused local processing
Use cases
- Deploying voice AI in resource-constrained environments
- Building privacy-focused text-to-speech applications
- Creating accessibility tools for low-resource devices
Pros
- Ultra-lightweight architecture with model sizes ranging from 25 MB to 80 MB, suitable for edge deployment.
- CPU-optimized ONNX-based inference that runs efficiently without requiring a GPU.
- Supports 8 built-in voices and adjustable speech speed for customization.
- Open-source Apache 2.0 license allows free use, modification, and commercial applications.
- High-quality 24 kHz audio output with built-in text preprocessing for numbers, currencies, and units.
Cons
- Currently in developer preview with APIs subject to change between releases.
- Some users report issues with the int8 quantized model, which may require troubleshooting.
Frequently asked questions about KittenTTS
What is KittenTTS and what does it do?
KittenTTS is an open-source, lightweight text-to-speech library that converts written text into natural-sounding speech while prioritizing efficiency and low resource usage.
Who is KittenTTS designed for?
It is designed for developers, researchers, and organizations building applications for edge computing, privacy-focused tools, or accessibility solutions where hardware resources are limited.
Does KittenTTS require a GPU to run?
No, KittenTTS is optimized for CPU-only execution and does not require a GPU for inference.
What voices are available in KittenTTS?
KittenTTS includes 8 built-in voices: Bella, Jasper, Luna, Bruno, Rosie, Hugo, Kiki, and Leo.
Can KittenTTS be used commercially?
Yes, KittenTTS is released under the Apache 2.0 license, which permits both personal and commercial use.
How do I get started with KittenTTS?
Installation can be done via pip using a provided wheel file, and basic usage involves loading a model and generating speech from text with optional voice and speed parameters.