Generate speech with customizable voices in any language, and create captivating stories using natural-sounding voices.
Speech-to-Speech
$0.01Starting price
0Popularity
About Speech-to-Speech
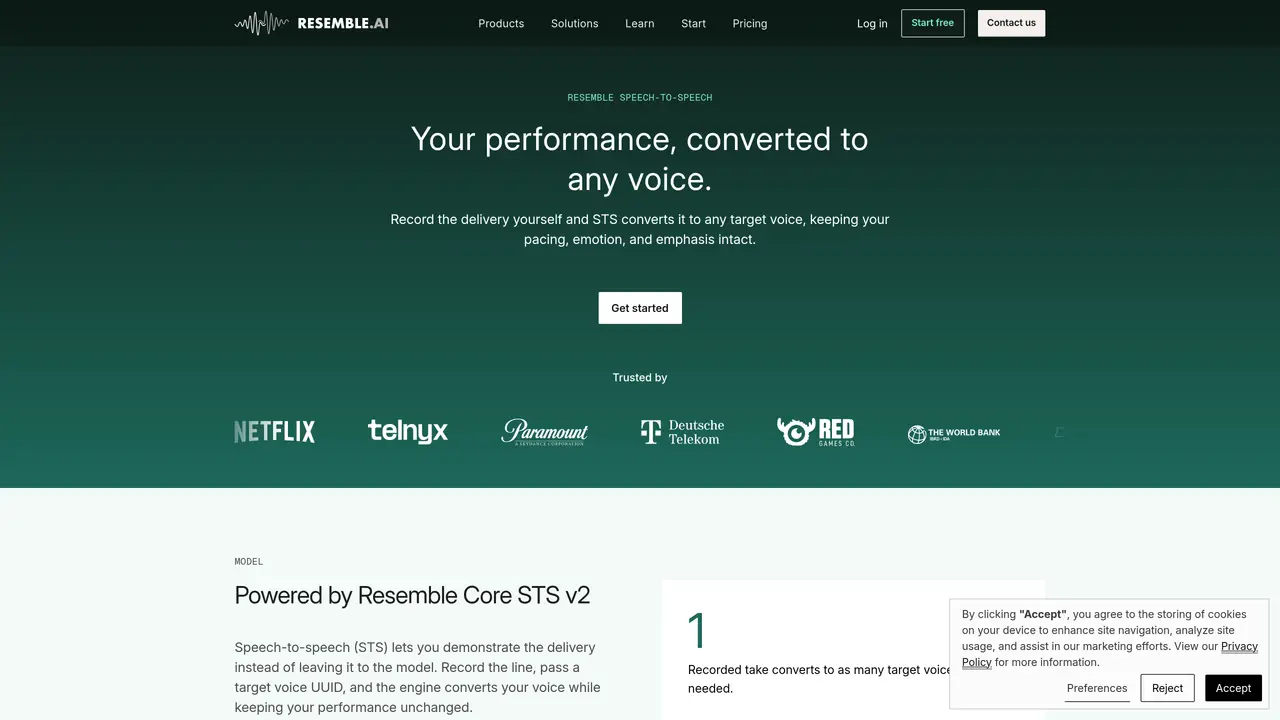
Resemble AI’s Speech-to-Speech Voice Conversion is an AI-powered voice generator that instantly transforms one’s voice into another. Powered by deep learning and natural language processing, this tool offers unparalleled real-time voice conversion with high-quality audio output. With Speech-to-Speech, you can easily clone your own voice, as well as integrate it with APIs, localizations, audio editing, game and Unity integrations, and mobile Android and IOS support. Whether you’re a content creator, developer, or gamer, Speech-to-Speech makes it simpler than ever to transform your voice and customize your audio experience. With its advanced AI technology, you’ll have a realistic, high-quality voice conversion in seconds. Use Cases And Features: 1. Create customized audio experiences in games. 2. Create localized audio in different languages. 3. Generate realistic audio for video content.
Resemble AI
Toronto, Canada · Founded 2018
- Founder
- Zohaib Ahmed
- Founded
- 2018
- Headquarters
- Toronto, Canada
Key features
- AI-powered voice generator
- Real-time voice conversion
- High-quality audio output
- Clone own voice
- Integrate with APIs and localizations
- Audio editing and game integrations
- Mobile Android and IOS support
Use cases
- Content creation: transform your voice for video content
- Game development: create customized audio experiences in games
- Localization: create audio in different languages
Pros
- Preserves original pacing, emotion, and emphasis during voice conversion
- Supports conversion to multiple target voices from a single recorded performance
- Allows prompt-guided adjustments to accent, tone, or speaking style without re-recording
- Compatible with various audio formats and sample rates for flexible deployment
- Designed for high-stakes applications with enterprise-grade security and compliance
Cons
- Requires a clean, single-speaker recording for optimal performance
- Output quality depends on the clarity and suitability of the input audio
- May not fully replicate nuanced vocal characteristics in all cases
Speech-to-Speech videos
Frequently asked questions about Speech-to-Speech
What is Resemble AI's Speech-to-Speech (STS) tool?
Resemble AI's Speech-to-Speech is a voice conversion tool that transforms a recorded performance into another voice while preserving pacing, emotion, and emphasis. It allows users to record a single take and convert it into multiple target voices without re-recording.
Who should use Speech-to-Speech?
Speech-to-Speech is designed for content creators, developers, game developers, filmmakers, voice agents, and localization teams who need high-quality, realistic voice conversions for applications like games, films, audiobooks, and multilingual content.
How does Speech-to-Speech work?
Users record a performance, then pass a target voice UUID to the engine, which converts the recording into the target voice while maintaining the original delivery. The tool also supports prompt-guided adjustments for accent, tone, or speaking style.
What are the key features of Speech-to-Speech?
Key features include human-guided conversion, one-take multi-voice output, prompt-guided steering for accents or tones, preservation of emotional delivery, and support for streaming and multiple audio formats like WAV and MP3.
Does Speech-to-Speech support integrations?
Yes, Speech-to-Speech supports integrations with various environments and workflows, including game engines, mobile platforms (Android and iOS), and API-based deployments. It also offers on-premises and air-gapped deployment options for enterprise use.
What are the typical use cases for Speech-to-Speech?
Common use cases include creating localized audio for different languages, generating realistic dialogue for games and films, producing consistent narration for audiobooks, and enhancing voice agents or IVR systems with natural-sounding speech.