
Generate captions, optimize content, and enhance with custom images for maximum engagement.
46M visits/mo-10%#3 Image & Design
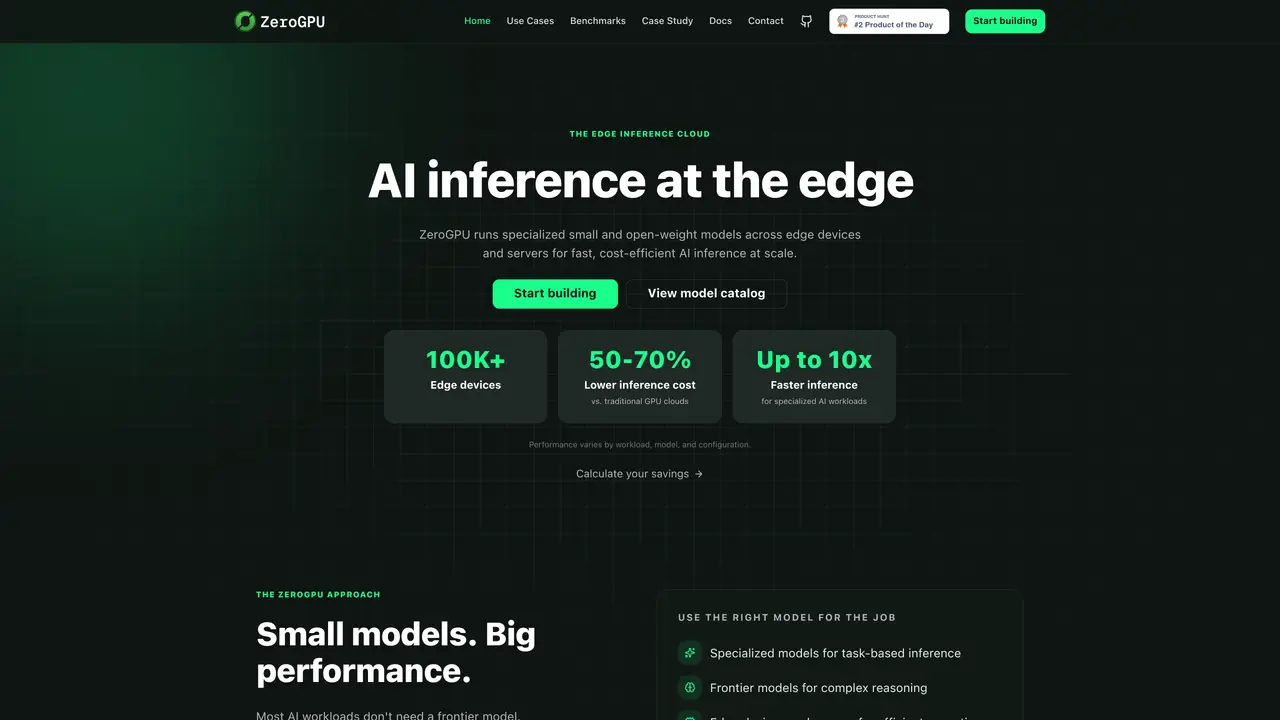
ZeroGPU positions itself as a compute efficiency layer for AI inference, targeting the huge volume of structured tasks that do not actually require frontier-scale models. It routes workloads like classification, extraction, routing, and moderation to specialized small and nano language models running across an edge-powered network with cloud fallback, all exposed via an OpenAI-compatible API and analytics dashboard. ZeroGPU reports 3× faster responses for many inference tasks and up to 10× faster classification and signal extraction, which matters a lot for chatty agents and real-time apps. The tool is designed for AI product teams and SaaS startups that need to cut inference bills while keeping UX responsive. It also supports agent and workflow automation builders, enterprise risk, compliance, and security teams, as well as adtech and marketing platforms. ZeroGPU uses consumption-based pricing tied to tokens processed, rather than fixed seat licenses, aligning cost with actual inference volume. The public savings calculator shows a representative small model at about $0.05 per 1M input tokens and $0.40 per 1M output tokens, often cutting costs by more than 90 percent versus premium providers for similar workloads.
AI inference at the edge refers to running AI models on local or distributed edge devices rather than centralized cloud servers, reducing latency and infrastructure costs while maintaining performance for high-volume, specialized tasks.
Small language models (SLMs) are purpose-built models trained for specific, high-volume tasks such as classification, intent extraction, or moderation. They often outperform larger models on focused workloads while delivering lower latency and cost.
ZeroGPU is an inference cloud platform that routes AI workloads to specialized small and nano models across an edge-powered network with cloud fallback, offering lower latency, reduced costs, and an OpenAI-compatible API.
ZeroGPU is not designed to replace large language models (LLMs) for complex reasoning tasks but instead complements them by handling high-volume, structured workloads more efficiently with specialized models.
No major code changes are required; ZeroGPU works with existing OpenAI SDKs by simply changing the base URL and specifying the appropriate model, making integration straightforward.
ZeroGPU reduces costs by routing workloads to specialized small models optimized for efficiency, using edge infrastructure where possible, and offering usage-based pricing tied to tokens processed rather than fixed infrastructure.
zerogpu.ai · third-party estimates from Similarweb
Last 4 months · grows by one month every month
Share of visits · estimated visits
Automation & Agents · Sep 2026
Traffic figures are third-party estimates, good for scale and trends; they can differ from a company's own numbers. Updated monthly.
We use essential cookies to run aitoolnavio™, and optional cookies to analyze traffic and measure our marketing. You choose what we use — optional cookies stay off unless you turn them on. See our Privacy Policy.
One short email a week: fresh tools worth trying, honest takes and the updates that actually matter. No spam, unsubscribe any time.
Generate captions, optimize content, and enhance with custom images for maximum engagement.
Build conversational forms, capture rich responses, and automate follow-ups with AI-powered surveys and workflows.
Automate code, research, and documents using agents.
AI-powered IDE for autonomous coding tasks and agentic development workflows
Source, match, and manage talent with predictive analytics for effortless recruiting.
Automate workflow, optimize operations, and detect potential issues with this efficient AI-driven solution.
Transforms thoughts into actions, enhancing productivity and efficiency.
AI Recruitment engine to hire top global talent
All-in-one team productivity platform combining chat, docs, video meetings, workflows, and AI tools in one place.
Personal assistant that coordinates tasks across apps and devices via text or call
AI automation and agent-building platform with 3,000+ app integrations
AI job search copilot that matches roles to skills, optimizes resumes for ATS, generates cover letters, and autofills applications with real-time insights.
Matched on what this tool does — grouped by the job you would be replacing.
matches Swap API URLs and cut inference costs · Agent Cost Optimizer and savings analytics · Usage-based billing
Routes LLM requests across 200+ AI models using adaptive scoring to balance capability, latency, cost, and policy in a single OpenAI-compatible endpoint.
Single endpoint routing LLM API calls to minimize inference costs
Unified API layer for multiple AI model vendors with pay-per-request billing
Unified API to access hundreds of AI models from multiple providers
matches OpenAI-compatible APIs and SDKs · Vertical model catalog · Edge-powered inference network
Unified OpenAI-compatible API to route, manage, and analyze LLM requests across 25+ providers for multi-model app development.
Access multiple AI models through one unified API with 99.96% uptime and automatic failover for reliable application performance.
Hosted open-source language models accessed via standard APIs at reduced cost