GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.
OpenLM Chatbot Arena
0Popularity
About OpenLM Chatbot Arena
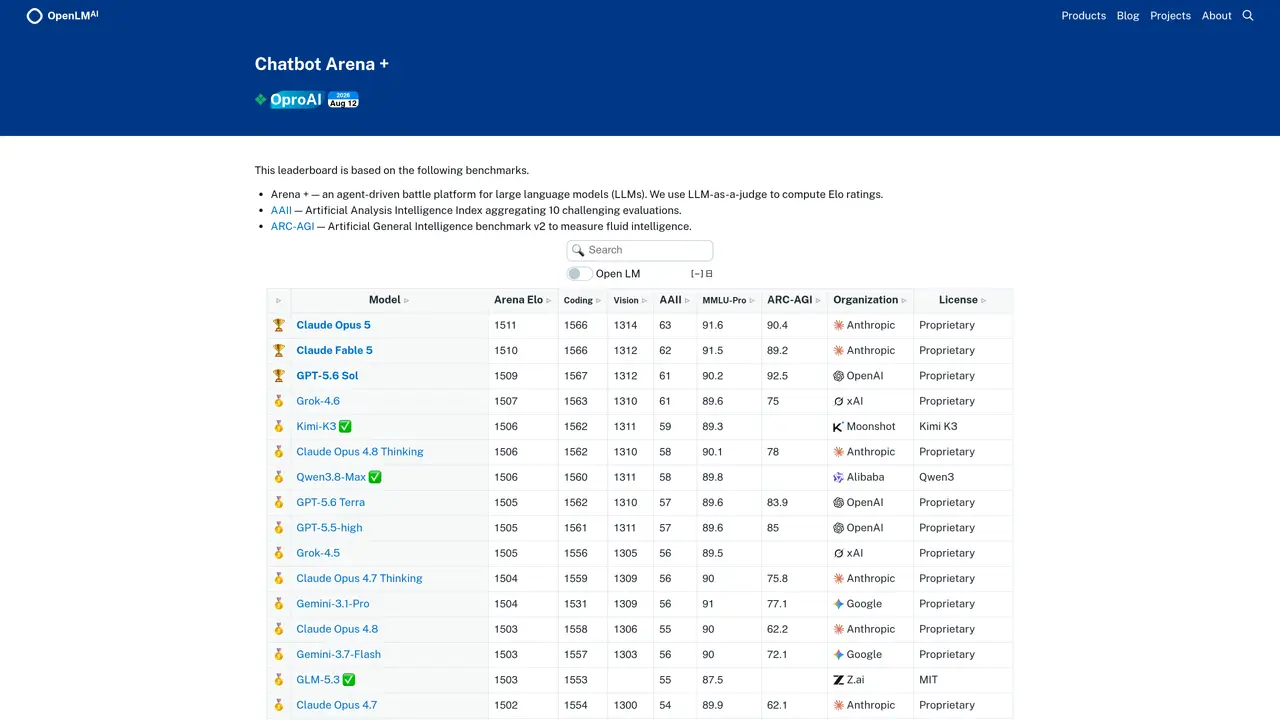
OpenLM Chatbot Arena is an AI leaderboard that ranks large language models (LLMs) by performance using multiple benchmarks from providers like Chatbot Arena, MMLU, and Arena-Hard-Auto. The platform aggregates results into a clear, interactive leaderboard that displays both open-source and proprietary models side by side. Rankings are updated regularly based on crowdsourced evaluations and real-time user feedback, providing a dynamic snapshot of the best-performing models at any given time. Users can explore rankings, compare specific models, and test language model capabilities directly through the interface. The tool is designed for AI professionals, researchers, developers, and data analysts who need objective comparisons to guide model selection or benchmarking tasks. It also serves AI enthusiasts and general users interested in understanding which models lead in current performance metrics. The leaderboard simplifies complex evaluation data into an accessible format, making it easier to identify trends and top performers without deep technical expertise.
Key features
- Crowdsourced model evaluation for real-world performance insights
- Real-time user feedback integration into rankings
- Clear, interactive leaderboard for open-source and proprietary models
- Aggregation of multiple benchmark results (e.g., Chatbot Arena, MMLU, Arena-Hard-Auto)
- Side-by-side model comparison capabilities
- Regularly updated rankings reflecting current performance
- Accessible interface for non-experts and professionals
- Filtering options for specific model categories or use cases
Use cases
- Identify top-performing AI models for specific tasks or benchmarks
- Compare open-source and proprietary language models before adoption
- Track emerging trends in LLM performance over time
Pros
- Aggregates multiple benchmarks (Arena+, AAII, ARC-AGI, MMLU-Pro) for comprehensive model comparisons
- Uses LLM-as-a-judge to compute dynamic Elo ratings based on crowdsourced evaluations
- Displays both open-source and proprietary models in a unified, interactive leaderboard
- Provides real-time updates reflecting current model performance trends
- Supports side-by-side model comparisons and direct capability testing through the interface
Cons
- Leaderboard rankings may fluctuate frequently due to dynamic evaluation methods
- Requires reliance on crowdsourced feedback, which could introduce variability in results
- Limited to models included in the aggregated benchmarks, excluding others
- Interface may be overwhelming for users without technical background in AI benchmarks
Frequently asked questions about OpenLM Chatbot Arena
What is OpenLM Chatbot Arena?
OpenLM Chatbot Arena is an AI leaderboard that ranks large language models (LLMs) based on performance across multiple benchmarks, including Arena+, AAII, ARC-AGI, and MMLU-Pro. It uses an agent-driven battle platform and LLM-as-a-judge to compute Elo ratings, providing dynamic and crowdsourced evaluations of both open-source and proprietary models.
Who should use OpenLM Chatbot Arena?
The tool is designed for AI professionals, researchers, developers, and data analysts who need objective comparisons of language models for model selection or benchmarking. It also caters to AI enthusiasts and general users interested in tracking the latest trends in LLM performance.
How are model rankings updated on the leaderboard?
Model rankings are updated regularly based on crowdsourced evaluations and real-time user feedback. The platform aggregates results from multiple benchmarks and uses an Elo rating system to compute performance scores, ensuring rankings reflect current capabilities.
What benchmarks are included in the OpenLM Chatbot Arena leaderboard?
The leaderboard includes benchmarks such as Arena+ (agent-driven battles), AAII (aggregating 10 challenging evaluations), ARC-AGI (measuring fluid intelligence), and MMLU-Pro (measuring advanced knowledge and reasoning). These benchmarks provide a comprehensive view of model performance across different tasks.
Can I compare specific models on the leaderboard?
Yes, the interface allows users to explore rankings and compare specific models side by side. This feature helps users identify strengths and weaknesses of different LLMs based on standardized evaluations.
How do I get started with OpenLM Chatbot Arena?
To get started, visit the OpenLM Chatbot Arena website and navigate to the leaderboard. Users can explore rankings, compare models, and review detailed performance metrics without requiring deep technical expertise.