Cloud platform for web scraping, browser automation, and AI data extraction with 20,000+ pre-built tools and scalable cloud runs.
PDF Parser
$1Starting price
4.3KMonthly visits
11Popularity
About PDF Parser
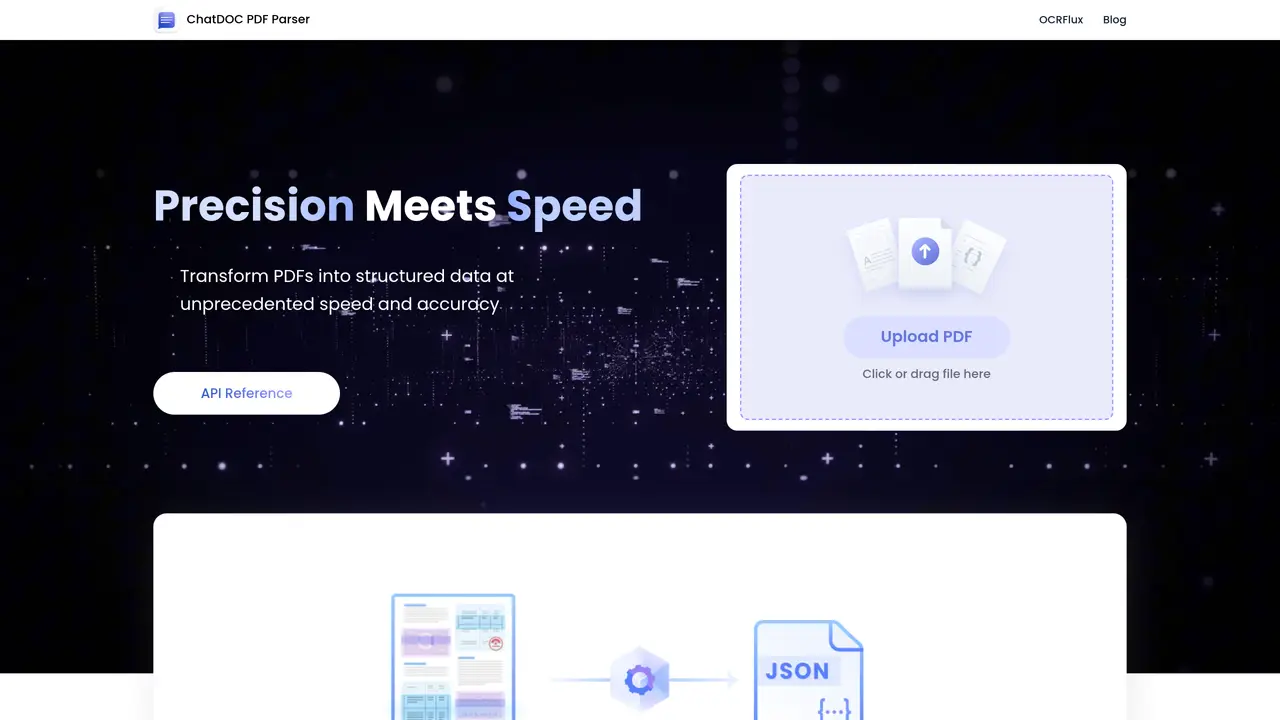
PDF Parser is an AI-powered API and web tool designed for developers, AI engineers, and businesses that need to convert complex PDF documents into structured, retrieval-ready data. It specializes in extracting tables, paragraphs, images, and table of contents from PDFs, including challenging layouts and scanned pages. The tool outputs data in formats suitable for RAG pipelines, such as Markdown or JSON, with layout preservation to maintain usability in downstream workflows. It includes document understanding features like OCR text positioning, reading order determination, table structure recognition, and logical document structure parsing. PDF Parser is optimized for speed, supporting fast parsing via simple API calls and designed for batch processing and data pipelines. The service claims high precision in element extraction and supports high-throughput RAG ingestion, making it suitable for complex PDF handling and automation workflows.
Key features
- Extracts tables, paragraphs, images, and table of contents from PDFs
- Supports scanned and complex layouts with OCR
- Outputs structured data in JSON or Markdown for RAG pipelines
- Preserves document layout and reading order
- Fast parsing via API with batch processing support
- OCR text positioning and table structure recognition
- Logical document structure parsing
- No content filtering policy
- Hybrid parsing approach trained on 10+ million document pages
- Available via API and web interface
Use cases
- Scanning and digitizing documents for archival or analysis
- Training AI models with structured PDF data
- Automating data extraction for workflows and pipelines
Pros
- Specializes in extracting tables, paragraphs, images, and table of contents from complex PDF layouts
- Supports scanned PDFs through OCR text positioning and structure recognition
- Outputs data in structured formats like Markdown or JSON, preserving layout for downstream workflows
- Optimized for speed with fast parsing via API calls and batch processing capabilities
- Designed for high-throughput RAG ingestion with high precision in element extraction
Cons
- May require technical knowledge for API integration and workflow setup
- Performance can vary depending on PDF complexity and quality of scanned content
Frequently asked questions about PDF Parser
What does PDF Parser do?
PDF Parser converts PDF documents into structured, retrieval-ready data such as Markdown or JSON. It extracts tables, paragraphs, images, and table of contents while preserving layout for downstream workflows.
Who is PDF Parser designed for?
The tool is designed for developers, AI engineers, and businesses that need to process complex PDFs for applications like RAG pipelines, database integration, or workflow automation.
Does PDF Parser support scanned PDFs?
Yes, PDF Parser includes OCR capabilities to recognize and extract text and structure from scanned PDFs with high precision.
How do I get started with PDF Parser?
Users can start parsing PDFs by uploading a file through the web interface or making a simple API call to process documents programmatically.
What formats does PDF Parser output data in?
The tool outputs parsed data in formats like Markdown or JSON, ensuring compatibility with downstream workflows such as RAG pipelines.
Can PDF Parser handle complex layouts and tables?
Yes, PDF Parser is optimized to recognize and extract tables with or without borders, as well as documents with complex layouts and hierarchical structures.
PDF Parser Website Engagement
Last Update: 9 days ago
Total Monthly Visits
0
Bounce Rate
0%
Visit Duration (avg)
0.00s
Pages Per Visit
0
Country Rank
0
United States
Global Rank
0
Monthly Traffic
Traffic Sources
Traffic Share By Country
- Indonesia64.6%
- India35.4%