An AI-driven experience management platform for enterprises to collect multi-channel feedback, analyze structured and unstructured data, and deliver actionable insights.
M-VADER
0Popularity
About M-VADER
M-VADER is a machine learning-based sentiment analysis tool designed to help users accurately identify sentiment in text. It is a powerful tool that can be used to quickly extract sentiment from large amounts of text data, allowing users to identify trends, topics, and overall sentiment in a timely manner. The tool is easy to use and has been trained on millions of tweets to accurately identify sentiment in language. With M-VADER’s deep learning capabilities, users can quickly and accurately classify sentiment in a variety of languages. Additionally, M-VADER is equipped with an intuitive user interface and powerful visualization tools, making it easy to interpret the data and draw meaningful insights from it. By leveraging machine learning and natural language processing, M-VADER provides users with a comprehensive analysis of sentiment in text and allows them to quickly identify and act on emerging trends.
Key features
- Machine learning-based sentiment analysis
- Accurate identification of sentiment in large amounts of text data
- Support for multiple languages
- Intuitive user interface
- Powerful visualization tools
- Deep learning capabilities
Use cases
- Identify sentiment in customer reviews to improve customer experience
- Monitor social media content to gain insights on customer sentiment
- Analyze large amounts of text data to identify trends and topics in different languages
Pros
- Enables image generation guided by combinations of text and images
- Supports multimodal input for flexible content creation
- Leverages a large-scale vision-language model (S-MAGMA) for semantic alignment
- Designed for diffusion-based generative models with multimodal context integration
Cons
- Limited to research and academic use cases as per arXiv submission
- Requires technical expertise to implement and deploy
- No official user interface or visualization tools provided
Frequently asked questions about M-VADER
What is M-VADER and what does it do?
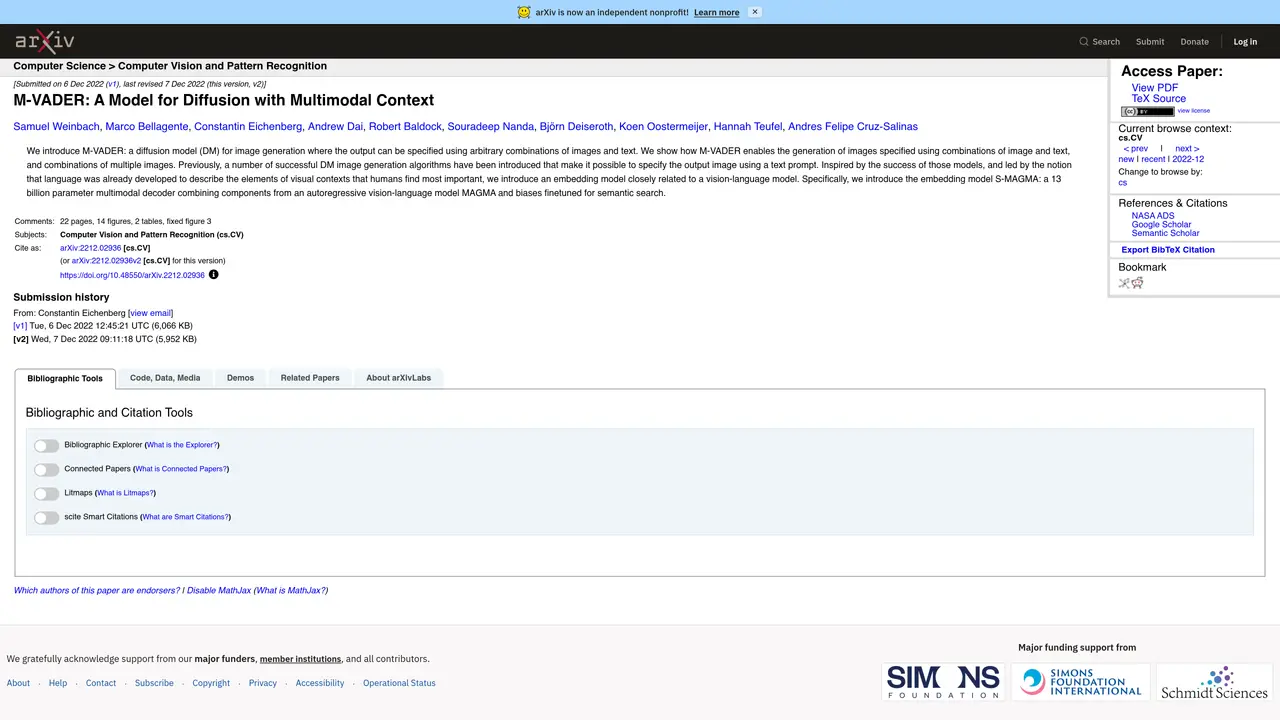
M-VADER is a diffusion-based model designed for image generation that allows users to specify output images using combinations of images and text. It supports multimodal context, enabling generation from text prompts, image prompts, or a mix of both.
Who is M-VADER designed for?
M-VADER is designed for researchers, developers, and practitioners in computer vision and generative AI who need flexible image generation from multimodal inputs.
How does M-VADER work with multimodal inputs?
M-VADER uses an embedding model, S-MAGMA, which combines components from an autoregressive vision-language model (MAGMA) and semantic search biases to process and integrate text and image inputs for image generation.
What are the supported input types for M-VADER?
M-VADER supports text prompts, image prompts, and combinations of both as input to generate images.
Are there any demos or implementations available for M-VADER?
Yes, M-VADER is available on platforms like Replicate and Hugging Face Spaces, where users can interact with the model through demos.
Is M-VADER open-source or available for research use?
M-VADER is presented in a research paper on arXiv, and its code and resources are linked through associated platforms like Hugging Face, indicating availability for research and development purposes.