GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.
BenchGen
FreeStarting price
1.5KMonthly visits
3Popularity
About BenchGen
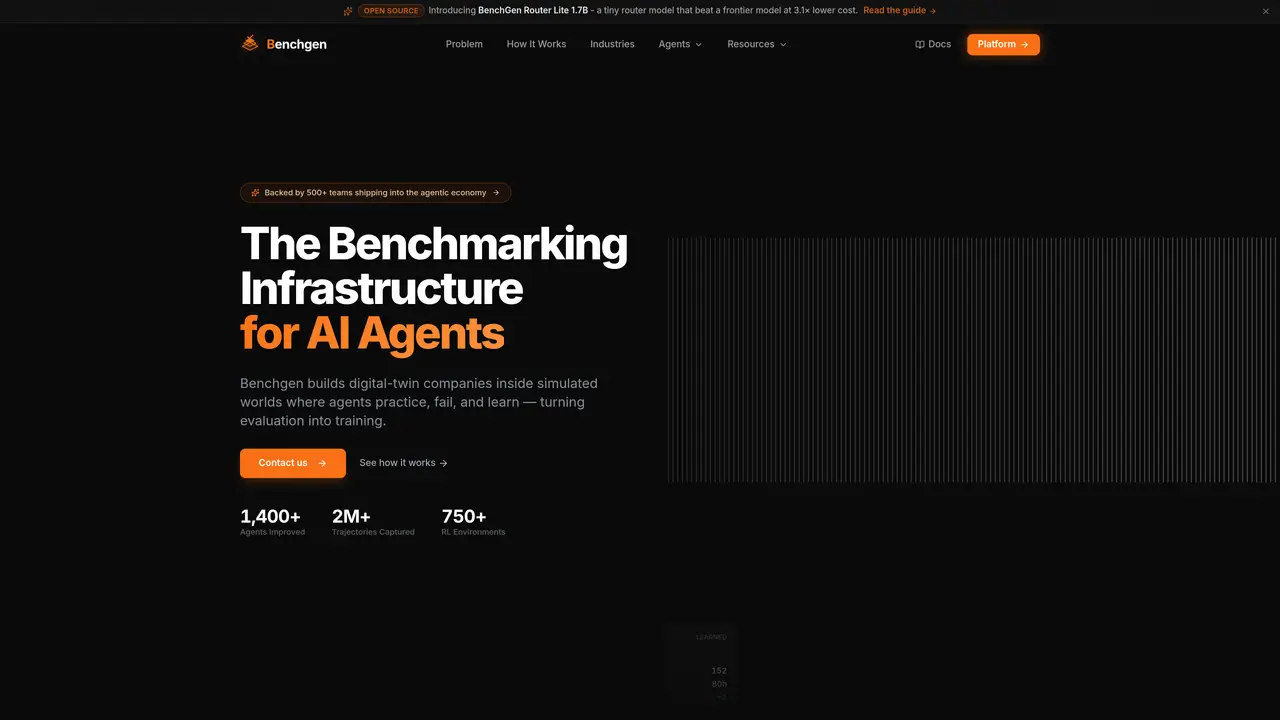
BenchGen provides a benchmarking infrastructure designed for AI agents operating in complex, real-world scenarios. The platform creates digital-twin simulations of enterprise systems where agents can practice, fail, and learn without risking production systems. These simulations replicate business operations such as CRM, ERP, databases, and APIs, enabling agents to execute real actions and generate measurable outcomes. Each interaction produces trajectory data that can be used both for evaluation and as training material, closing the gap between demo performance and real-world reliability. The system supports deterministic benchmarks with full audit trails, making it suitable for regulated industries like defense, energy, and fintech. BenchGen offers a library of over 750 reinforcement learning environments and tracks performance across more than 1,400 agents, with rankings updated in real time.
Key features
- Digital-twin company simulations
- Multi-step workflow testing
- Trajectory logging and analysis
- Cloud and on-premise deployment options
- Air-gapped environment support
- Deterministic benchmarking
- Audit trail generation
- Real-time performance rankings
Use cases
- Testing AI agents in regulated industries like defense and fintech
- Evaluating agent reliability before production deployment
- Training agents using failure data from simulated environments
Pros
- Simulates real enterprise systems including CRM, ERP, and APIs
- Generates trajectory data usable for both evaluation and training
- Supports deterministic benchmarks with full audit trails
- Offers over 750 reinforcement learning environments
- Provides real-time performance rankings across agents and models
Cons
- No mention of a free tier or open access
- Requires enterprise data integration for realistic simulations
- Limited to agentic AI systems rather than general AI models
Frequently asked questions about BenchGen
What is AI agent benchmarking?
AI agent benchmarking is a structured evaluation process that measures how well an AI agent performs on real tasks under realistic conditions against defined success criteria. It runs agents through complete multi-step workflows, including tool calls, data retrieval, and decision sequences, scoring every step rather than just a single response.
Why isn't standard LLM evaluation enough for autonomous agents?
Standard LLM benchmarks like MMLU or HumanEval measure isolated prompt-response quality, scoring a single output rather than a decision sequence. Autonomous agents must call tools, retrieve context, make sequential decisions, and complete multi-step workflows, which requires more comprehensive testing.
Who should use BenchGen?
BenchGen is designed for organizations where AI failure is not an option, particularly in regulated industries such as defense, energy, utilities, and fintech. It is also suitable for teams building the next generation of AI agents across government, education, and cloud infrastructure sectors.
What kind of environments does BenchGen simulate?
BenchGen simulates digital-twin environments of enterprise systems, including CRM, ERP, databases, and APIs. These simulations replicate real business operations, allowing agents to execute real actions and generate measurable outcomes in a risk-free setting.
Does BenchGen support on-premise deployment?
Yes, BenchGen supports deployment in fully isolated runtimes powered by cloud or on-premise GPU/CPU servers. It can also be deployed in air-gapped environments for maximum security, particularly for classified or sensitive use cases.
How does BenchGen help close the gap between demo performance and real-world reliability?
BenchGen turns evaluation into training by capturing trajectory data from every agent interaction in simulated environments. This data is used both for evaluation and as training material, enabling agents to learn from failures and improve their performance in real-world scenarios.
BenchGen Website Engagement
Last Update: 9 days ago
Total Monthly Visits
0
Bounce Rate
0%
Visit Duration (avg)
—
Pages Per Visit
0
Country Rank
0
United States
Global Rank
0