GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.
ImageBind by Meta
0Popularity
About ImageBind by Meta
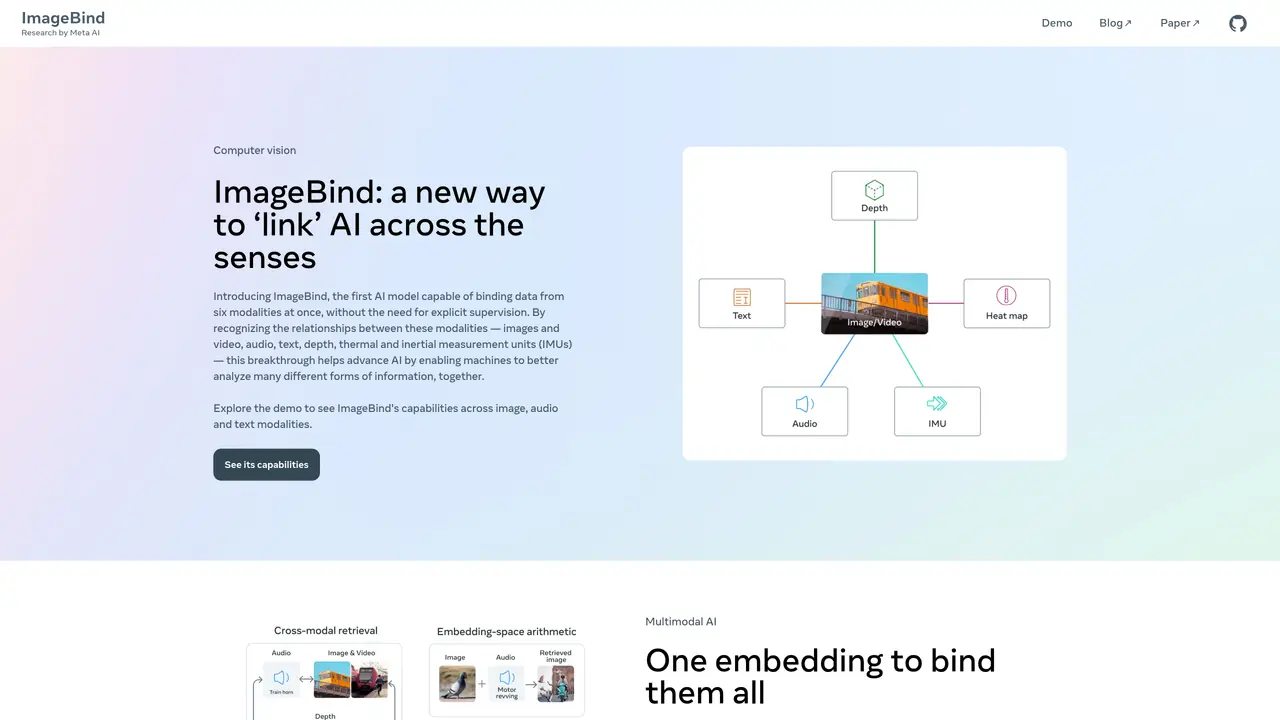
ImageBind by Meta is a revolutionary AI model that enables unprecedented levels of data analysis. Using cutting-edge technology, ImageBind can bind data from six modalities at once, including images and video, audio, text, depth, thermal, and inertial measurement units (IMUs). This allows machines to analyze many different types of information collaboratively, quickly and accurately. With ImageBind, users can unlock previously inaccessible insights from a multitude of data sources, helping to drive better decision-making and improve workflow efficiency. ImageBind is the first of its kind to achieve this level of data binding without requiring explicit supervision. The intuitive interface makes it easy to use, even for first-time users. Sign up now to unlock the power of ImageBind and gain access to a world of data insights.
Key features
- Analyze large-scale datasets using multiple modalities
- Automate data analysis for improved efficiency and accuracy
- Intuitive interface for easy onboarding of first-time users
- Bind data from six modalities at once, including images and video, audio, text, depth, thermal, and inertial measurement units (IMUs)
- Achieve unprecedented levels of data analysis without requiring explicit supervision
Use cases
- Analyze large-scale datasets using multiple modalities
- Automate data analysis for improved efficiency and accuracy in various industries
- Onboard first-time users easily with the intuitive interface
Pros
- Enables binding of six modalities (images, video, audio, text, depth, thermal, and IMUs) simultaneously
- Eliminates the need for explicit supervision in data binding tasks
- Facilitates collaborative analysis of diverse data types for comprehensive insights
- Designed for versatility across multiple domains requiring multimodal data integration
Cons
- Requires JavaScript to run, limiting accessibility for users with disabled scripting
- Limited public documentation or interface details due to restricted access
Frequently asked questions about ImageBind by Meta
What is ImageBind by Meta?
ImageBind is an AI model developed by Meta that binds and analyzes data from multiple modalities—such as images, video, audio, text, depth, thermal, and IMU sensors—without requiring explicit supervision.
Who should use ImageBind?
Researchers, developers, and organizations working with multimodal data can use ImageBind to gain insights across diverse data types for applications like content understanding, retrieval, and decision-making.
How does ImageBind work?
ImageBind aligns different data modalities into a shared embedding space, enabling machines to process and analyze them collaboratively for tasks like cross-modal retrieval and zero-shot classification.
What are the key capabilities of ImageBind?
It supports binding six modalities, enables zero-shot learning across modalities, and facilitates tasks like image-text retrieval, audio-visual search, and multimodal reasoning.
Does ImageBind require labeled data?
No, ImageBind achieves multimodal binding without explicit supervision, relying on natural associations between modalities rather than labeled datasets.
How can I get started with ImageBind?
Visit the official website to explore documentation, examples, and resources. Access to the tool may require enabling JavaScript in your browser.