GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.
Inference.ai
$1Starting price
13KMonthly visits
18Popularity
About Inference.ai
Inference.ai is a cutting-edge GPU cloud provider that revolutionizes the way businesses and individuals access and utilize graphical processing units (GPUs). By offering a scalable, affordable, and efficient GPU cloud, Inference.ai caters specifically to those in need of substantial computing power without the overhead of managing physical hardware. Whether you’re a data scientist, AI researcher, or a business leveraging machine learning, Inference.ai ensures that you have the computing resources you need, precisely when you need them. Key Features: Access to a Wide Range of NVIDIA GPUs: From the latest A100 80GB versions to specialized models like the RTX 6000 ADA, Inference.ai keeps an extensive stock of over 15+ different NVIDIA GPU SKUs. Global Data Centers: With facilities distributed around the world, users benefit from low-latency connections, crucial for real-time processing and international collaboration. Cost Efficiency: Offering services at prices 82% cheaper than major hyperscalers like Microsoft, Google, and AWS. Scalability: Easily scale your GPU needs up or down depending on project requirements without investing in physical infrastructure. Focus on Model Development: By offloading infrastructure management, users can concentrate on model development and optimization. Inference.ai offers expert advice on the most efficient and optimized compute setups for various needs. The platform’s focus is on removing the burden of infrastructure management from users, making it a particularly appealing choice for those looking to develop and optimize their AI models. Inference.ai stands out by offering an unparalleled range of NVIDIA GPU options at significantly lower costs than its competitors. Its global reach with data centers around the world ensures that users everywhere can access top-tier computing resources with minimal latency.
Key features
- Access to a wide range of NVIDIA GPUs
- Global data centers for low-latency connections
- Cost efficiency, 82% cheaper than major hyperscalers
- Scalability, easily scale GPU needs up or down
- Focus on model development, offloading infrastructure management
- Expert advice on optimized compute setups
Use cases
- AI researchers running complex machine learning models and simulations
- Large enterprises handling extensive data processing tasks and AI-driven analytics
- Startups leveraging affordable GPU access to innovate and develop new AI-based products
Pros
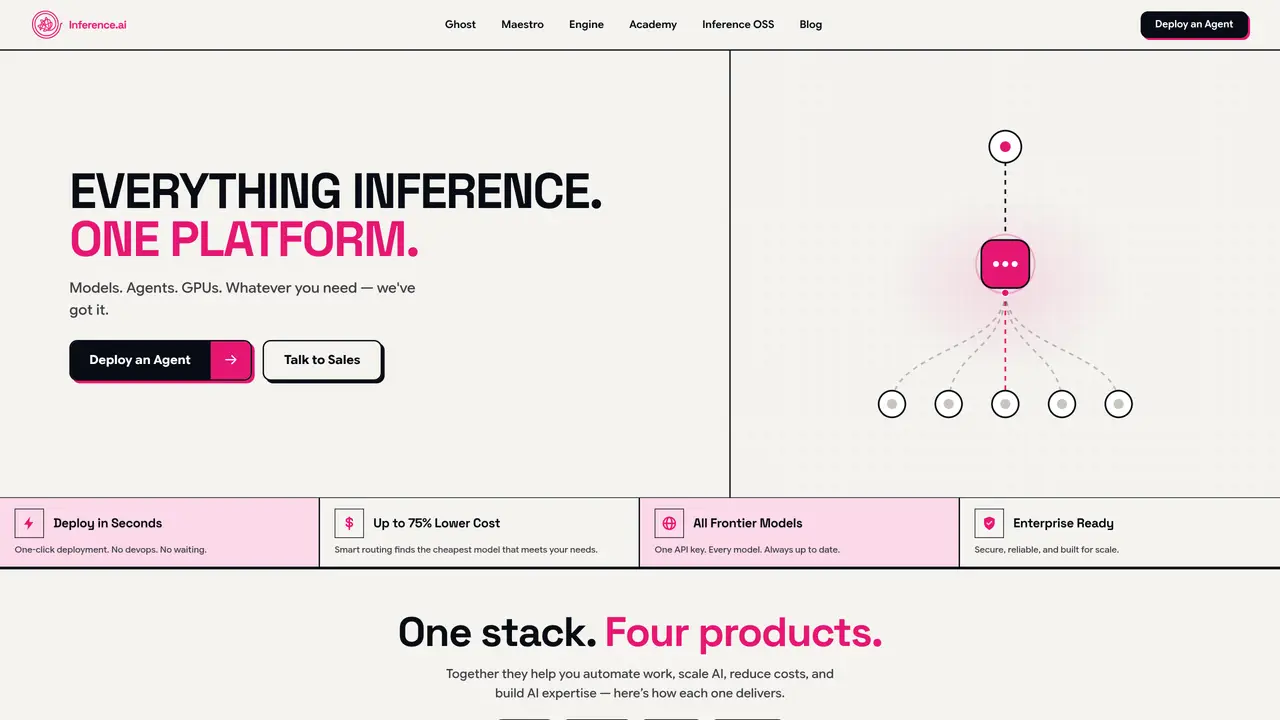
- Offers one-click deployment for AI models and GPUs with no DevOps overhead required
- Provides access to a wide range of NVIDIA GPUs, including high-end models like Blackwell B300s and RTX 4090s
- Includes smart routing to automatically select the most cost-effective model based on performance, speed, and budget
- Features a unified platform combining models, agents, and GPUs with a single API key for streamlined workflows
- Supports scalable InfiniBand clusters that can expand to thousands of GPUs for large-scale workloads
Cons
- Limited transparency on specific pricing structures beyond general cost-saving claims
- May require familiarity with AI infrastructure concepts to fully leverage advanced features like smart routing and cluster scaling
Frequently asked questions about Inference.ai
What is Inference.ai and what does it offer?
Inference.ai provides a unified platform for deploying AI models, agents, and GPUs with one-click deployment and no DevOps overhead. It offers access to a wide range of NVIDIA GPUs, smart model routing, and enterprise-ready infrastructure designed to automate work, scale AI, and reduce costs.
Who should use Inference.ai?
Inference.ai suits AI researchers, data scientists, developers, and businesses that require scalable GPU computing power for model development, deployment, and optimization without managing physical hardware or DevOps tasks.
How does Inference.ai's pricing model work?
The platform uses smart routing to select the most cost-effective model based on performance, speed, and quality, with a unified billing system. Compute options include hourly or reserved bare-metal GPUs, with costs optimized for efficiency.
What integrations or APIs does Inference.ai support?
Inference.ai provides a single API key for accessing all supported models and offers one-click deployment for agents and GPUs. It supports open models like DeepSeek, Qwen, and Kimi, hosted for immediate use.
What are the limitations of Inference.ai?
While offering extensive GPU options, the platform's smart routing and model selection may not always align with highly specialized or niche use cases requiring specific hardware configurations. Enterprise features like hard budget caps are listed as upcoming.
How do I get started with Inference.ai?
Users can start by deploying models or agents with one click, accessing the platform's Academy for guided learning, or exploring open models hosted on the platform. No DevOps setup is required, and deployment is designed to be immediate.
Inference.ai Website Engagement
Last Update: 9 days ago
Total Monthly Visits
0
Bounce Rate
0%
Visit Duration (avg)
0.00s
Pages Per Visit
0
Country Rank
0
Canada
Global Rank
0
Monthly Traffic
Traffic Sources
Traffic Share By Country
- United States32.3%
- Canada31.4%
- Hong Kong14.4%
- India9.8%
- Indonesia6.6%