Scales efficient language processing with open-source accessibility.
357M visits/mo+1%#2 Coding & Development
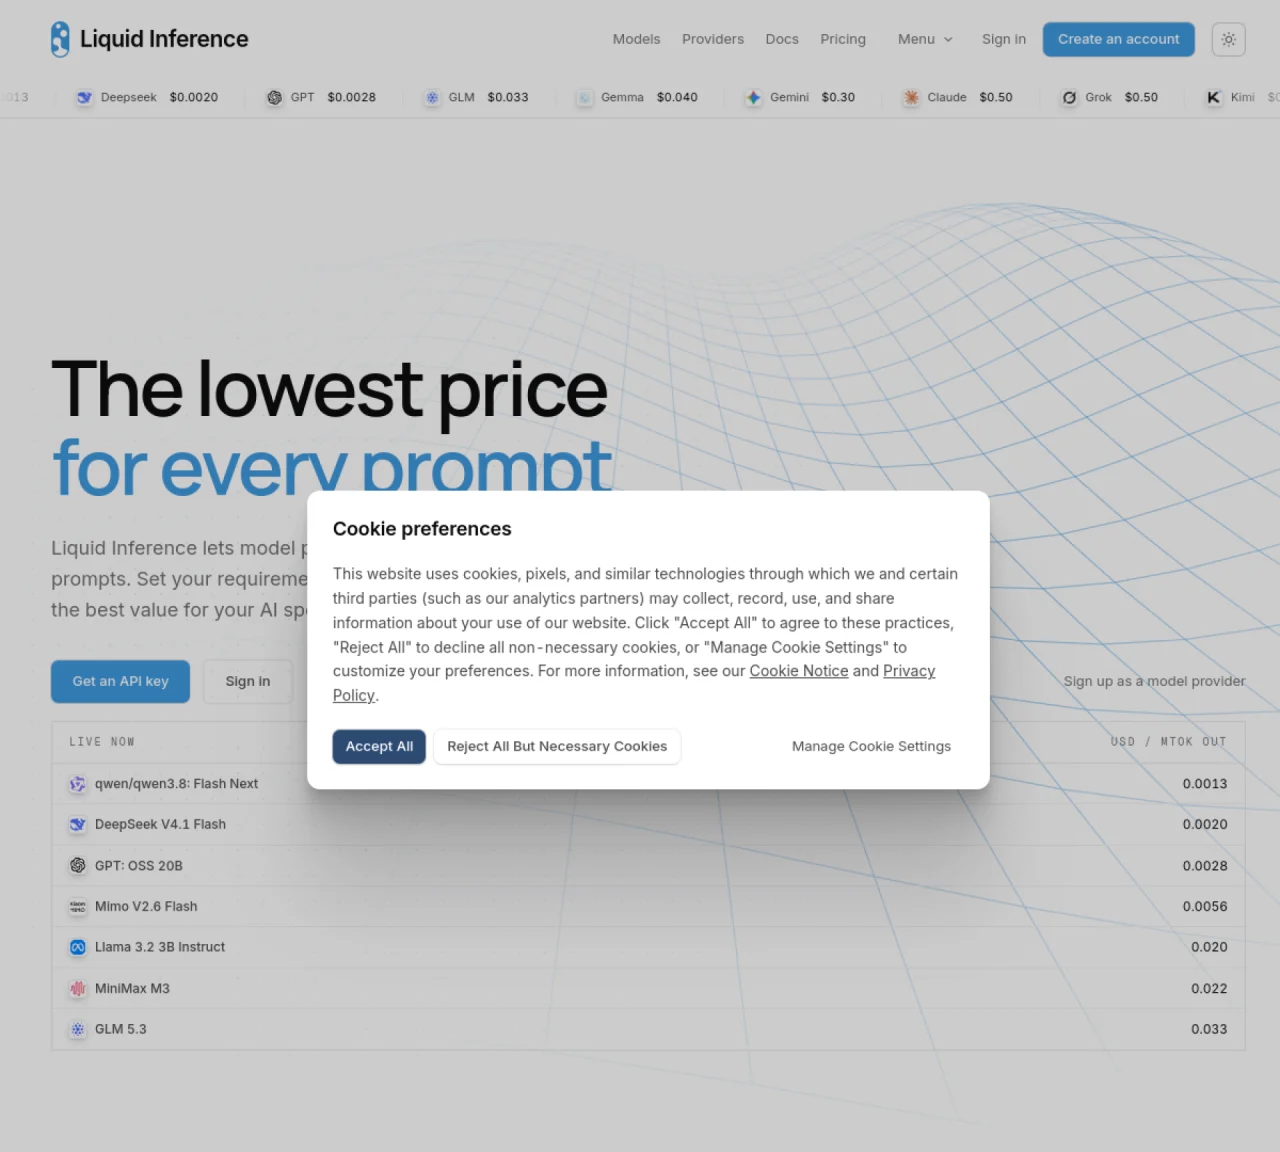
Liquid Inference operates as an auction exchange where model providers compete to fulfill each inference request at the lowest price that meets user-defined requirements. Users specify models, regions, speed, and minimum quality standards, and the system selects the lowest-priced provider that satisfies those terms. Pricing is dynamic, adjusting with supply and demand as providers lower rates during periods of spare capacity. The platform provides itemized billing, public price history, and independent benchmark results for providers. Buyers pay only for tokens consumed, while providers set their own prices and can adjust them freely without fixed rate cards. The exchange supports integration with existing AI coding tools through a compatible API endpoint and offers a CLI for running coding agents with configurable ranking and price caps.
Liquid Inference is an auction exchange where model providers compete to fulfill AI inference requests at the lowest possible price while meeting user-defined requirements such as model type, region, speed, and quality standards.
The platform suits developers, businesses, and researchers who want to optimize costs for AI model inference while maintaining control over performance and quality benchmarks.
Pricing is dynamic and adjusts based on supply and demand, with providers lowering rates during periods of spare capacity. Buyers pay only for tokens consumed, and providers set their own prices without fixed rate cards.
Yes, the platform supports integration with existing AI coding tools through a compatible API endpoint and offers a CLI for running coding agents with configurable ranking and price caps.
Yes, the platform offers itemized billing, public price history, and independent benchmark results for providers to ensure transparency and trust in the auction process.
Users can specify their model, region, speed, and quality requirements to start the auction process. The system then selects the lowest-priced provider that meets those terms.
We use essential cookies to run aitoolnavio™, and optional cookies to analyze traffic and measure our marketing. You choose what we use — optional cookies stay off unless you turn them on. See our Privacy Policy.
One short email a week: fresh tools worth trying, honest takes and the updates that actually matter. No spam, unsubscribe any time.
Scales efficient language processing with open-source accessibility.
Collaboration and version control platform for software development and AI model hosting.
Tesla’s AI stack powers Full Self-Driving, Optimus humanoid robots, and real-world autonomy with neural networks, custom hardware, and Dojo-scale training.
Integrates AI into Airtable to analyze data, summarize insights, draft content, and automate workflows without prior AI experience.
AI-powered website builder that generates a professional site in under a minute and includes tools for content, SEO, and analytics.
Unified platform to access and switch between hundreds of AI models like ChatGPT, Claude, and Gemini via a single API.
xAI builds Grok frontier AI models for reasoning, coding, voice, images, video, enterprise workflows, and developer APIs.
Meta AI enhances machine learning, NLP, and computer vision capabilities.
Crowdsourced platform for blind, side-by-side AI model comparisons with a public leaderboard.
Customize, deploy, and control AI models securely.
Independent benchmarks comparing AI models on quality, speed, and cost across multiple capabilities.
Chat, build, and explore with open AI models.
Matched on what this tool does — grouped by the job you would be replacing.
matches Auction-based provider selection · Customizable model, region, speed, and quality filters · Dynamic price adjustments per request
Unified API gateway for routing and managing AI model requests
Single endpoint routing LLM API calls to minimize inference costs
Unified API layer for multiple AI model vendors with pay-per-request billing
Unified API for routing AI models with spend control and usage tracking