GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.
SymageDocs
$79Starting price
1.2KMonthly visits
1Popularity
About SymageDocs
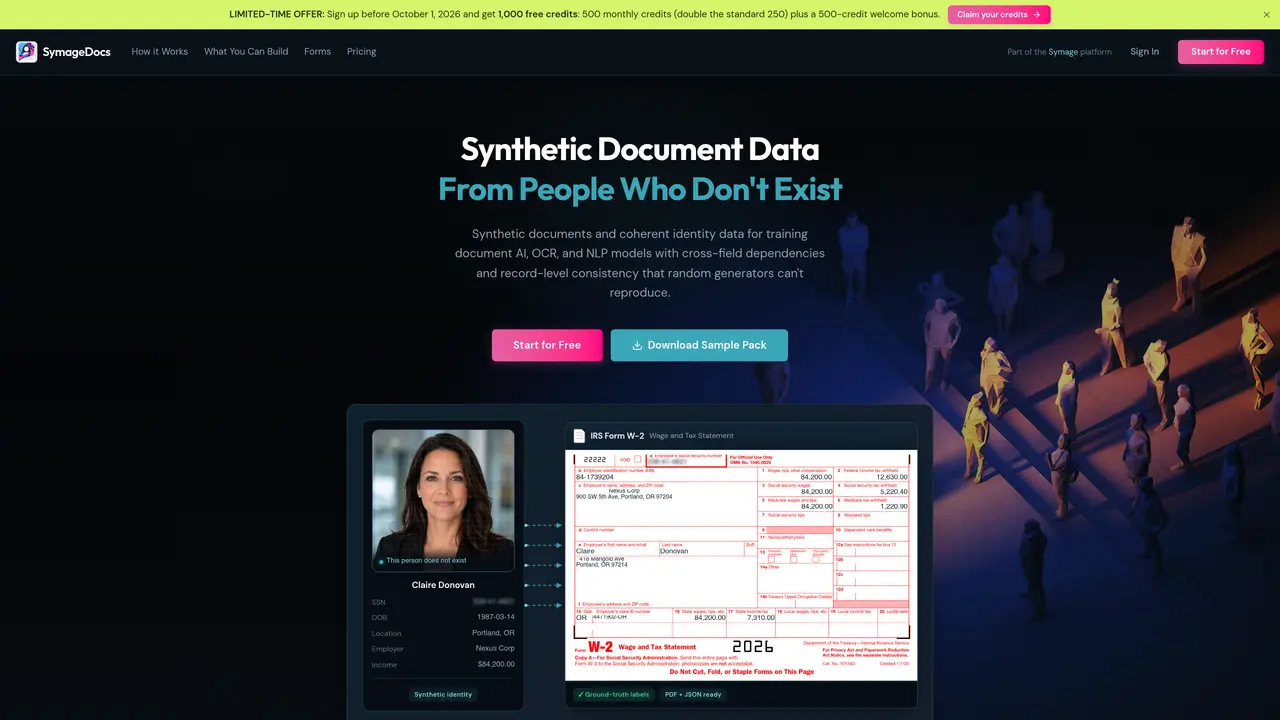
SymageDocs produces synthetic document and tabular data designed for training machine learning models such as document AI, OCR, and NLP systems. The tool creates coherent synthetic identities with cross-field dependencies and record-level consistency, avoiding the unrealistic combinations found in random generators. It supports forms including W-2s, 1040s, and CMS-1500 healthcare claims, producing data without real personal information to reduce privacy and compliance risks. Users can generate, preview, and download labeled datasets in formats like PDF, JSON, and CSV, with ground-truth labels ready for immediate use in training pipelines. The platform offers a Python SDK for automated integration into training workflows, eliminating manual preprocessing steps. SymageDocs emphasizes statistical realism in generated identities, ensuring attributes such as age, occupation, and income align with real-world distributions.
Key features
- Coherent synthetic identities with cross-field dependencies
- Ground-truth labels for PDF, JSON, and CSV formats
- Support for tax returns, healthcare claims, and legal documents
- BIO token classification and layout-aware formats
- Python SDK for automated data generation
- Handwritten PDF output option
- Custom forms support
- Pipeline-ready export formats
Use cases
- Training document AI models for parsing and OCR
- Generating synthetic identity data for compliance-safe testing
- Creating labeled datasets for NLP and layout analysis tasks
Pros
- Preserves cross-field dependencies and record-level consistency
- Provides ground-truth labels in multiple formats (PDF, JSON, CSV)
- Supports a growing library of document types and versions
- Offers a Python SDK for automated data generation and pipeline integration
- Zero PII exposure with programmatically generated data
Cons
- Credit-based pricing model with no free tier beyond limited preview credits
- Handwritten PDFs cost more credits than typed PDFs
- Complex forms may require additional credits based on field count
- Output formats are constrained to those explicitly supported
Frequently asked questions about SymageDocs
What is SymageDocs and what does it do?
SymageDocs generates synthetic document and tabular data for training machine learning models such as document AI, OCR, and NLP systems. It creates coherent synthetic identities with cross-field dependencies and record-level consistency, avoiding unrealistic combinations found in random generators.
Who should use SymageDocs?
The tool is designed for ML teams, researchers, and developers working on document AI, OCR, parsing, or NLP systems who require realistic, labeled training data without privacy or compliance risks.
Does SymageDocs use real personal information?
No, SymageDocs generates data programmatically without using any real personal information, eliminating privacy and re-identification risks.
What formats does SymageDocs support for exporting data?
SymageDocs supports exporting data in formats such as PDF, JSON, and CSV, with ground-truth labels ready for immediate use in training pipelines.
Can SymageDocs integrate with automated training pipelines?
Yes, SymageDocs offers a Python SDK that allows users to generate data, download datasets, and feed them directly into training pipelines without manual steps.
What types of forms does SymageDocs support?
SymageDocs supports forms including W-2s, 1040s, and CMS-1500 healthcare claims, among others, with a growing library of document types.
SymageDocs Website Engagement
Last Update: 9 days ago
Total Monthly Visits
0
Bounce Rate
0%
Visit Duration (avg)
—
Pages Per Visit
0
Country Rank
—
Unknown
Global Rank
0