
OpenAI builds and deploys advanced AI models like GPT-4o for autonomous agents and workflows.

Octen Extract
$1/1k URLsStarting price
0Popularity
About Octen Extract
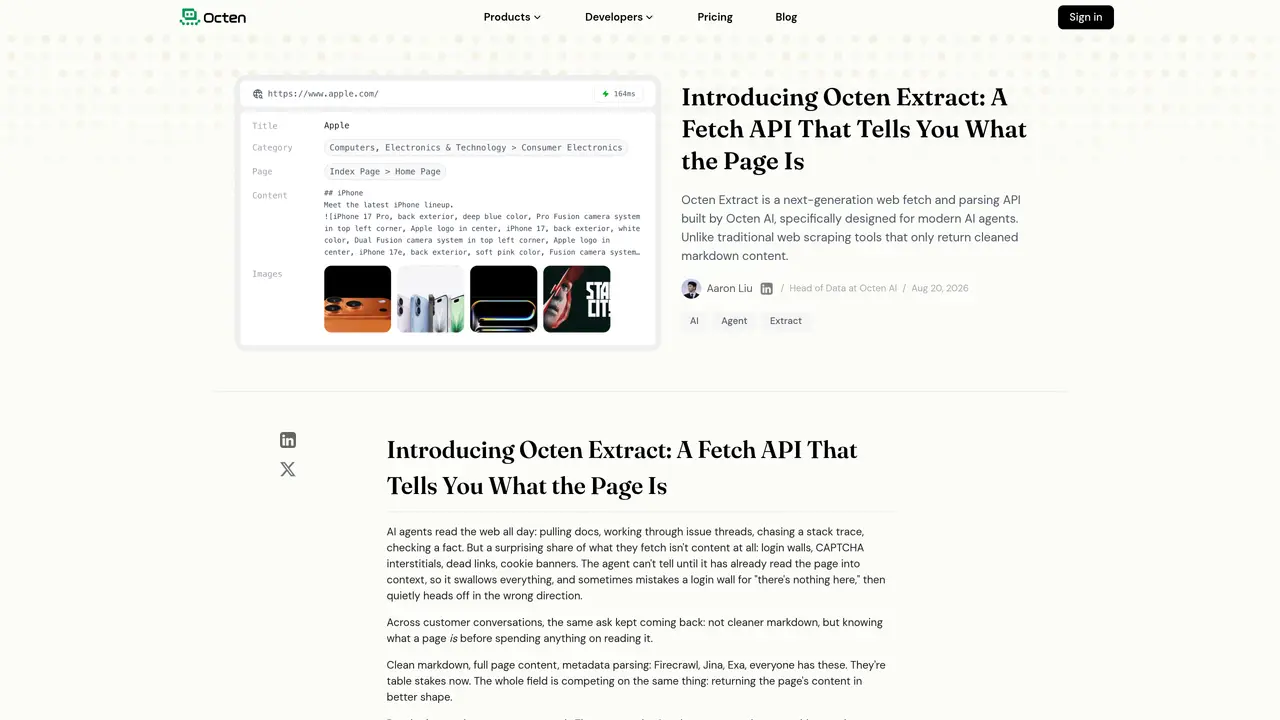
Octen Extract is a fetch and parsing API designed for AI agents that need to evaluate web pages before ingesting their content. It returns both the extracted content and metadata labels indicating the page type and domain, allowing agents to filter irrelevant or misleading pages early. The service processes URLs to provide structured responses including page structure classification, topical category, and full content where applicable. It targets use cases where agents frequently encounter login walls, CAPTCHAs, error pages, or cookie banners that waste tokens and lead to incorrect conclusions. The API operates on a flat pricing model of $1 per 1,000 pages, covering both successful and failed requests. It is positioned as a solution for reducing unnecessary processing costs and improving decision-making in automated web research workflows.
Key features
- Page structure classification (Content Page, Index Page, Operation Page)
- Topical categorization from 160+ domain taxonomy
- Full content extraction for relevant pages
- Intent-focused highlights for key information
- Flat $1 per 1,000 pages pricing
- Handles login walls and CAPTCHAs explicitly
- Returns metadata with every request
- Designed for AI agent workflows
Use cases
- Filtering irrelevant pages before processing in research agents
- Evaluating web sources for credibility in automated research
- Reducing token waste in coding agent workflows
Pros
- Returns page classification before content extraction
- Flat pricing model covering both successful and failed requests
- Built on page-understanding engine used in production search stack
- Handles login walls, CAPTCHAs, and error pages explicitly
- Provides topical categorization from 160+ domain taxonomy
Cons
- No free tier available
- Requires API key for access
- Pricing model may be higher than basic fetch services
Frequently asked questions about Octen Extract
What does Octen Extract do?
Octen Extract is a fetch and parsing API that evaluates web pages before agents ingest their content, returning both extracted content and metadata labels such as page type and domain classification.
Who is Octen Extract designed for?
It is designed for modern AI agents that frequently encounter irrelevant or misleading pages like login walls, CAPTCHAs, error pages, or cookie banners during automated web research workflows.
How does Octen Extract help reduce costs?
By labeling page types and domains upfront, it prevents agents from wasting tokens and processing costs on irrelevant pages, shifting judgment to the API layer before content is read.
What metadata does Octen Extract provide in its response?
Each response includes page structure classification, topical category from a 160+ taxonomy, and full content where applicable, along with the URL and domain information.
How do I get started with Octen Extract?
Users can start by making a POST request to the API endpoint with their API key and a list of URLs to fetch and parse, receiving structured responses for each URL.
Does Octen Extract handle failed requests like 4xx or 5xx errors?
Yes, failed requests such as 4xx or 5xx errors are identified and labeled in the response, ensuring agents are aware of the issue without wasting resources.













