Cloud platform for web scraping, browser automation, and AI data extraction with 20,000+ pre-built tools and scalable cloud runs.
Cockroach Crawler
FreeStarting price
0Popularity
About Cockroach Crawler
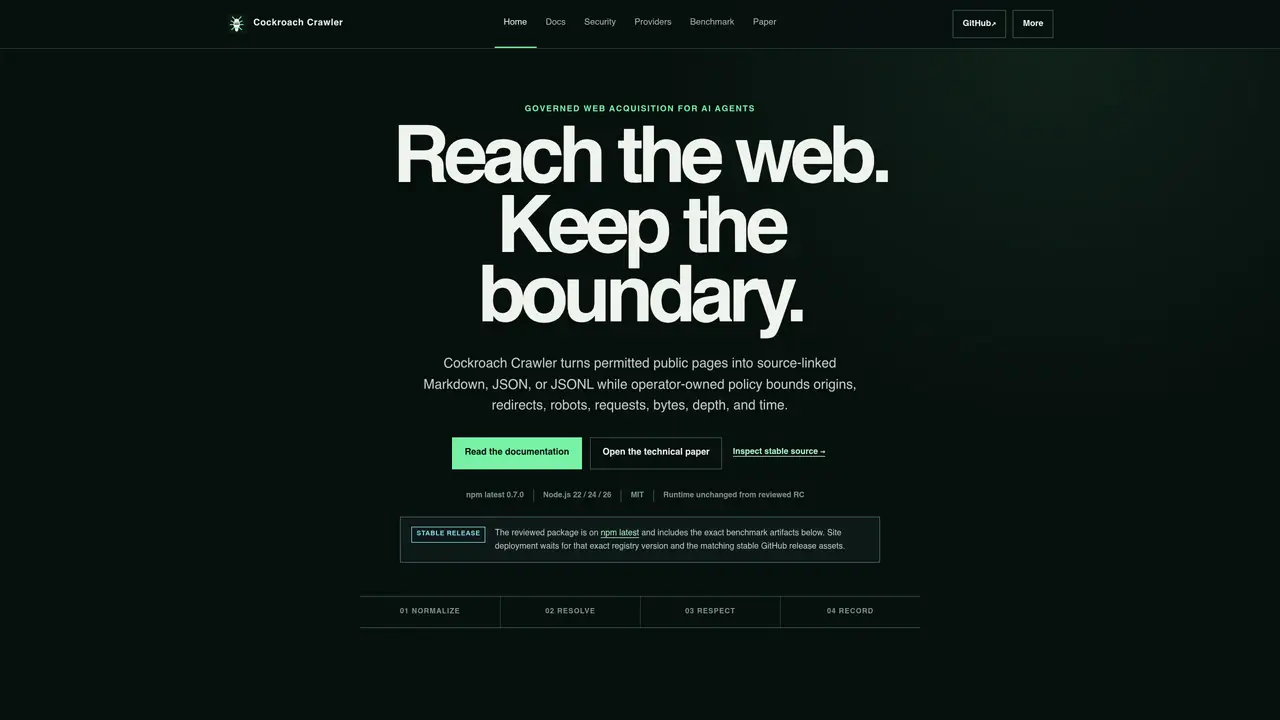
Cockroach Crawler is a governed web acquisition tool designed for AI agents. It converts permitted public web pages into source-linked Markdown, JSON, or JSONL formats while enforcing operator-defined policies that control origins, redirects, robots.txt compliance, request limits, byte consumption, crawl depth, and time constraints. The tool provides a curated capability map of 50+ surfaces covering crawling, rendering, extraction, connection, and operation from a single bounded toolkit. It supports static HTTP crawling, JavaScript rendering, and bounded interactions, producing agent-ready data through readable Markdown, deterministic fields, or schema-validated outputs. The crawler can inspect public sources via provider adapters, connect to agent runtimes through native MCP or JavaScript interfaces, and deploy via Node.js, Docker, or Cloudflare Worker profiles. Authority is maintained through public-network admission controls, DNS pinning, exact budget enforcement, and challenge-aware escalation that halts without bypassing access restrictions.
Key features
- Static HTTP crawling with multiple traversal strategies
- JavaScript rendering and component tree flattening
- Markdown, JSON, and PDF output generation
- Provider adapters for GitHub, YouTube, X, Reddit, and social platforms
- Native MCP server for agent integration
- Bounded process-local asynchronous jobs
- Adaptive relevance traversal for prioritized crawling
- Persistent cache and compact site maps
Use cases
- Extracting structured data from permitted public web pages for AI training
- Monitoring and archiving public content with policy enforcement
- Agent-driven web research with governed access and provenance tracking
Pros
- Governed crawling with operator-defined policy controls
- Supports JavaScript rendering and bounded interactions
- Produces structured outputs including Markdown, JSON, and PDF
- Includes provider adapters for public sources like GitHub, YouTube, and social media
- Offers deployment options via Node.js, Docker, or Cloudflare Worker
Cons
- No explicit mention of a free tier or open-source availability beyond GitHub repository
- Limited to specific operating systems (Windows, macOS, glibc Linux on x64/ARM64)
- No indication of multi-language support beyond English documentation
- Requires exact registry version and matching GitHub release for stable deployment
Frequently asked questions about Cockroach Crawler
What is Cockroach Crawler and what does it do?
Cockroach Crawler is a governed web acquisition tool designed for AI agents. It converts permitted public web pages into source-linked Markdown, JSON, or JSONL formats while enforcing operator-defined policies to control crawling behavior, compliance, and resource usage.
Who should use Cockroach Crawler?
The tool is intended for developers and organizations building AI agents that require reliable, policy-bound access to public web data. It suits use cases where governance, compliance, and controlled data acquisition are critical.
How does Cockroach Crawler enforce governance and boundaries?
It enforces governance through operator-defined policies that control origins, redirects, robots.txt compliance, request limits, byte consumption, crawl depth, and time constraints. Authority is maintained via public-network admission controls, DNS pinning, exact budget enforcement, and challenge-aware escalation.
What formats does Cockroach Crawler output data in?
The tool outputs data in Markdown, JSON, or JSONL formats, with options for readable Markdown, deterministic fields, or schema-validated outputs. It also supports PDF text extraction and metadata capture.
Can Cockroach Crawler render JavaScript and interact with pages?
Yes, it supports JavaScript rendering, bounded interactions such as clicks and scrolling, and can capture full-page screenshots or PDFs. It also flattens component trees and handles same-origin iframes.
How can I integrate Cockroach Crawler with AI agents or other systems?
The crawler can connect to agent runtimes through JavaScript, native MCP, or an optional Maqam gateway. It also provides a token-authenticated Node.js or Docker API, a local playground, and a fixed-origin Cloudflare Worker profile for deployment.