Generate lifelike human videos with AI, making professional video creation fast and accessible for any user.
OmniHuman
0Popularity
About OmniHuman
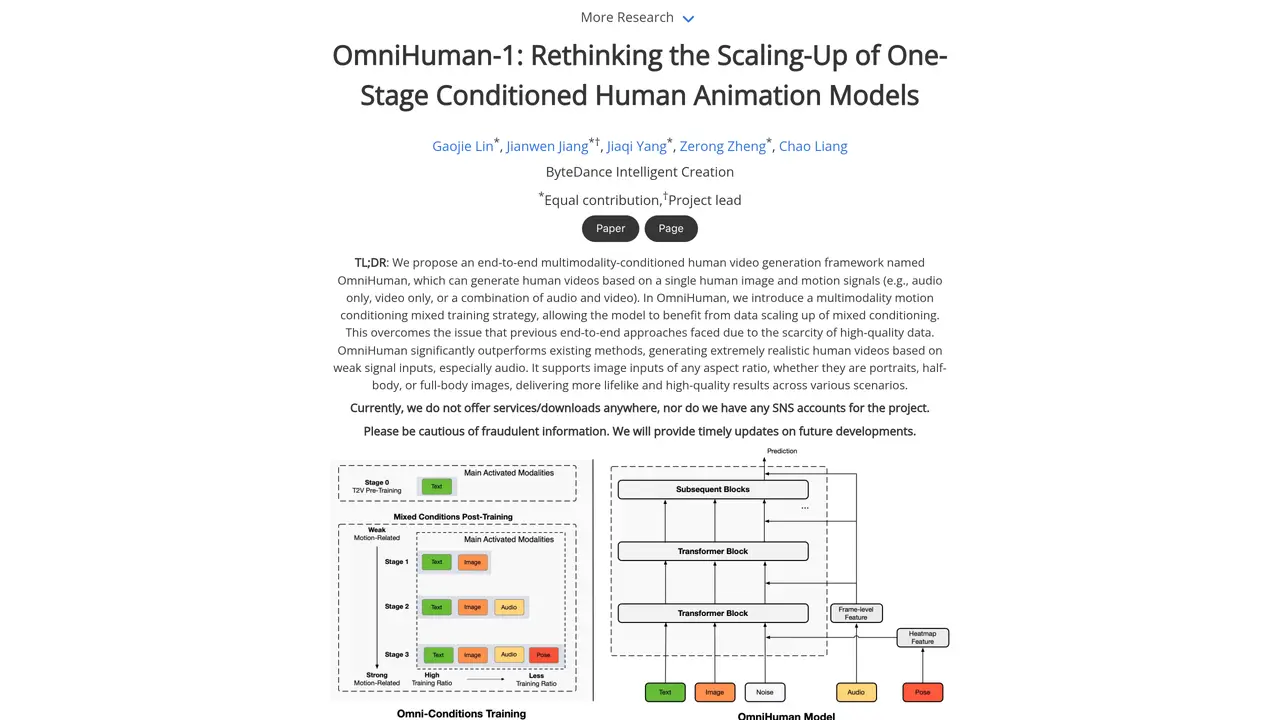
OmniHuman is an AI tool that converts still images into realistic human videos by leveraging audio or video inputs to drive motion. It is designed for media creators, gamers, and educators who need to produce engaging content without investing in complex animation workflows. The tool streamlines the process of generating human-centric videos, making it accessible to users with varying technical backgrounds. By automating motion synthesis, OmniHuman reduces the time and resources typically required for animation, enabling faster content creation. Its multimodal input support allows for flexible use cases, from animating historical figures to creating virtual influencers. While the tool emphasizes ease of use, its output quality depends on the clarity and suitability of the input image. OmniHuman is currently not available to the general public, limiting broader adoption despite its potential for creative and educational applications.
Key features
- Converts static images into realistic human videos
- Supports multimodal input (audio or video signals)
- Enables fast animation creation without extensive resources
- Produces high-quality, natural human motion
- Designed for media creators, gamers, and educators
- Automates motion synthesis from simple inputs
- Accessible to users with varying technical backgrounds
- Limited user control over fine-grained motion details
- Output quality depends on input image clarity
Use cases
- Generate realistic human videos for social media content
- Animate historical figures for educational or documentary purposes
- Create virtual influencers or full-body human videos for marketing
Pros
- Generates realistic human videos from a single still image using multimodal inputs (audio, video, or combined)
- Supports diverse input types including portraits, half-body, full-body images, cartoons, animals, and challenging poses
- Handles various audio styles such as speech, singing, and music with realistic motion synthesis
- Enables video driving to mimic specific actions and combined audio-video driving for precise control
- Delivers high-quality results across different aspect ratios and body proportions without complex animation workflows
Cons
- Currently unavailable to the general public, limiting accessibility and broader adoption
- Output quality heavily depends on the clarity and suitability of the input image and audio
- Lacks public services, downloads, or social media presence, making it difficult to test or verify independently
OmniHuman videos
Frequently asked questions about OmniHuman
What is OmniHuman and how does it work?
OmniHuman is an end-to-end multimodality-conditioned human video generation framework that creates realistic human videos from a single image and motion signals such as audio, video, or a combination of both. It uses a mixed training strategy to handle diverse input types and generate lifelike motion, lighting, and texture details.
Who is OmniHuman designed for?
The tool is aimed at researchers, media creators, and developers interested in human animation, as it simplifies the process of generating human-centric videos without requiring complex animation workflows or extensive technical expertise.
What types of inputs does OmniHuman support?
OmniHuman supports single human images of any aspect ratio (portrait, half-body, full-body) and motion signals including audio only, video only, or a combination of both. It can also handle diverse visual styles such as cartoons, artificial objects, animals, and challenging poses.
Is OmniHuman available for public use?
No, OmniHuman is currently not available to the general public. The project is in a research phase and does not offer services, downloads, or public access. Updates on future developments will be provided on the project's official page.
How does OmniHuman handle audio-driven animations?
OmniHuman significantly improves gesture handling and produces highly realistic results from audio inputs alone. It supports various speech styles and can generate realistic motion even from high-pitched songs or different music genres.
Can OmniHuman mimic specific video actions?
Yes, due to its mixed condition training, OmniHuman can support video driving to mimic specific actions from a reference video, as well as combined audio and video driving to control specific body parts for more precise animations.