GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.

LongLLaMa
$0.07Starting price
0Popularity
About LongLLaMa
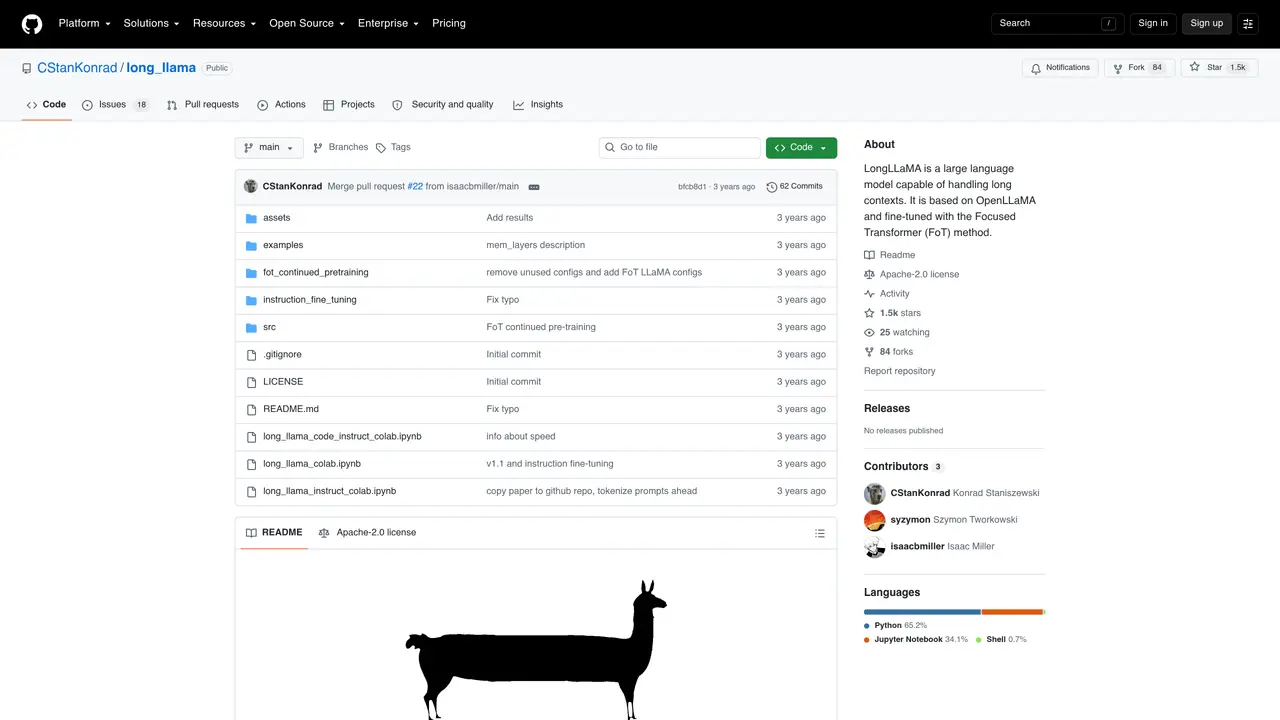
LongLLaMA is a large language model designed specifically for handling extensive text contexts, capable of processing up to 256,000 tokens. It is built on OpenLLaMA and enhanced through the Focused Transformer (FoT) method, which allows it to manage contexts significantly longer than its training data. The repository provides a smaller 3B base variant of LongLLaMA under an Apache 2.0 license, making it accessible for integration into existing implementations. It also includes code for instruction tuning and continued pretraining using FoT. LongLLaMA is particularly useful for tasks requiring deep context understanding, such as analyzing lengthy documents, summarizing large texts, or processing extended conversations. The model is designed for natural language processing tasks and includes tools for easy integration into Hugging Face, facilitating broader adoption in research and development workflows. Note that this is a GitHub repository, meaning it requires technical knowledge to set up and run effectively.
GitHub, Inc.
San Francisco, California, US · Founded 2008
- Founders
- Tom Preston-Werner, Chris Wanstrath, PJ Hyett, Scott Chacon
- Founded
- 2008
- Headquarters
- San Francisco, California, US
- Legal status
- Subsidiary of Microsoft (NASDAQ: MSFT)
Key features
- Processes up to 256,000 tokens for long context understanding
- Based on OpenLLaMA with Focused Transformer (FoT) fine-tuning
- Includes a 3B base variant under Apache 2.0 license
- Provides code for instruction tuning and FoT continued pretraining
- Tools for easy integration into Hugging Face
- Designed for tasks requiring extensive context analysis
- Open-source and available on GitHub
Use cases
- Analyzing lengthy documents or reports
- Summarizing large texts with deep context retention
- Processing extended conversations or dialogues
Pros
- Capable of handling extremely long contexts up to 256,000 tokens or more, enabling deep analysis of lengthy documents.
- Built on OpenLLaMA and enhanced with the Focused Transformer (FoT) method for improved context extrapolation.
- Includes a smaller 3B base variant released under the permissive Apache 2.0 license for broader accessibility.
- Provides code for instruction tuning and continued pretraining, supporting customization and fine-tuning.
- Designed as a drop-in replacement for LLaMA in existing implementations, supporting short contexts up to 2048 tokens.
Cons
- Requires technical expertise to set up and run, as it is distributed as a GitHub repository without a user-friendly interface.
- The FoT method and long-context handling may introduce computational overhead, limiting accessibility for users with limited resources.
Frequently asked questions about LongLLaMa
What is LongLLaMA and what does it do?
LongLLaMA is a large language model designed to handle long contexts, built on OpenLLaMA and fine-tuned using the Focused Transformer (FoT) method. It can process up to 256,000 tokens or more, enabling tasks like analyzing lengthy documents or summarizing large texts.
Who is LongLLaMA suitable for?
LongLLaMA is suitable for researchers, developers, and organizations needing to process or analyze very long text sequences, such as legal documents, code repositories, or extended conversations. Its technical nature makes it best suited for users with programming experience.
How does the Focused Transformer (FoT) method work in LongLLaMA?
The FoT method enhances LongLLaMA's ability to handle long contexts by using a subset of attention layers that access a memory cache of key-value pairs. It employs contrastive learning during training to improve the model's ability to differentiate relevant from irrelevant information, enabling extrapolation beyond trained context lengths.
Can LongLLaMA be integrated into existing workflows?
Yes, LongLLaMA can serve as a drop-in replacement for LLaMA in existing implementations, particularly for short contexts up to 2048 tokens. It also includes inference code for Hugging Face, facilitating integration into research and development workflows.
What variants of LongLLaMA are available?
The repository provides a 3B base variant (LongLLaMA-3Bv1.1) released under the Apache 2.0 license, as well as instruction-tuned variants like LongLLaMA-Instruct-3Bv1.1 and LongLLaMA-Code 7B for specialized tasks.
How do I get started with LongLLaMA?
To get started, visit the GitHub repository to access the model weights, code for inference, instruction tuning, and FoT continued pretraining. Follow the provided documentation and examples to set up and run the model, which requires familiarity with Python, PyTorch, or JAX.