GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.

NVIDIA NeMo Speech
$0.07Starting price
0Popularity
About NVIDIA NeMo Speech
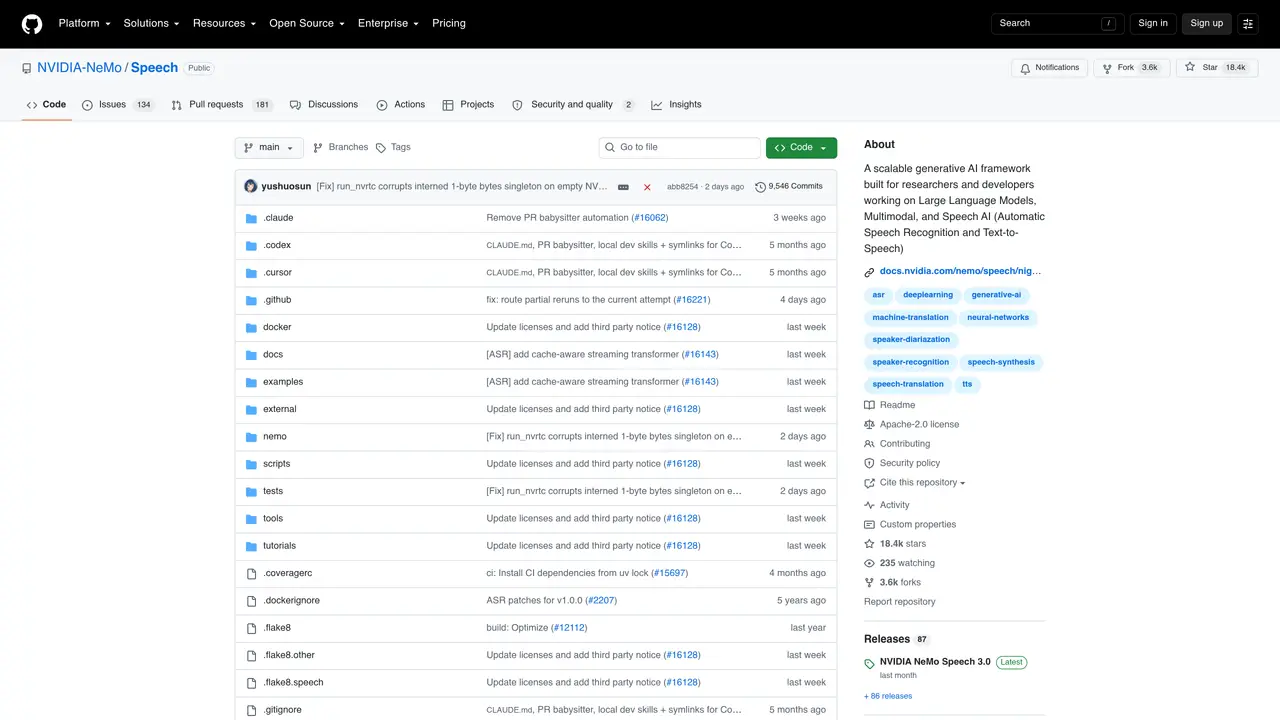
NVIDIA NeMo Speech is an open-source PyTorch framework designed for Automatic Speech Recognition (ASR), Text-to-Speech (TTS), and emerging Speech Large Language Models (LLMs). It provides a modular stack that includes state-of-the-art streaming and offline models, training recipes, and GPU-optimized kernels. The toolkit enables fast experimentation and reproducible deployments across NVIDIA GPUs like H100 and A100, supporting installation via uv, pip, or Docker. It is tailored for research labs exploring novel architectures, applied ML teams deploying voice features, and platform groups standardizing on a transparent speech stack. Typical workflows involve selecting a pretrained ASR or TTS checkpoint, running provided scripts for transcription or synthesis, and fine-tuning on domain-specific audio using included recipes. The framework supports exporting optimized artifacts and containerizing for serving, with modular components that allow balancing latency, accuracy, and cost. It is particularly well-suited for call analytics, captioning, voice user interfaces, agent handoffs, and accessibility scenarios, including multilingual deployments. Teams prioritizing open weights, transparent training recipes, and tight GPU performance controls will find it especially beneficial. However, for users primarily seeking a hosted API without customization, a managed service may be simpler to adopt.
GitHub, Inc.
San Francisco, California, US · Founded 2008
- Founders
- Tom Preston-Werner, Chris Wanstrath, PJ Hyett, Scott Chacon
- Founded
- 2008
- Headquarters
- San Francisco, California, US
- Legal status
- Subsidiary of Microsoft (NASDAQ: MSFT)
Key features
- Open-source PyTorch framework for ASR, TTS, and Speech LLMs
- State-of-the-art streaming and offline models with GPU-optimized kernels
- Modular architecture for balancing latency, accuracy, and cost
- Training recipes and data pipelines for large-scale supervised and self-supervised learning
- High-throughput inference on H100 and A100 GPUs with containerized environments
- Unified English model supporting both offline and streaming with punctuation and capitalization
- Open-weight TTS with multilingual voices and natural prosody
- Reproducible installs via uv, pip, or Docker with deterministic environments
- Full-duplex voice chat with interruptible, responsive agents
- Apache-2.0 licensing for internal adoption and compliance
Use cases
- Building and deploying real-time transcription systems for call analytics or live captioning
- Developing multilingual voice user interfaces or conversational agents with natural prosody
- Fine-tuning domain-specific speech models for accessibility tools or specialized audio processing
Pros
- Open-source framework with transparent training recipes and model weights
- Supports both Automatic Speech Recognition (ASR) and Text-to-Speech (TTS) with modular components
- Optimized for NVIDIA GPUs (e.g., H100, A100) with GPU-accelerated kernels
- Includes pre-trained checkpoints and training recipes for fast experimentation
- Enables deployment flexibility with Docker, pip, and uv installation options
Cons
- Primarily designed for technical users comfortable with PyTorch and GPU environments
- Requires customization for deployment, which may be complex for non-developers
- Not a managed service, so users must handle infrastructure and scaling themselves
Frequently asked questions about NVIDIA NeMo Speech
What is NVIDIA NeMo Speech used for?
NVIDIA NeMo Speech is a framework for building, training, and deploying speech AI models, including Automatic Speech Recognition (ASR) and Text-to-Speech (TTS). It supports research, experimentation, and production deployments for applications like call analytics, captioning, and voice interfaces.
Who is NVIDIA NeMo Speech designed for?
The tool is designed for researchers, developers, and applied ML teams working on speech AI. It is particularly suited for those who need customization, open weights, and tight control over GPU performance, such as research labs and platform teams.
How do I get started with NVIDIA NeMo Speech?
Users can install NeMo Speech via pip, uv, or Docker. The framework provides pre-trained checkpoints, training recipes, and scripts for transcription, synthesis, and fine-tuning. Documentation and examples are available in the GitHub repository.
Does NVIDIA NeMo Speech support multilingual models?
Yes, NeMo Speech includes multilingual models for both ASR and TTS, with support for languages such as English, Spanish, German, French, Vietnamese, Italian, Chinese, Hindi, Japanese, Arabic, Korean, and Portuguese.
Can NVIDIA NeMo Speech be used for streaming applications?
Yes, the framework supports streaming ASR and TTS models with controllable latency, enabling real-time applications such as voice chat and live transcription.
What are the deployment options for NVIDIA NeMo Speech?
NeMo Speech models can be exported as optimized artifacts and containerized for serving. The framework supports deployment on NVIDIA GPUs, with modular components to balance latency, accuracy, and cost.