GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.
OpenGauntlet
0Popularity
About OpenGauntlet
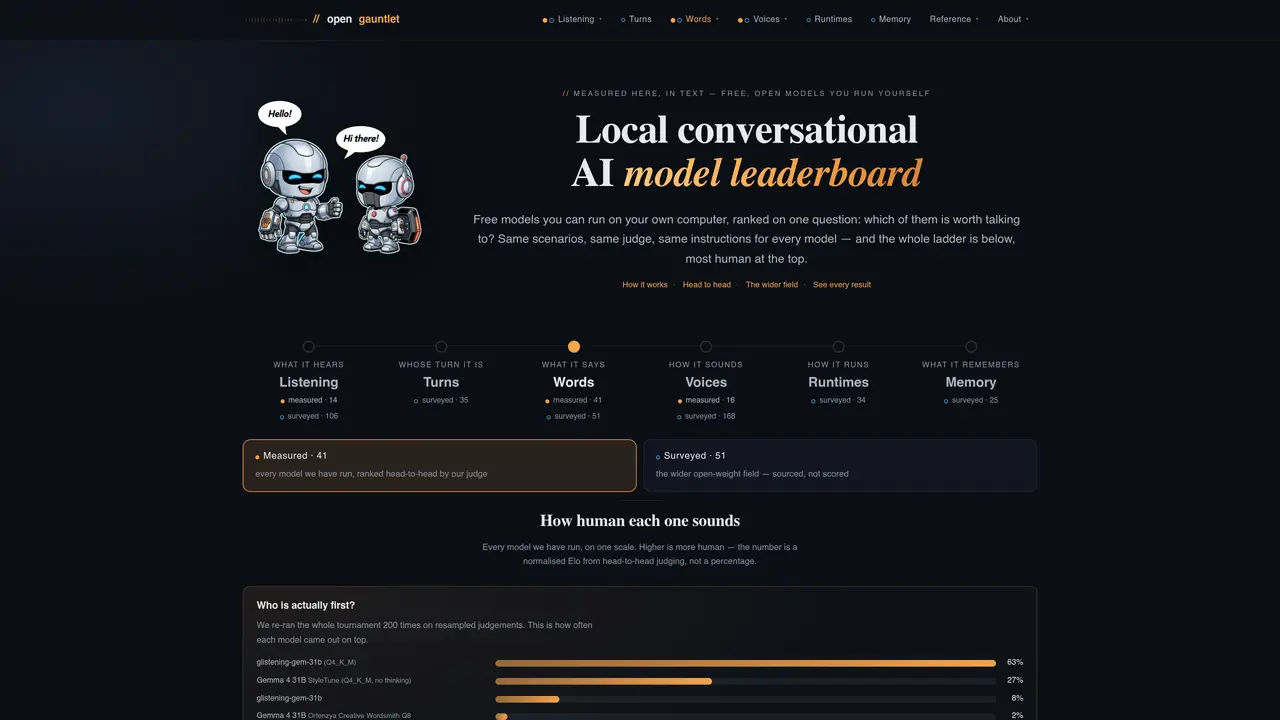
OpenGauntlet is a leaderboard and benchmarking system for local conversational AI models. It ranks free, open models that users can run on their own hardware by evaluating how human-like their responses sound in standardized chat scenarios. The platform measures multiple dimensions of conversational ability, including listening comprehension, turn-taking, word choice, voice quality, runtime speed, and memory usage. Each model is tested under identical conditions with the same judge, using GPT-5.4 to score responses on a normalized Elo scale. The leaderboard includes both models that have been directly benchmarked and a broader survey of open-weight models that have not been scored. Results are presented in a sortable table showing performance metrics across different hardware configurations, with models that exceed human reading speed marked accordingly. The project also provides research on model compression, orchestration, and hardware requirements to help users select appropriate models for their systems.
Key features
- Head-to-head model comparisons
- Standardized chat scenarios for consistent testing
- Multi-dimensional performance metrics
- Hardware-specific runtime measurements
- Normalized Elo scoring system
- Sortable leaderboard table
- Survey of open-weight models
- Research on model compression and orchestration
Use cases
- Selecting the most human-like local conversational AI model for personal use
- Comparing performance of different model variants on specific hardware
- Evaluating trade-offs between model size, speed, and conversational quality
Pros
- Ranks local models by human-likeness using standardized head-to-head judging
- Measures multiple conversational dimensions (listening, turns, words, voices, runtimes, memory)
- Provides hardware-specific performance data for different GPUs
- Includes both benchmarked and surveyed open-weight models
- Uses consistent judging criteria across all tested models
Cons
- Only evaluates free, open models that can run locally
- No direct comparison to proprietary or cloud-based models
- Surveyed models are not scored, only cataloged
- Requires local hardware to run models
Frequently asked questions about OpenGauntlet
What is OpenGauntlet?
OpenGauntlet is a leaderboard and benchmarking system for free, open conversational AI models that users can run on their own hardware. It ranks models based on how human-like their responses sound in standardized chat scenarios.
Who is OpenGauntlet designed for?
The platform is designed for users interested in evaluating and comparing local conversational AI models, particularly those who prioritize open-weight models and want to assess performance under identical conditions.
How does OpenGauntlet evaluate models?
Models are evaluated using a normalized Elo scale derived from head-to-head judging by GPT-5.4, measuring dimensions such as listening comprehension, turn-taking, word choice, voice quality, runtime speed, and memory usage.
Does OpenGauntlet include all open-weight models?
No, the leaderboard includes models that have been directly benchmarked, while a broader survey lists additional open-weight models that have not been scored but are included for reference.
What hardware configurations are included in the benchmarking?
The platform measures models across different hardware configurations, including systems like a DGX Spark, RTX 5090, and RTX 5080, with speed metrics provided in words per second.
Can users request to benchmark a specific model?
Yes, users can request a model to be added to the leaderboard, inspect published results, or flag claims that require further review through the platform's interface.