GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.
Requesty LLM Gateway
FreeStarting price
0Popularity
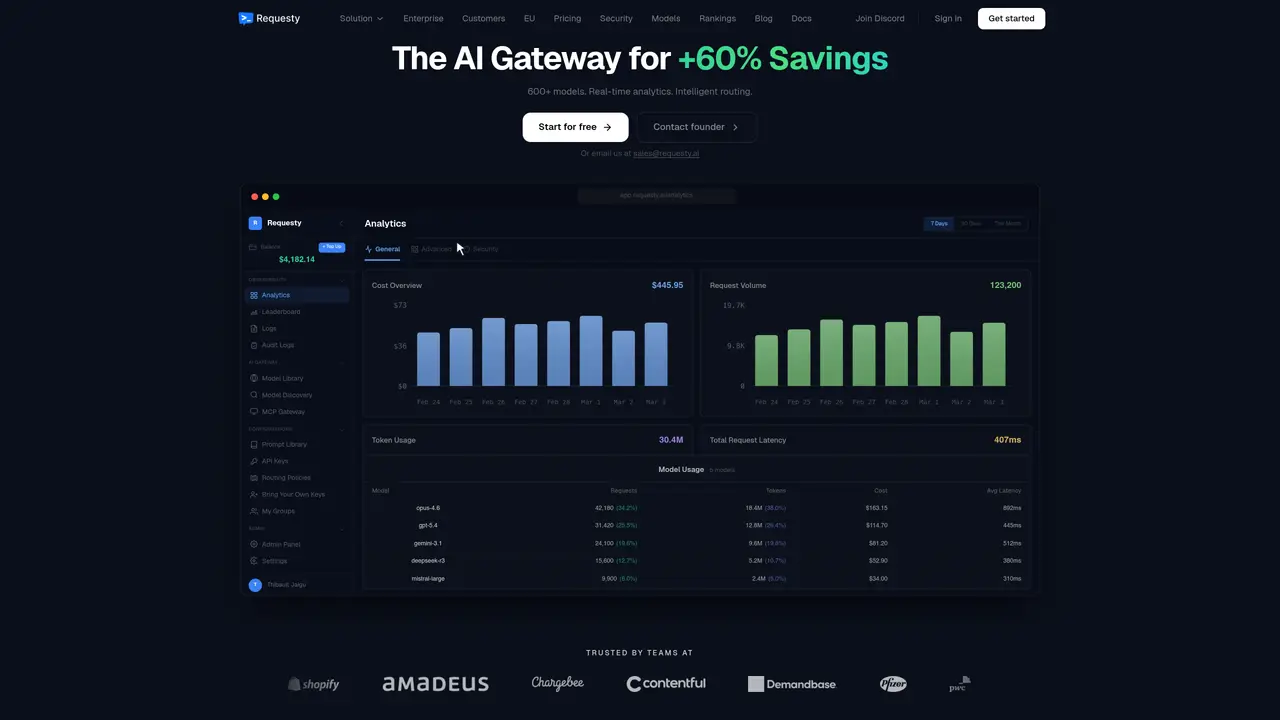
About Requesty LLM Gateway
Requesty is an LLM Gateway that functions as an intelligent middleware for all your LLM needs. Integrate with 200+ LLM providers by changing 1 value: your base URL. Use a single API key to access all the providers and forget about top-ups and rate limits. The moment you switch the base URL, you get: – Tracing: See all your LLM inference calls without changing anything in your code – Telemetry: See latency, request counts, caching rates and more without changing anything in your code – Billing: See exactly how much you spend with every provider and for every use case – Data security: Protect your PII and company secrets by masking them before they hit the LLM provider – Privacy: Restrict usage to providers in a specific region – Smart routing: Route requests based on Requesty’s smart routing classification model, saving cost and improving performance. Use Cases And Features 1. Access 200+ models using a single API key without any rate-limits 2. Get OpenAI compatible access to all LLM providers 3. Get aggregated tracing, telemetry and billing for all your LLM inference calls.
Key features
- Integrate with 200+ LLM providers
- Use a single API key to access all providers
- Tracing: See all LLM inference calls without changing code
- Telemetry: See latency, request counts, caching rates and more
- Billing: See exactly how much you spend with every provider
- Data security: Protect PII and company secrets by masking them
- Privacy: Restrict usage to providers in a specific region
- Smart routing: Route requests based on Requesty’s smart routing classification model
Use cases
- Access 200+ models using a single API key without rate-limits
- Get OpenAI compatible access to all LLM providers
- Get aggregated tracing, telemetry and billing for all LLM inference calls
Pros
- Unified access to 600+ LLM models via a single API key and base URL
- Real-time observability with cost, performance, and usage analytics across all providers
- Automatic failover and load balancing with sub-14ms switching between providers
- Enterprise-grade security including PII detection, content guardrails, and data residency controls
- OpenAI-compatible API enabling seamless integration with existing SDKs and workflows
Cons
- Requires initial setup to configure routing policies and security settings
- Dependency on third-party LLM providers for model availability and performance
- Potential latency introduced by gateway routing and security checks
- Enterprise features may require additional configuration and management
Frequently asked questions about Requesty LLM Gateway
What is Requesty?
Requesty is an AI gateway that acts as a middleware between applications and over 600 LLM providers, offering real-time analytics, intelligent routing, and observability for AI infrastructure.
Who should use Requesty?
Requesty suits teams and enterprises that rely on multiple LLM providers and need centralized control over costs, performance, security, and data residency.
How does Requesty handle data security and privacy?
Requesty provides PII detection and scrubbing to redact sensitive data before it reaches LLM providers, along with content guardrails and geo-based routing to ensure data residency compliance.
Can Requesty integrate with existing applications easily?
Yes, Requesty offers an OpenAI-compatible API that works with existing SDKs, requiring minimal code changes for integration.
Does Requesty support failover and load balancing?
Requesty includes automatic failover and load balancing, switching traffic to the next best provider in under 14ms if a provider goes down, ensuring zero downtime.
What kind of analytics does Requesty provide?
Requesty offers real-time observability with cost analytics, performance monitoring, usage insights, and agent-specific metrics to track spending, latency, and success rates across all providers.