GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.
Inferect
$149/moStarting price
0Popularity
About Inferect
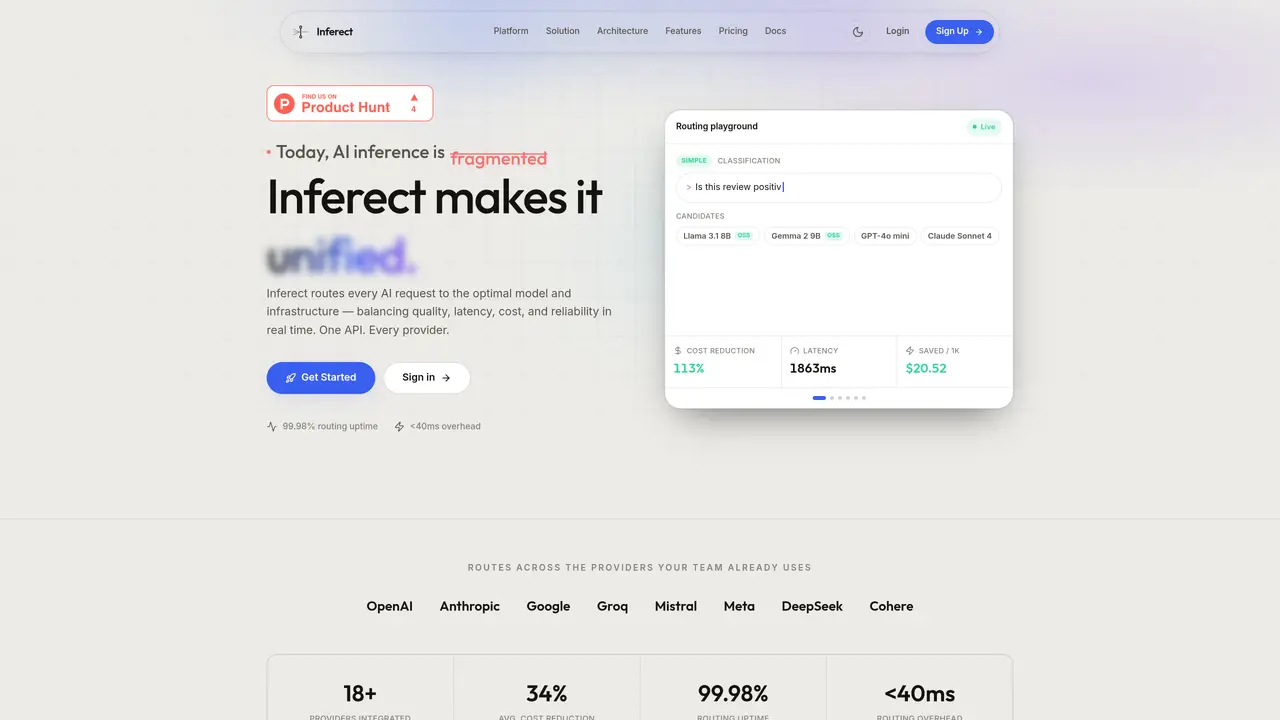
Inferect acts as a middleware gateway between applications and AI model providers, dynamically routing each inference request to the optimal model and infrastructure in real time. It balances cost, latency, quality, and reliability by scoring and selecting the best provider for each task without requiring code changes. The platform integrates with existing providers such as OpenAI, Anthropic, Google, Groq, Mistral, Meta, and DeepSeek, allowing teams to leverage multiple services through a single API. It provides observability features including cost tracking, latency analytics, and unified dashboards for every request from prompt to response. Additional capabilities include semantic caching to avoid redundant token billing, automatic failover for reliability, and load balancing to manage rate limits at scale. Security features include key isolation and audit logging, while the platform supports self-hosting or managed deployment options.
Key features
- Smart routing based on cost, latency, and quality signals
- Semantic caching for instant repeat request handling
- Multi-provider inference with single API integration
- Automatic failover and load balancing
- Unified observability dashboard for all requests
- Model benchmarking and live quality signals
- Key isolation and audit logging for security
- REST API and TypeScript/Python SDKs
Use cases
- Optimizing AI inference costs across multiple providers
- Improving inference reliability with automatic failover
- Reducing latency by routing around slow providers
Pros
- Real-time routing optimization across multiple providers
- Unified observability for cost, latency, and quality metrics
- Semantic caching to reduce token costs on repeat requests
- Automatic failover and load balancing for reliability
- Supports 18+ major AI model providers
Cons
- No free tier beyond developer testing limits
- Pricing includes usage-based fees on top of flat rates
- Requires integration with existing provider accounts
- Limited to AI inference use cases only
Frequently asked questions about Inferect
What is Inferect?
Inferect is an intelligence layer for AI inference that routes each request to the optimal model and infrastructure in real time, balancing cost, latency, quality, and reliability. It acts as a middleware gateway between applications and AI model providers, supporting over 18 providers through a single API.
Who should use Inferect?
Inferect is designed for AI teams and developers who need to optimize inference costs, latency, and reliability across multiple providers. It suits production environments requiring observability, failover, and load balancing without code changes.
How does Inferect optimize inference requests?
Inferect scores and routes each request to the best model based on real-time signals for cost, latency, and quality. It includes features like semantic caching, automatic failover, load balancing, and multi-provider integration to ensure optimal performance.
Does Inferect support self-hosting?
Yes, Inferect offers both self-hosted and managed deployment options. Users can bring their own keys or opt for a fully managed solution with a single flat price for the team.
What integrations does Inferect support?
Inferect integrates with major providers including OpenAI, Anthropic, Google, Groq, Mistral, Meta, DeepSeek, Cohere, and others. It provides a unified API to access these providers without modifying existing code.
How do I get started with Inferect?
Users can start with Inferect's free tier for testing, which includes low limits and no credit card requirement. For production use, they can sign up for a plan and integrate the SDK or REST API into their applications.