GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.
SEAL Leaderboard
0Popularity
About SEAL Leaderboard
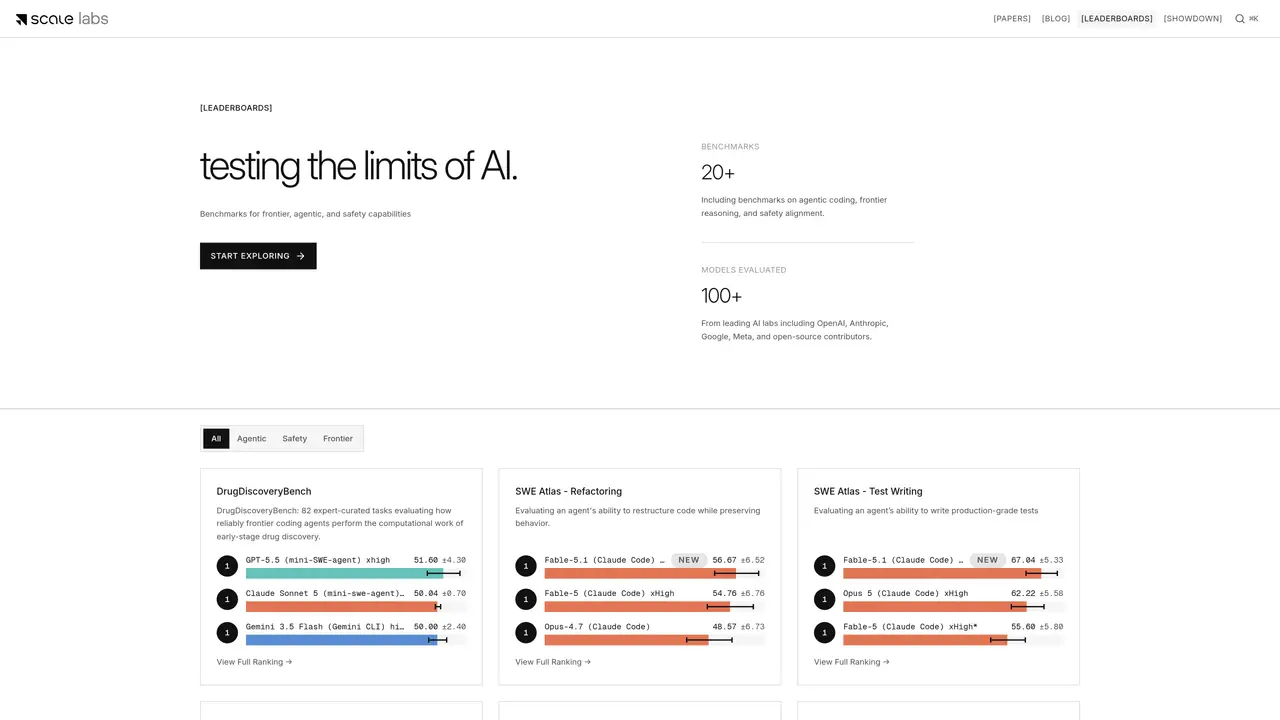
Scale SEAL Leaderboards is an AI evaluation platform that provides authoritative rankings of large language models by measuring their performance across key domains such as coding, math, instruction following, multilingual capabilities, and safety alignment. The platform uses advanced AI-powered evaluation methods that incorporate real-world usage metrics and human preferences from a global user base to deliver tamperproof and comprehensive results. It features specialized benchmarks like SEAL Showdown and SWE Atlas, which analyze millions of real conversations and assess agentic behaviors including code refactoring, test writing, and deep code comprehension. Researchers, enterprises, and developers rely on SEAL Leaderboards to make informed decisions about selecting AI models that best fit their specific needs, whether for frontier reasoning, professional applications, or multimodal interactions. The platform includes over 20 benchmarks covering frontier models, agentic capabilities, and safety evaluations, with models evaluated from leading AI labs such as OpenAI, Anthropic, Google, Meta, and open-source contributors. Benchmarks like DrugDiscoveryBench, SWE-Bench Pro, and Humanity’s Last Exam assess specialized tasks ranging from early-stage drug discovery to long-horizon software engineering and frontier human knowledge challenges.
Key features
- Authoritative rankings of large language models
- Evaluation across coding, math, instruction following, and multilingual capabilities
- SEAL Showdown for analyzing real conversations and human preferences
- Demographically segmented insights from global users
- Tamperproof and comprehensive evaluations
- AI-powered evaluation methodologies
- Curated private datasets for accurate assessments
- Real-world usage metrics for genuine performance insights
Use cases
- Comparing large language models for research purposes
- Selecting the best AI model for enterprise or development needs
- Evaluating model performance in specific domains like coding or multilingual tasks
Pros
- Provides authoritative rankings of large language models across diverse domains such as coding, math, and multilingual capabilities
- Uses real-world usage metrics and human preferences from global users for tamperproof evaluations
- Features specialized benchmarks like SEAL Showdown and SWE Atlas for agentic and safety capabilities
- Covers over 20 benchmarks, including frontier reasoning, agentic coding, and safety alignment
- Evaluates models from leading AI labs such as OpenAI, Anthropic, Google, and Meta
Cons
- Evaluations may not fully capture nuanced real-world performance due to reliance on curated datasets
- Limited transparency in proprietary evaluation methodologies may hinder interpretability for some users
Frequently asked questions about SEAL Leaderboard
What does Scale SEAL Leaderboards do?
Scale SEAL Leaderboards provides authoritative rankings of large language models by evaluating their performance across domains such as coding, math, instruction following, multilingual capabilities, and safety alignment using real-world usage metrics and human preferences.
Who is SEAL Leaderboards designed for?
The platform is designed for researchers, enterprises, and developers who need to make informed decisions about selecting AI models that best suit their specific needs based on comprehensive and tamperproof evaluations.
How does SEAL Leaderboards evaluate models?
SEAL Leaderboards uses carefully curated private datasets and real-world usage metrics, combined with human preferences from diverse global users, to ensure evaluations reflect genuine performance rather than artificially optimized benchmark results.
What types of benchmarks are included in SEAL Leaderboards?
The platform includes over 20 benchmarks covering frontier reasoning, agentic coding, safety alignment, professional reasoning in fields like finance and legal practice, and multimodal interactions such as vision-language understanding.
Can SEAL Leaderboards evaluate agentic capabilities?
Yes, SEAL Leaderboards features specialized benchmarks like SWE Atlas, which evaluates agentic behaviors such as code refactoring, test writing, codebase Q&A, and tool use through the Model Context Protocol (MCP).
How do I get started with SEAL Leaderboards?
Users can start exploring the benchmarks and rankings by visiting the Scale Labs website, where they can access detailed evaluations and full rankings across various AI models and capabilities.