OpenAI builds and deploys advanced AI models like GPT-4o for autonomous agents and workflows.

RAG-Anything
$0.07Starting price
0Popularity
About RAG-Anything
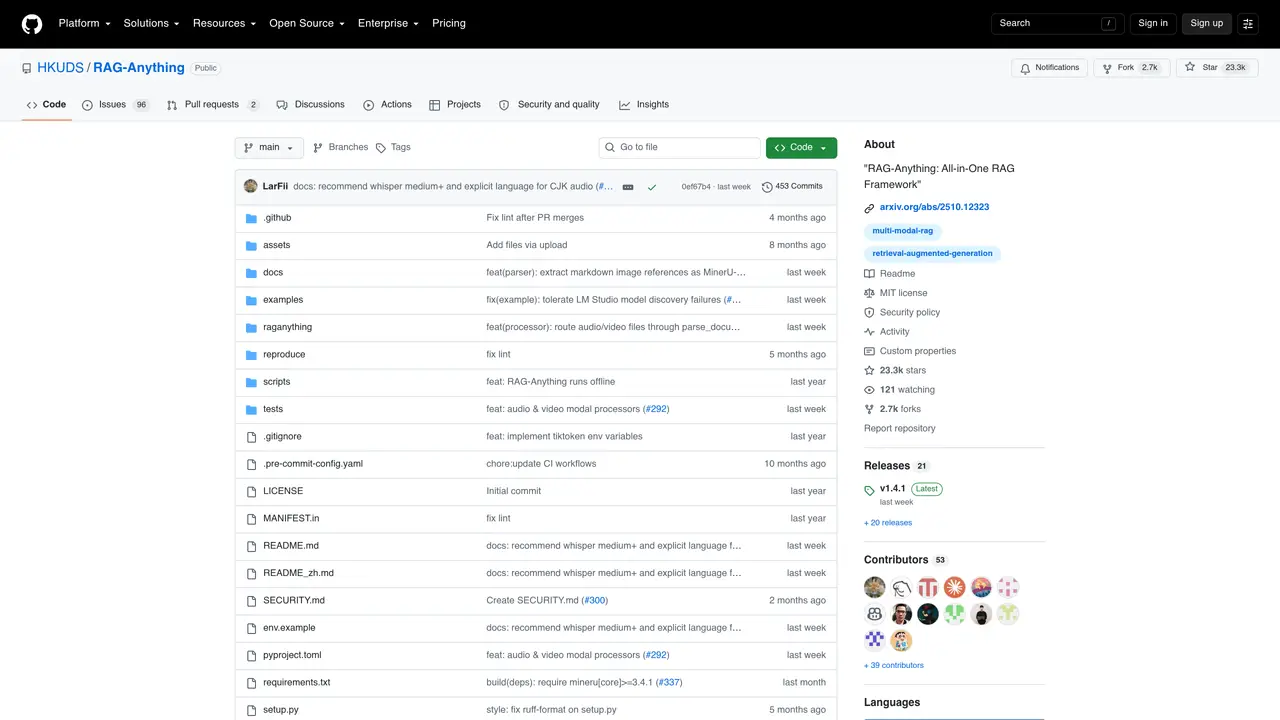
RAG-Anything is an open-source all-in-one multimodal RAG framework designed to help developers build advanced knowledge retrieval systems from complex documents. It processes and indexes mixed-content files including PDFs, Office documents, images, tables, equations, charts, and other structured elements into a unified retrieval framework. The tool combines document parsing, multimodal content understanding, knowledge graph indexing, vector-graph retrieval, and VLM-enhanced querying to transform documents into searchable, graph-connected knowledge systems. It supports specialized processors for visual, tabular, mathematical, and textual content, enabling richer contextual answers across modalities. Ideal for AI engineers, data teams, researchers, and enterprise knowledge builders, RAG-Anything is used to create document intelligence systems, multimodal knowledge graphs, and hybrid retrieval pipelines that fuse semantic search with graph traversal and modality-aware ranking. The framework is extensible, allowing configuration of parsers, LLMs, embeddings, and vision models to suit different document types and use cases.
GitHub, Inc.
San Francisco, California, US · Founded 2008
- Founders
- Tom Preston-Werner, Chris Wanstrath, PJ Hyett, Scott Chacon
- Founded
- 2008
- Headquarters
- San Francisco, California, US
- Legal status
- Subsidiary of Microsoft (NASDAQ: MSFT)
Key features
- Processes PDFs, Office documents, images, tables, equations, and charts in a single framework
- Builds multimodal knowledge graphs preserving relationships across text, visuals, tables, and formulas
- Supports VLM-enhanced querying for combined visual and textual context
- Implements vector-graph fusion retrieval with modality-aware ranking
- Includes specialized processors for visual, tabular, mathematical, and textual content
- Enables document intelligence systems for research, reports, manuals, and enterprise knowledge bases
- Supports hybrid retrieval combining semantic search, graph traversal, and modality-aware ranking
- Configurable parsers, LLMs, embeddings, and vision models for flexible deployment
Use cases
- Build RAG pipelines over PDFs, Office documents, reports, and technical files
- Query documents containing images, diagrams, charts, tables, and visual context
- Create multimodal knowledge graphs connecting text, tables, equations, and visual entities
Pros
- Supports end-to-end multimodal document processing from ingestion to querying
- Handles mixed-content files including PDFs, Office documents, images, tables, equations, and charts
- Integrates specialized processors for visual, tabular, mathematical, and textual content
- Features a multimodal knowledge graph for automatic entity extraction and cross-modal relationship discovery
- Offers adaptive processing modes and direct content list insertion for flexibility
Cons
- Requires technical expertise to configure and deploy due to its open-source nature
- May demand significant computational resources for processing large or complex documents
- Limited official documentation beyond GitHub repository and technical report
Frequently asked questions about RAG-Anything
What is RAG-Anything and what does it do?
RAG-Anything is an open-source all-in-one multimodal RAG framework designed to build advanced knowledge retrieval systems from complex documents. It processes and indexes mixed-content files such as PDFs, Office documents, images, tables, equations, and charts into a unified retrieval framework.
Who is RAG-Anything suitable for?
The tool is ideal for AI engineers, data teams, researchers, and enterprise knowledge builders who need to create document intelligence systems, multimodal knowledge graphs, and hybrid retrieval pipelines.
Does RAG-Anything support multimodal queries?
Yes, RAG-Anything supports multimodal query capabilities, enabling enhanced RAG with seamless processing of text, images, tables, and equations within a single framework.
How does RAG-Anything handle documents with images?
When documents include images, RAG-Anything seamlessly integrates them into VLM-enhanced query mode for advanced multimodal analysis, combining visual and textual context for deeper insights.
Can I use RAG-Anything without parsing documents?
Yes, RAG-Anything allows direct content list insertion by bypassing document parsing and inserting pre-parsed content lists from external sources.
Is RAG-Anything extensible?
Yes, the framework is extensible, allowing configuration of parsers, LLMs, embeddings, and vision models to suit different document types and use cases.