AI-powered writing tool for paraphrasing, summarizing, and enhancing writing effortlessly.

RAKE
$0.07Starting price
0Popularity
About RAKE
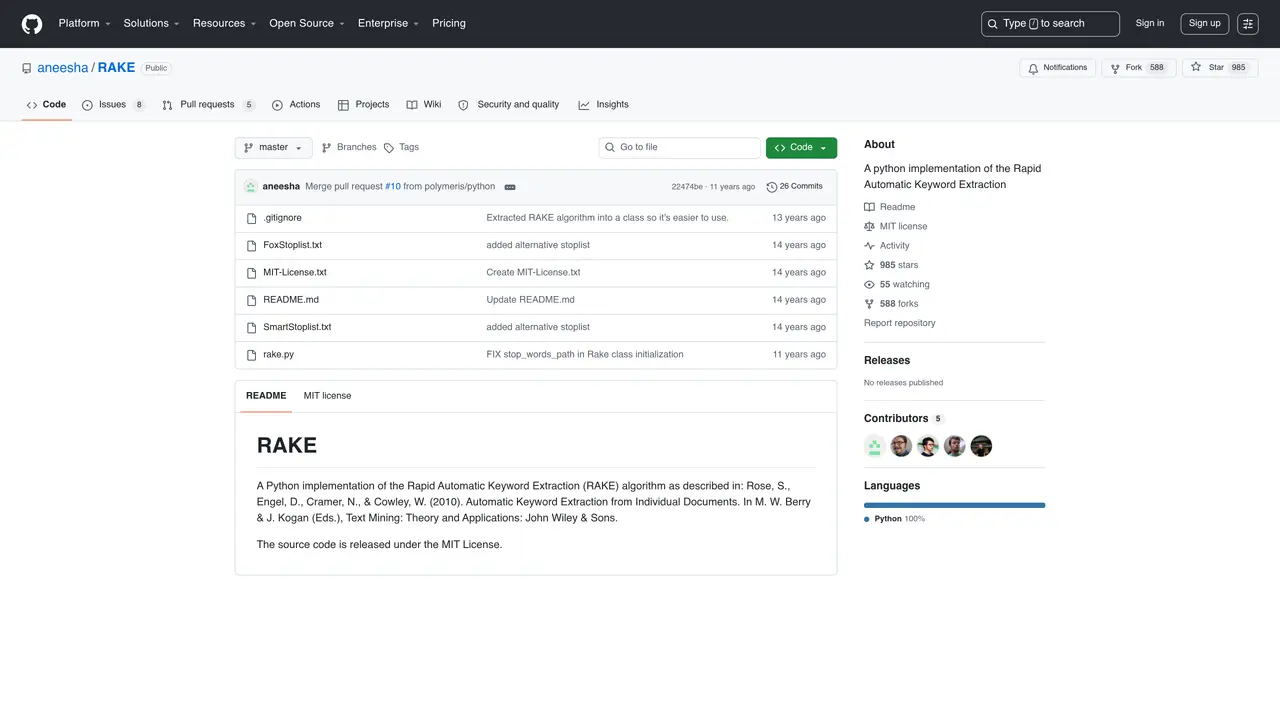
RAKE (Rapid Automatic Keyword Extraction) is an open-source algorithm designed for extracting keywords and key phrases from text documents. It operates by identifying stop words and phrase delimiters to determine candidate keywords, then scoring these candidates based on their frequency and co-occurrence within the text. The tool is particularly useful for processing large volumes of unstructured text, enabling users to quickly distill key topics and themes without manual intervention. The algorithm is language-agnostic and does not rely on predefined dictionaries or training data, making it adaptable to various languages and domains. RAKE is commonly employed in text summarization, content analysis, and information retrieval tasks, where it helps researchers, marketers, and businesses gain insights from textual data. Its simplicity and efficiency make it a practical choice for applications requiring rapid keyword extraction and topic modeling.
GitHub, Inc.
San Francisco, California, US · Founded 2008
- Founders
- Tom Preston-Werner, Chris Wanstrath, PJ Hyett, Scott Chacon
- Founded
- 2008
- Headquarters
- San Francisco, California, US
- Legal status
- Subsidiary of Microsoft (NASDAQ: MSFT)
Key features
- Generate tag clouds
- Automatically identify keywords
- Summarize large texts
- Use natural language processing and machine learning algorithms
- Analyze and extract meaningful keywords from unstructured text
- Identify key topics and trends in documents
Use cases
- Businesses can use RAKE to quickly identify important words and phrases within large amounts of text, making it easier to get a quick overview of the content.
- Researchers can use RAKE to extract meaningful keywords from unstructured text, allowing them to identify key topics and trends in documents.
- Marketers can use RAKE to generate tag clouds and other visualizations of text data, helping them gain insights and make decisions.
Pros
- Open-source implementation of a well-established keyword extraction algorithm
- Lightweight and easy to integrate into Python-based workflows
- No manual keyword research required, enabling automated processing of large text volumes
- Supports customization through configurable stoplists for domain-specific use cases
- Widely cited and validated in academic literature for keyword extraction tasks
Cons
- Limited to keyword extraction without additional NLP features like sentiment analysis or entity recognition
- Performance heavily depends on the quality and relevance of input text preprocessing
- No built-in visualization tools, requiring external libraries for tag clouds or data representation
Frequently asked questions about RAKE
What is RAKE and how does it work?
RAKE is a Python implementation of the Rapid Automatic Keyword Extraction algorithm, designed to automatically identify and extract keywords from unstructured text. It analyzes text to determine meaningful phrases based on stopwords and phrase delimiters, as described in the original research by Rose et al. (2010).
Who should use RAKE?
RAKE is suitable for researchers, data analysts, marketers, and developers who need to process large volumes of text to extract key terms efficiently. It is particularly useful for tasks like document summarization, topic identification, and content analysis.
How do I get started with RAKE?
To use RAKE, clone the GitHub repository and install the required dependencies. The tool can then be integrated into Python scripts or used via command-line execution to process text files or strings directly.
Does RAKE support multiple languages?
RAKE is primarily designed for English text, as it relies on language-specific stopword lists. Users may need to customize stopword lists or adapt the algorithm for other languages.
Can RAKE be integrated with other tools or platforms?
RAKE is a standalone Python library and can be integrated into larger workflows or systems that support Python scripts. It does not natively include integrations with third-party platforms but can be embedded in custom applications.
What are the limitations of RAKE?
RAKE may struggle with highly technical or domain-specific jargon that is not captured in its stopword lists. Additionally, its performance depends on the quality of input text preprocessing, such as sentence tokenization and stopword removal.