Automate complex processes, leverage real-time analytics, customize workflow with powerful tools.

BrowserAct
$179.99Starting price
0Popularity
About BrowserAct
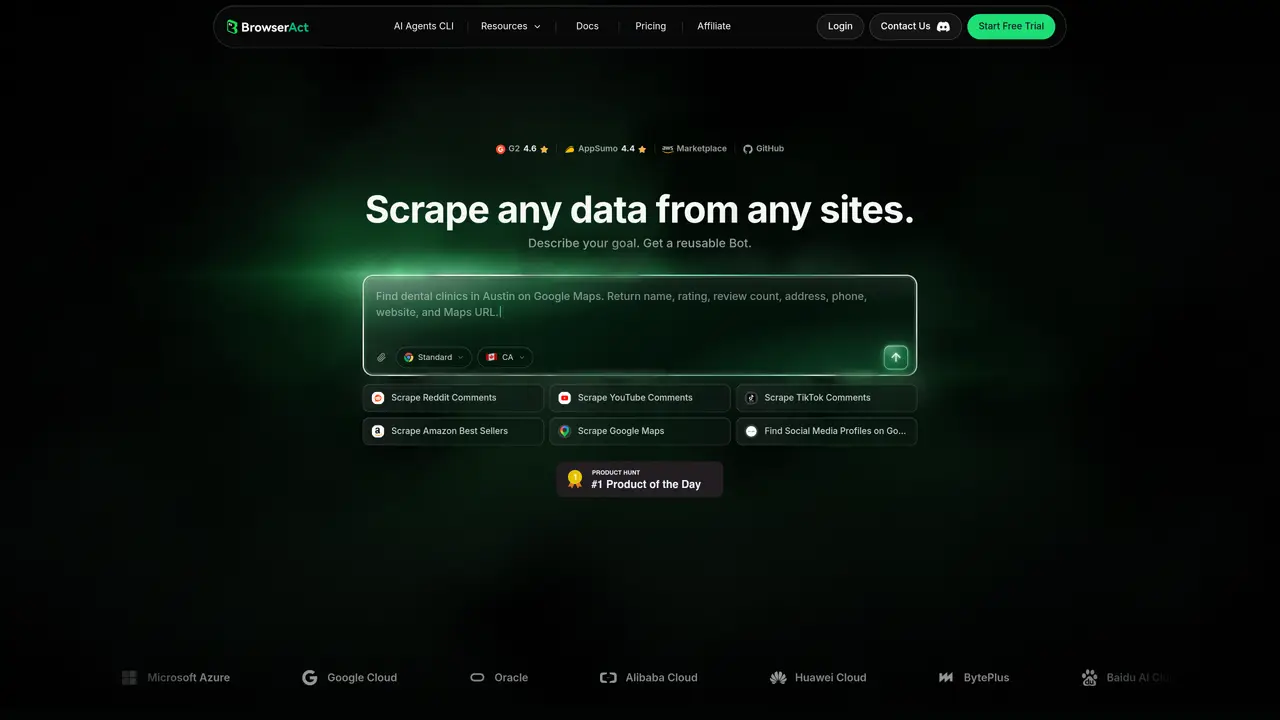
BrowserAct is an AI-powered cloud browser platform designed to automate data extraction and interaction tasks on any website through natural language commands, eliminating the need for coding expertise. The platform enables users to scrape data, fill out forms, navigate dynamic pages, and handle CAPTCHAs reliably, even on long-tail websites that lack dedicated APIs or prebuilt scrapers. BrowserAct automatically adapts to changes in website layouts or DOM structures, ensuring consistent performance without manual adjustments. Its agent-oriented structured output feature generates clean, usable data formats suitable for AI agent inputs and retrieval-augmented generation (RAG) pipelines. The tool is particularly useful for tasks requiring interaction with complex or JavaScript-heavy websites, where traditional scraping methods often fail. Users can define automation workflows in plain language, making the platform accessible to non-technical professionals while still offering robust capabilities for developers. BrowserAct supports a wide range of use cases, from market research and lead generation to real-time data monitoring and automated testing. By combining natural language processing with browser automation, it bridges the gap between manual browsing and fully automated data extraction.
Key features
- Natural Language Scraping (no code required)
- Reliable CAPTCHA Handling and simulation
- Agent-Oriented Structured Output
- Form Automation and Interaction
- Broad Website Compatibility
- Adapts automatically to layout or DOM changes
Use cases
- Extract data from complex websites using natural language
- Automate form filling and interactions across dynamic websites
- Generate structured output directly usable for AI agent input and RAG pipelines
Pros
- No-code natural language scraping for structured data extraction from any website
- Automated CAPTCHA handling and recovery from page changes without manual intervention
- Reusable Bots that adapt to layout or DOM changes, reducing maintenance overhead
- Managed infrastructure including browsers, proxies, and scheduling for reliable scaling
- Flexible result delivery via CSV, JSON, APIs, webhooks, or integrations with Make, n8n, and Zapier
Cons
- Dependence on cloud-based execution may introduce latency for real-time tasks
- Limited control over underlying browser behavior compared to local scraping solutions
- Potential cost accumulation for high-volume or long-running automated tasks
- May require adjustments for websites with complex JavaScript-driven interactions
BrowserAct videos
Frequently asked questions about BrowserAct
What is BrowserAct and what does it do?
BrowserAct is an AI-powered cloud browser platform that enables users to extract structured data and automate web tasks using natural language prompts without requiring coding skills. It builds reusable bots that can collect data, interact with forms, and handle complex websites reliably.
Who should use BrowserAct?
BrowserAct is designed for teams and individuals who need to scrape data from websites, automate form interactions, or generate structured outputs for AI agents and RAG pipelines. It suits users without technical expertise as well as developers seeking managed web scraping infrastructure.
How does BrowserAct handle CAPTCHAs and website changes?
BrowserAct automatically handles common CAPTCHAs like reCAPTCHA and Turnstile, and adapts to page layout or DOM changes to maintain reliable scraping. It detects page changes and recovers broken paths with minimal manual intervention.
Can BrowserAct integrate with other tools or platforms?
Yes, BrowserAct supports flexible result delivery through CSV or JSON downloads, APIs, webhooks, and integrations with automation platforms like Make, n8n, and Zapier. It can also be used to provide browsers for custom AI agents.
What kind of websites can BrowserAct scrape?
BrowserAct is compatible with a wide range of websites, including long-tail sites not covered by typical APIs or prebuilt scrapers. It works with real Chromium browsers and global residential proxies to access content from different regions.
How do I get started with BrowserAct?
Users can start by describing their data extraction or automation goal in natural language, and BrowserAct will build a reusable bot. The platform manages browsers, proxies, CAPTCHAs, and scheduling, allowing users to run tasks immediately or on a schedule.