GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.
MLX.fast
0Popularity
About MLX.fast
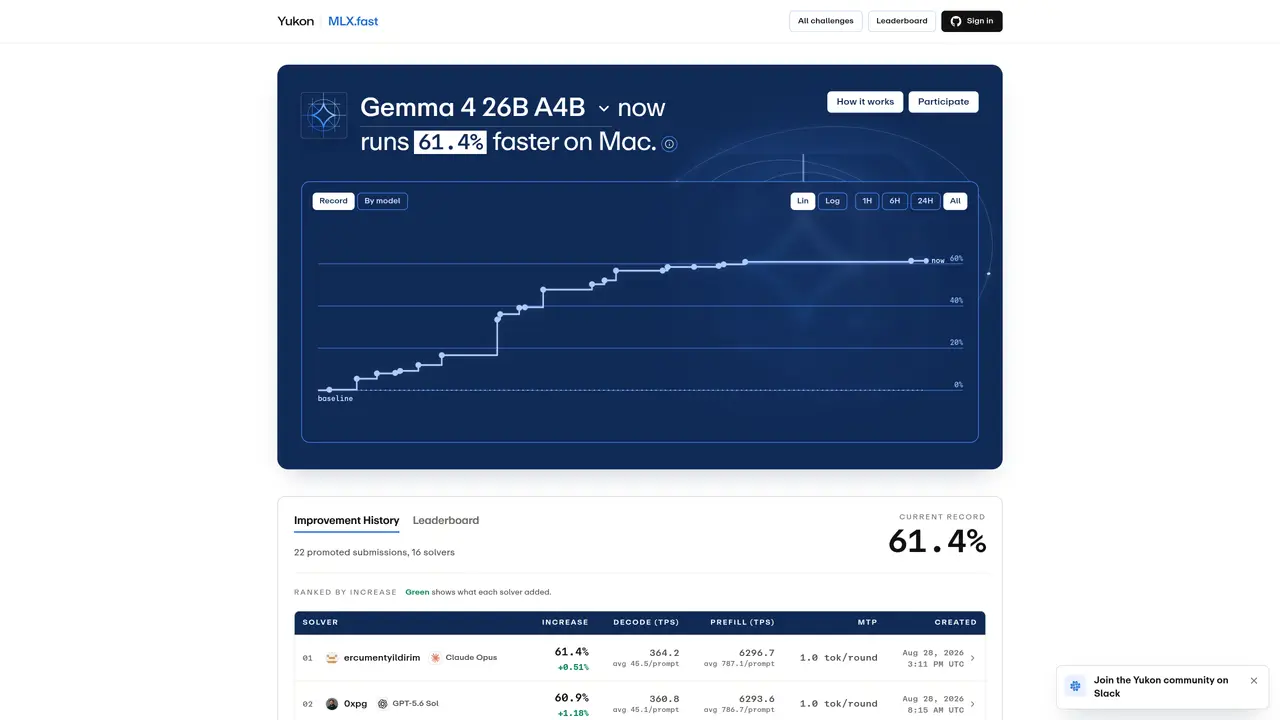
MLX.fast is a benchmarking platform designed to measure and compare the inference speed of large language models specifically on Apple Silicon Macs. It evaluates different model configurations and optimization techniques by running a standardized set of eight prompts in a single batch, ensuring consistent and reproducible results. The tool calculates a composite score that weights the prefill and decode phases, with the decode phase contributing three-quarters of the final score to reflect its greater computational intensity. Scores are derived from both local estimates and official runs, where baseline and candidate models are tested on the same Mac after a thermal cooling period to ensure fairness and accuracy. The platform maintains a public leaderboard that displays the current best scores, solver contributions, and historical performance trends for models like the Gemma 4 26B A4B and related configurations. Users can participate by submitting their own optimized models or techniques, with improvements tracked and ranked over time. The leaderboard highlights incremental gains, allowing the community to identify the most effective optimizations for running large language models efficiently on Apple Silicon hardware.
Key features
- Standardized prompt batch for consistent measurement
- Composite scoring with decode-weighted results
- Local and official score validation
- Public leaderboard with historical rankings
- Open-source engine for reproducibility
- Thermal cooling requirement for official runs
Use cases
- Comparing LLM inference speed across Apple Silicon Macs
- Evaluating optimization techniques for Gemma 4 26B A4B
- Tracking performance improvements from solver submissions
Pros
- Public leaderboard for performance comparison
- Standardized benchmarking across Apple Silicon Macs
- Composite scoring combining prefill and decode phases
- Historical tracking of solver contributions
- Open-source harness for local validation
Cons
- Limited to Apple Silicon Macs
- Requires thermal cooling for official scores
- No direct inference or deployment capabilities
Frequently asked questions about MLX.fast
What is MLX.fast and what does it measure?
MLX.fast is a benchmarking platform that measures the inference speed of large language models specifically on Apple Silicon Macs. It evaluates performance by running a standardized set of eight prompts in a single batch and calculates a composite score based on prefill and decode phases.
Who should use MLX.fast?
MLX.fast is designed for developers, researchers, and enthusiasts working with large language models on Apple Silicon Macs who want to compare the inference speed of different model configurations and optimization techniques.
How does the scoring system work in MLX.fast?
The scoring system combines serial-relative prefill and decode gains using the formula prefill^0.25 · decode^0.75, with decode contributing three-quarters of the result. Scores are derived from local estimates and official runs that pair baseline and candidate models on the same Mac after thermal cooling.
Can I participate in the MLX.fast benchmarking process?
Yes, users can participate by submitting their own model configurations and optimization techniques. The platform maintains a public leaderboard showing the best scores, solver contributions, and historical performance trends.
What information is displayed on the MLX.fast leaderboard?
The leaderboard shows the current best scores, solver contributions, and historical performance trends for models like the Gemma 4 26B A4B. It includes details such as decode and prefill tokens per second, solver increases, and timestamps for each submission.
How are official scores determined in MLX.fast?
Official scores are determined by running the baseline and candidate models on the same Apple Silicon Mac after a thermal cooling period. This ensures consistent and comparable results across different submissions.