GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.

LEANN
$0.07Starting price
0Popularity
About LEANN
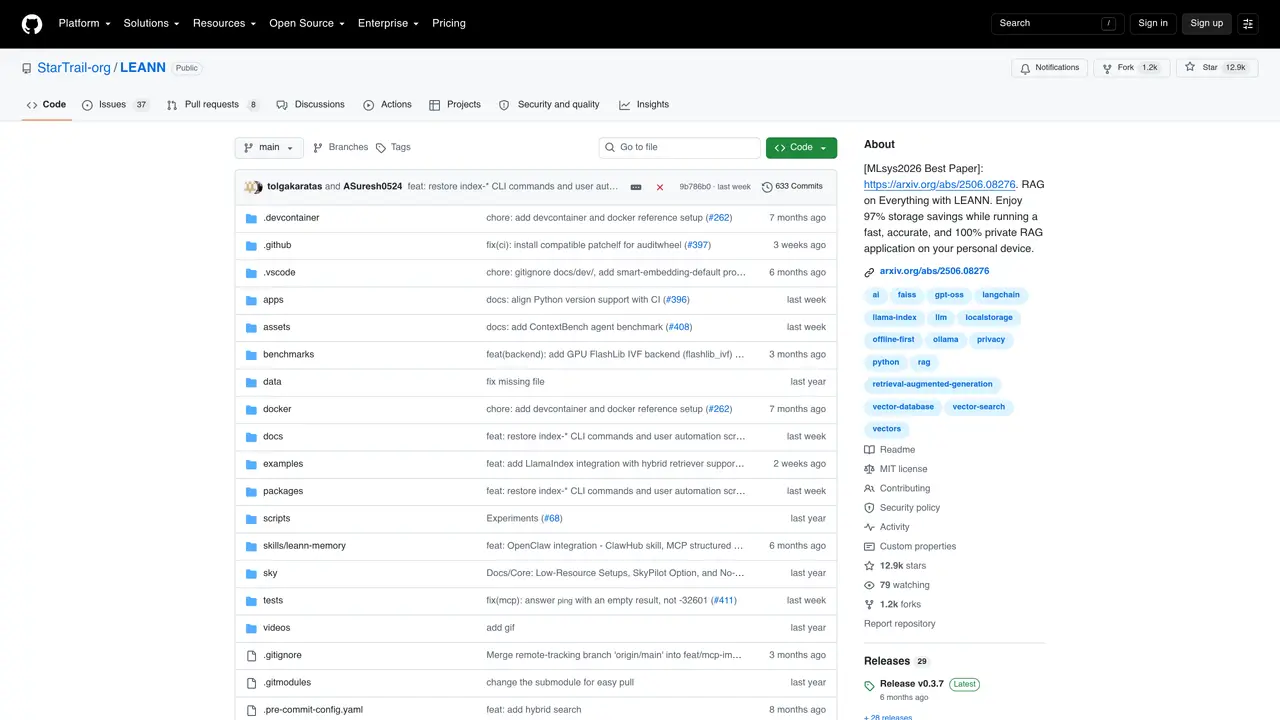
LEANN is a local-first vector database and RAG runtime designed for fast, accurate retrieval over large personal or team knowledge bases without cloud dependency. It indexes millions of document chunks in gigabytes of storage while preserving retrieval quality through graph pruning. At query time, it selectively recomputes embeddings only for relevant candidates, reducing storage overhead and enabling flexible model swaps without rebuilding indexes. The system supports both HNSW and DiskANN indexing backends, allowing users to balance latency, accuracy, and memory usage based on their hardware constraints. LEANN integrates with OpenAI-compatible APIs or local LLM engines like Ollama and vLLM, enabling standardized workflows that can switch providers without changing code. Data remains entirely on-device, with no telemetry collected, making it suitable for privacy-sensitive applications such as personal knowledge management, secure document search, or offline agent prototyping. The tool is equally useful for indie developers testing RAG systems, enterprise teams validating on-device retrieval, or researchers curating portable knowledge bases across multiple machines. Installation is flexible, supporting pip/uv or source builds, with built-in support for ingesting diverse data sources like documents, code, emails, browser history, and chat exports. Configuration options include backend selection, graph degree tuning, and search complexity adjustments to optimize performance for specific hardware setups.
GitHub, Inc.
San Francisco, California, US · Founded 2008
- Founders
- Tom Preston-Werner, Chris Wanstrath, PJ Hyett, Scott Chacon
- Founded
- 2008
- Headquarters
- San Francisco, California, US
- Legal status
- Subsidiary of Microsoft (NASDAQ: MSFT)
Key features
- Local-first vector database with on-device processing
- Selective embedding recomputation at query time
- Support for HNSW and DiskANN indexing backends
- OpenAI-compatible API integration for LLMs and embeddings
- Graph pruning for memory-efficient high-degree preservation
- CSR format storage for cache-friendly traversal
- No telemetry or cloud dependency
- Built-in ingestion for documents, code, emails, and chat exports
- Tunable graph degree and search complexity
- Portable index export and identical retrieval quality across devices
Use cases
- Private knowledge base search across personal documents and communications
- Offline RAG prototyping for developers using local LLMs
- Enterprise validation of on-device retrieval systems for sensitive data
Pros
- Achieves up to 97% storage savings compared to traditional vector databases without compromising retrieval accuracy
- Enables fully private, on-device RAG applications with zero telemetry or cloud dependency
- Supports indexing and semantic search across diverse personal data sources like documents, emails, browser history, and chat exports
- Offers flexible backend options (HNSW and DiskANN) to balance latency, accuracy, and memory usage based on hardware constraints
- Provides portable knowledge bases that can be transferred between devices with minimal overhead
Cons
- Requires local hardware capable of handling graph-based recomputation and on-demand embedding generation
- Limited GPU acceleration support compared to cloud-based vector databases, potentially affecting performance for large-scale queries
Frequently asked questions about LEANN
What is LEANN and what does it do?
LEANN is a local-first vector database and RAG runtime designed to enable fast, accurate retrieval over large personal or team knowledge bases entirely on-device. It indexes millions of document chunks while preserving retrieval quality through graph pruning and selective recomputation of embeddings.
Who is LEANN suitable for?
LEANN is suitable for privacy-sensitive users such as individuals managing personal knowledge, enterprise teams validating on-device retrieval, indie developers testing RAG systems, and researchers curating portable knowledge bases across multiple machines.
Does LEANN require cloud services or internet access?
No, LEANN operates entirely offline with no telemetry collected, ensuring complete data privacy and eliminating cloud costs.
What data sources can LEANN index?
LEANN can ingest and index diverse data sources including documents, code, emails, browser history, chat exports, and external knowledge bases.
How does LEANN handle storage efficiency?
LEANN uses graph-based selective recomputation and smart graph pruning to minimize storage overhead, achieving significant reductions compared to traditional vector databases.
How do I get started with LEANN?
Users can install LEANN via pip/uv or source builds, configure backend settings, and ingest their data sources. The tool provides built-in support for various data formats and integrates with local LLM engines or OpenAI-compatible APIs.