GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.

NVIDIA TensorRT
0Popularity
About NVIDIA TensorRT
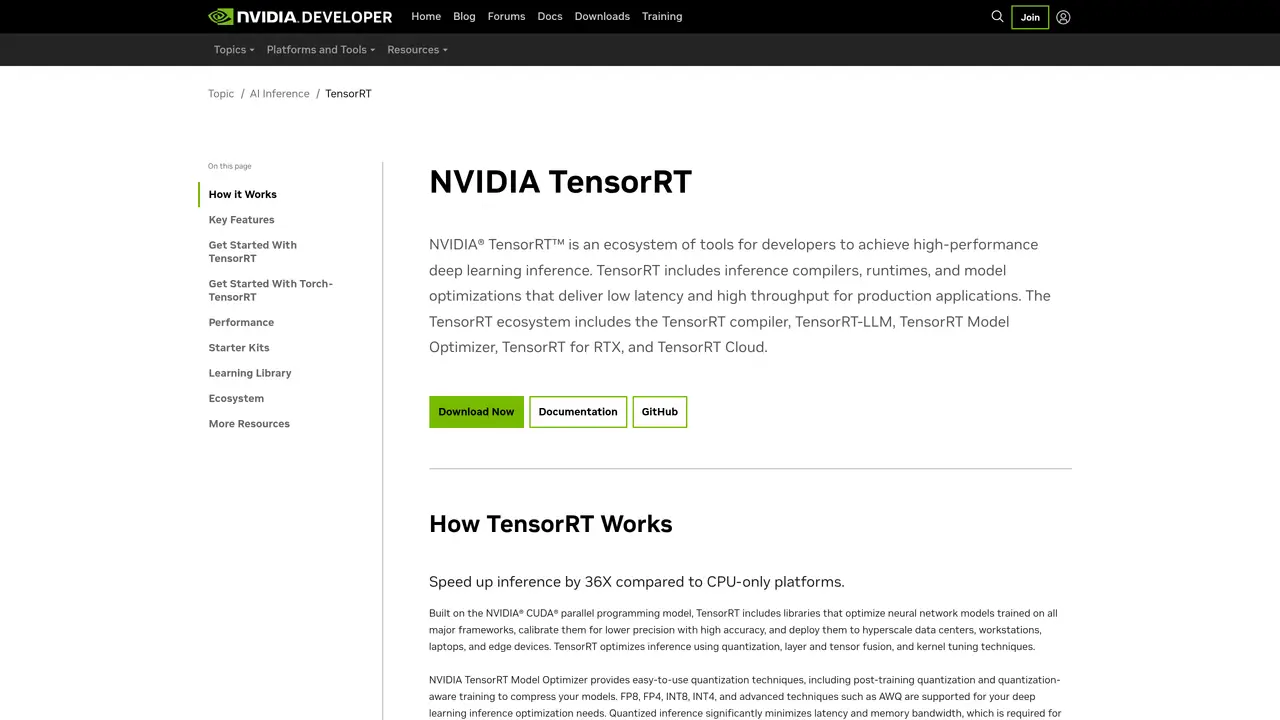
NVIDIA TensorRT is an AI-acceleration platform that provides maximum performance and fast inference times for deep learning applications. It is a high-performance deep learning inference optimizer and runtime for production deployment of AI models. With NVIDIA TensorRT, you can quickly optimize and deploy trained neural networks in production environments, enabling faster and more accurate inference. NVIDIA TensorRT enables developers to optimize, validate, and deploy trained deep learning models in production environments with dramatically higher inference performance. It features highly optimized graph optimizations, such as layer fusion, kernel auto-tuning, and half-precision FP16 support, to accelerate model inference by up to 100x compared to CPU-only platforms. Additionally, it offers built-in support for NVIDIA GPUs, and works with popular deep learning frameworks such as TensorFlow and PyTorch. NVIDIA TensorRT is ideal for developers and data scientists who need to quickly optimize and deploy trained deep learning models in production environments.
Nvidia
Santa Clara, United States · Founded 1993
- Founders
- Jensen Huang, Chris Malachowsky, Curtis Priem
- Founded
- 1993
- Headquarters
- Santa Clara, United States
- Legal status
- Public company
Key features
- Accelerate inference speeds up to 100x
- Optimize, validate, and deploy trained deep learning models quickly
- Compatible with popular deep learning frameworks like TensorFlow and PyTorch
- Highly optimized graph optimizations for faster model inference
- Built-in support for NVIDIA GPUs
- Supports half-precision FP16 for improved performance
Use cases
- Optimizing and deploying trained neural networks in production environments
- Accelerating deep learning model inference by up to 100x compared to CPU-only platforms
- Enabling faster and more accurate inference in AI applications
Pros
- Delivers high-performance deep learning inference with low latency and high throughput for production applications
- Supports a wide range of optimization techniques including quantization, layer fusion, kernel tuning, pruning, and distillation
- Integrates with major deep learning frameworks such as TensorFlow, PyTorch, ONNX, and Hugging Face
- Provides specialized tools like TensorRT-LLM for large language model inference and TensorRT Cloud for cloud-based engine optimization
- Enables deployment across diverse platforms including edge devices, workstations, data centers, and embedded systems
Cons
- Requires NVIDIA GPU hardware for optimal performance, limiting compatibility with non-NVIDIA platforms
- TensorRT Cloud access is limited and subject to approval, restricting availability for some users
- Complexity in setup and optimization may pose challenges for developers without deep learning expertise
NVIDIA TensorRT videos
Frequently asked questions about NVIDIA TensorRT
What is NVIDIA TensorRT?
NVIDIA TensorRT is an ecosystem of tools designed for high-performance deep learning inference, including compilers, runtimes, and model optimizations. It accelerates neural network inference across data centers, workstations, laptops, and edge devices using techniques like quantization, layer fusion, and kernel tuning.
Who should use NVIDIA TensorRT?
TensorRT is ideal for developers, data scientists, and enterprises deploying AI models in production environments requiring low latency and high throughput. It supports applications across edge devices, autonomous systems, and hyperscale data centers.
How does NVIDIA TensorRT optimize models?
TensorRT optimizes models through quantization (FP8, INT8, INT4), layer and tensor fusion, kernel tuning, and advanced techniques like AWQ. It also supports pruning, distillation, and speculative decoding for further performance gains.
What frameworks does NVIDIA TensorRT integrate with?
TensorRT integrates with major frameworks such as PyTorch, TensorFlow, Hugging Face, ONNX, and MATLAB. It also works with NVIDIA-specific SDKs like NVIDIA NIM, DeepStream, and Riva for specialized applications.
Can NVIDIA TensorRT be used for large language models (LLMs)?
Yes, TensorRT-LLM is an open-source library within the TensorRT ecosystem that accelerates and optimizes LLM inference on NVIDIA GPUs. It provides a simplified Python API for deploying LLMs in data centers or workstation environments.
How do I get started with NVIDIA TensorRT?
Start by downloading the TensorRT SDK from the NVIDIA Developer website, then explore the developer guide for step-by-step instructions. TensorRT offers APIs and tools tailored to different deployment needs, including cloud-based optimization via TensorRT Cloud.