GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.

WIT by Google AI
$0.07Starting price
0Popularity
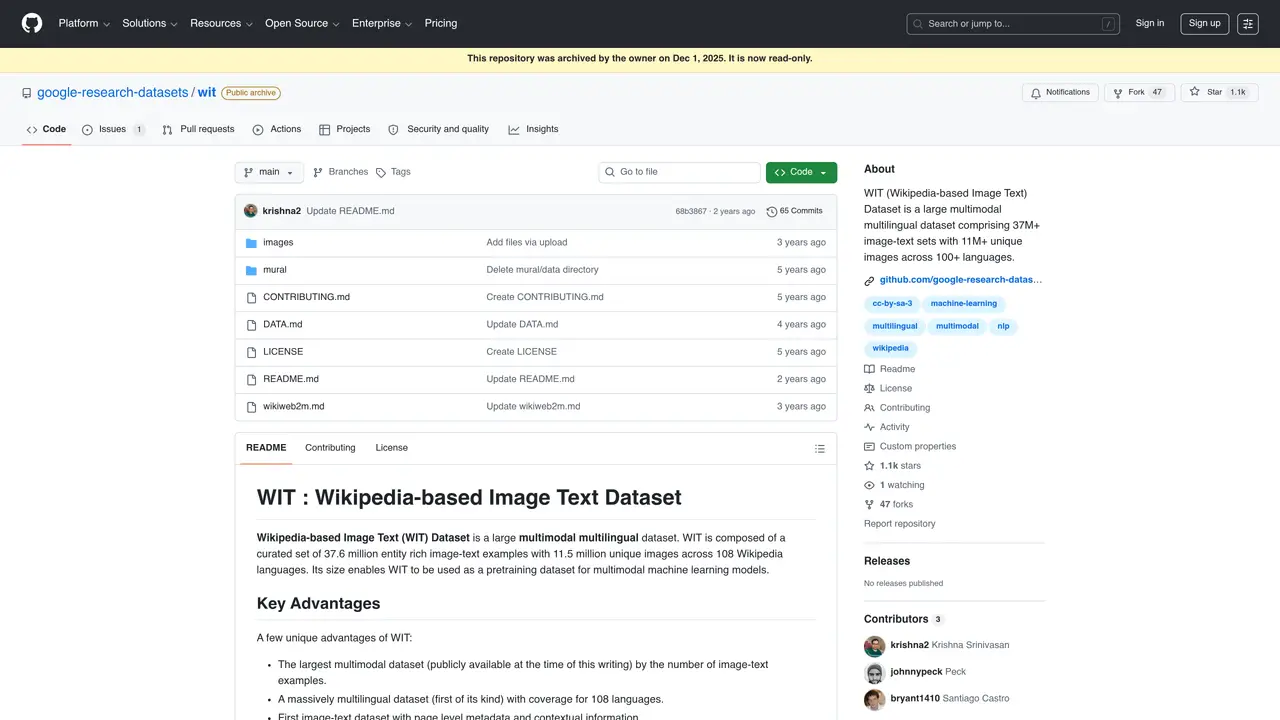
About WIT by Google AI
WIT by Google AI is an AI-powered platform that helps developers quickly and easily build intuitive and powerful conversational interfaces. With WIT, users can create natural language processing (NLP) models in minutes and deploy them in their apps. WIT’s cutting-edge AI technology can interpret language and recognize intent, allowing developers to quickly create AI-powered solutions that are easy to use and understand. WIT’s intuitive interface and advanced AI capabilities make it ideal for developers looking to create conversational interfaces that are powerful, yet easy to use and understand. WIT provides developers with the tools they need to build sophisticated conversational interfaces that are tailored to their target audience’s needs. With WIT, developers can quickly create AI-powered solutions that interact with users in a natural, conversational way.
GitHub, Inc.
San Francisco, California, US · Founded 2008
- Founders
- Tom Preston-Werner, Chris Wanstrath, PJ Hyett, Scott Chacon
- Founded
- 2008
- Headquarters
- San Francisco, California, US
- Legal status
- Subsidiary of Microsoft (NASDAQ: MSFT)
Key features
- Create NLP models in minutes
- Interpret language and recognize intent
- Build powerful and intuitive conversational interfaces
- Tailor interfaces to user needs
- Deploy NLP models in apps
- Use cutting-edge AI technology
Use cases
- Building conversational interfaces for customer service chatbots
- Creating AI-powered virtual assistants
- Developing natural language processing applications
Pros
- Largest publicly available multimodal dataset with 37.6 million image-text examples
- Massively multilingual coverage across 108 languages
- Includes page-level metadata and contextual information for richer data interpretation
- Diverse collection of real-world entities and challenging test sets for robust model training
- Enables pretraining for multimodal machine learning models due to its scale and quality
Cons
- Dataset is archived and read-only, limiting future updates or expansions
- Requires technical expertise to process and integrate into custom applications
- No direct support or maintenance provided due to archival status
Frequently asked questions about WIT by Google AI
What is the WIT dataset?
WIT (Wikipedia-based Image Text) is a large multimodal multilingual dataset comprising over 37 million image-text examples with 11 million unique images across 108 languages. It includes page-level metadata and contextual information for each image-text pair.
Who should use the WIT dataset?
The WIT dataset is designed for researchers and developers working on multimodal machine learning models, particularly those focused on vision-language tasks such as image-text retrieval, captioning, or visual question answering.
How can the WIT dataset be used in machine learning?
WIT can be used as a pretraining dataset for multimodal models to improve their understanding of the relationship between images and text, especially in multilingual contexts where existing datasets are limited.
Is the WIT dataset publicly available?
Yes, the WIT dataset is publicly available and can be accessed via its GitHub repository. It has also been used in academic research and competitions, such as the WIT Image-Text Competition on Kaggle.
What makes the WIT dataset unique?
WIT stands out due to its massive scale, multilingual coverage, and inclusion of page-level metadata and contextual information, which are not typically found in other image-text datasets.
Are there any additional resources or tools associated with WIT?
Yes, the WIT dataset has been used to create related datasets like WikiWeb2M, and there are authoring tools for multimedia content that leverage WIT for relevance annotations and accessibility research.