GitHub hosts HunyuanVideo, Tencent's open-source framework for large-scale video generation models, enabling AI-driven video creation.

XLM
$0.07Starting price
0Popularity
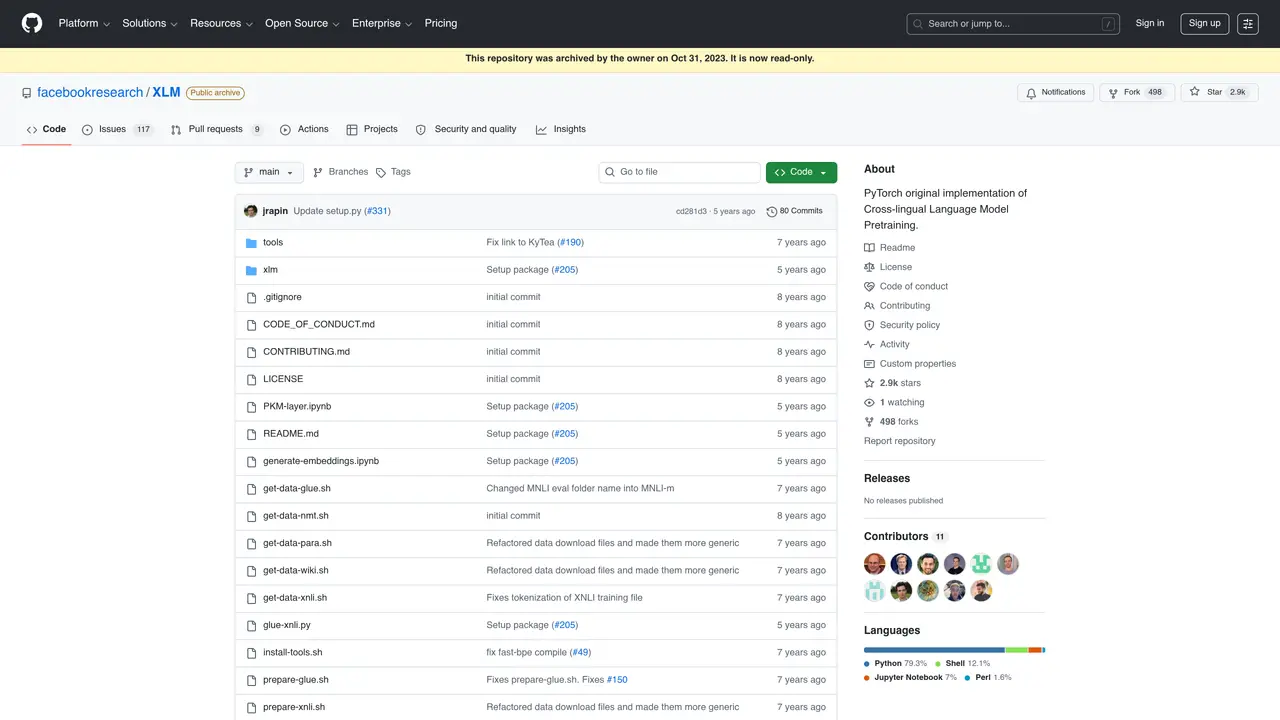
About XLM
XLM is a powerful and versatile natural language processing (NLP) framework developed by Facebook Research. It enables users to easily train, evaluate and deploy state-of-the-art models for a wide range of tasks such as machine translation, text classification and sentiment analysis. This framework is designed to be highly extensible and easily integrated into existing machine learning pipelines.The core features of XLM include a wide range of pretrained models, a highly optimized training pipeline and easy-to-use APIs. It also provides an extensive set of tools for building, training and evaluating models on various datasets. With XLM, users can quickly fine-tune their models on any dataset or task, and achieve impressive results.XLM is an ideal choice for researchers, engineers and data scientists who need an efficient and reliable NLP framework for their projects. With its extensive feature set, users can quickly and easily build, train and evaluate their models with minimal effort.
GitHub, Inc.
San Francisco, California, US · Founded 2008
- Founders
- Tom Preston-Werner, Chris Wanstrath, PJ Hyett, Scott Chacon
- Founded
- 2008
- Headquarters
- San Francisco, California, US
- Legal status
- Subsidiary of Microsoft (NASDAQ: MSFT)
Key features
- Pre-train models
- Easy integration into existing machine learning pipelines
- Highly optimized training pipeline
- Easy-to-use APIs
- Extensive set of tools for building, training and evaluating models
- Supports a wide range of tasks including machine translation, text classification and sentiment analysis
Use cases
- Machine translation
- Text classification
- Sentiment analysis
Pros
- Supports cross-lingual and monolingual language model pretraining with multiple objectives (MLM, CLM, TLM)
- Includes pretrained models for English and multilingual tasks, with demonstrated performance improvements over BERT on GLUE benchmarks
- Provides tools for supervised and unsupervised machine translation, cross-lingual text classification, and fine-tuning on tasks like XNLI and GLUE
- Designed for multi-GPU and multi-node training, enabling scalable model training
- Offers flexibility through modular components such as Product-Key Memory (PKM) layers and BPE tokenization support
Cons
- Repository is archived and read-only as of October 31, 2023, indicating limited ongoing maintenance or updates
- Requires familiarity with PyTorch and command-line tools for installation and data preprocessing
- Dependencies like fastBPE and Apex may introduce complexity in setup and compatibility issues
Frequently asked questions about XLM
What is XLM and what does it do?
XLM is a PyTorch-based framework for cross-lingual language model pretraining, developed by Facebook Research. It supports monolingual and cross-lingual pretraining, including models like BERT, and is designed for tasks such as machine translation, text classification, and sentiment analysis.
Who is XLM suitable for?
XLM is ideal for researchers, engineers, and data scientists working on multilingual NLP tasks. It is particularly useful for those needing cross-lingual capabilities, such as supervised or unsupervised machine translation and cross-lingual text classification.
How do I get started with XLM?
To get started, install the Python package in editable mode using 'pip install -e .'. Ensure dependencies like PyTorch, NumPy, and fastBPE are installed. The repository provides scripts for data preparation, pretraining, and fine-tuning, along with example notebooks for demonstration.
Does XLM support multi-GPU and multi-node training?
Yes, XLM supports both multi-GPU and multi-node training, making it scalable for large datasets and complex models. The framework includes code for distributed training setups.
What tasks can I perform with XLM?
XLM supports tasks such as monolingual language model pretraining (e.g., BERT), cross-lingual language model pretraining (XLM), supervised or unsupervised machine translation, cross-lingual text classification (e.g., XNLI), and fine-tuning on GLUE benchmarks.
Are there pretrained models available in XLM?
Yes, XLM provides pretrained models, including an English-only BERT model trained with the MLM objective. The repository also includes BPE codes and vocabulary files for various languages to facilitate pretraining and fine-tuning.